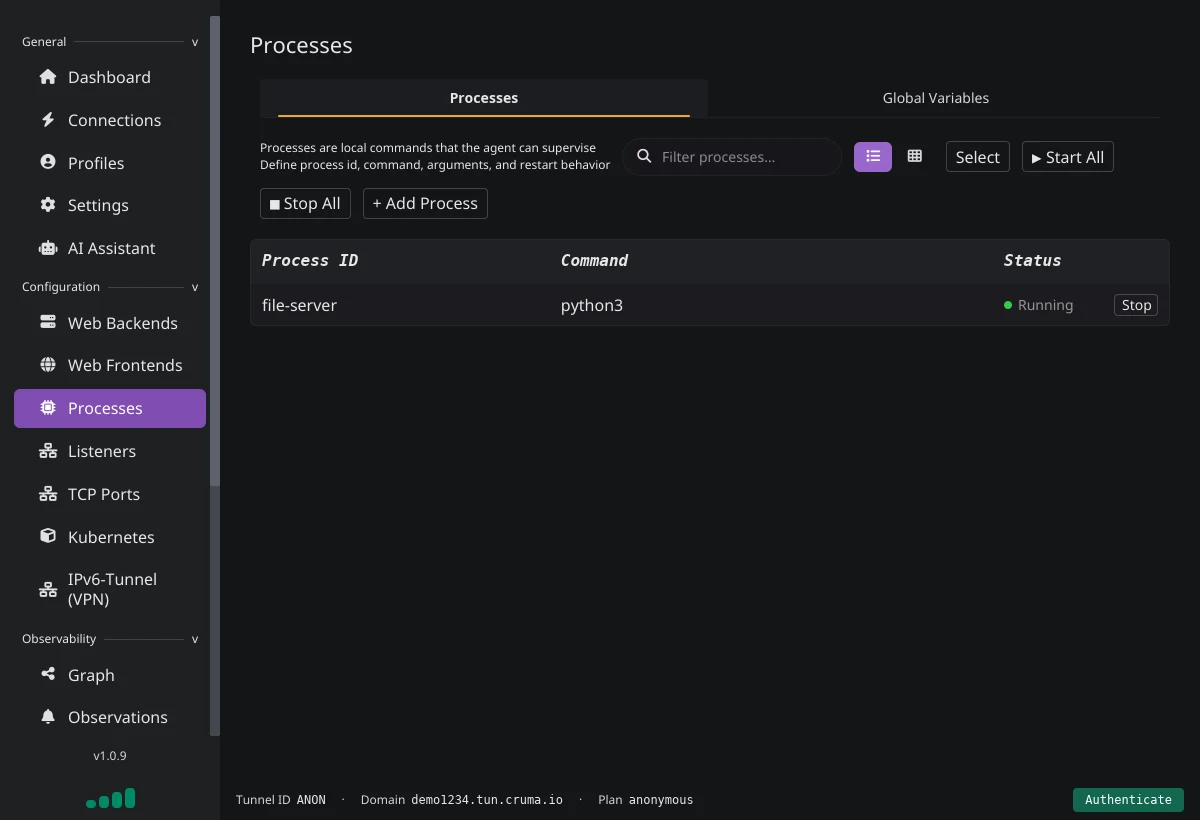
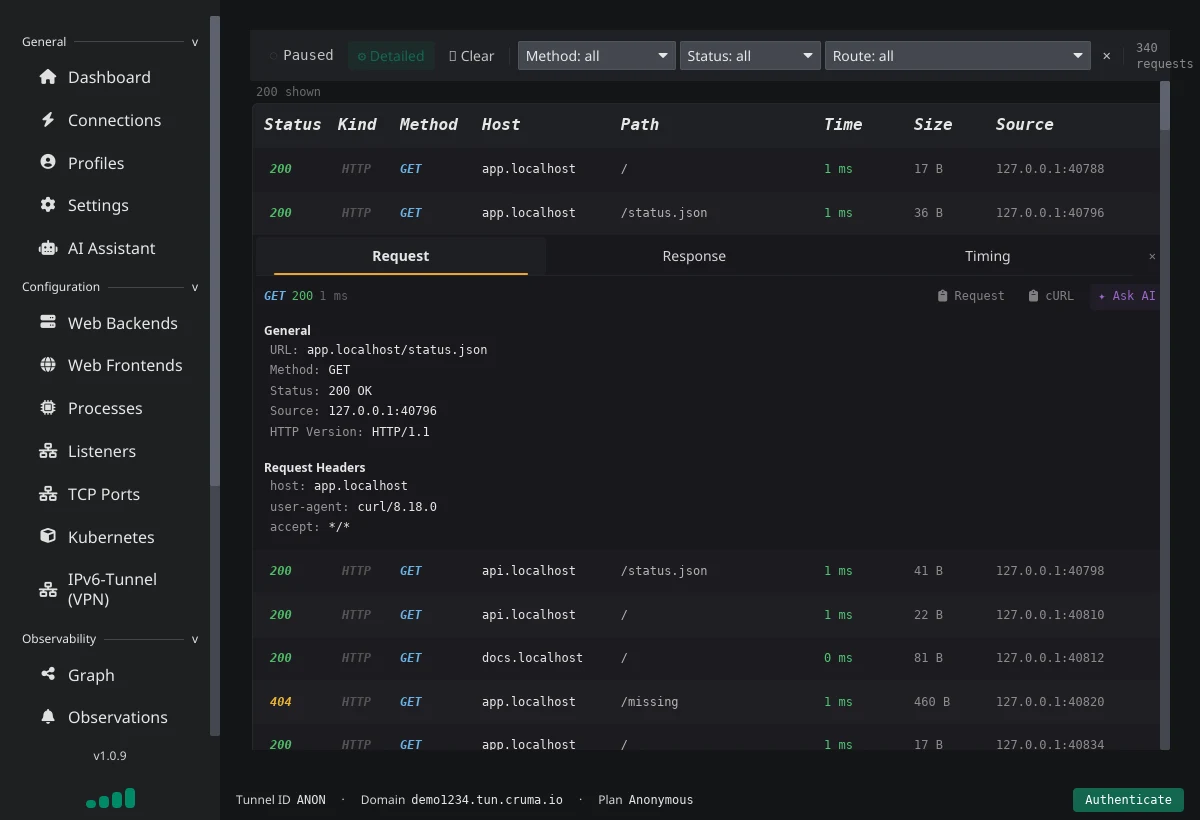
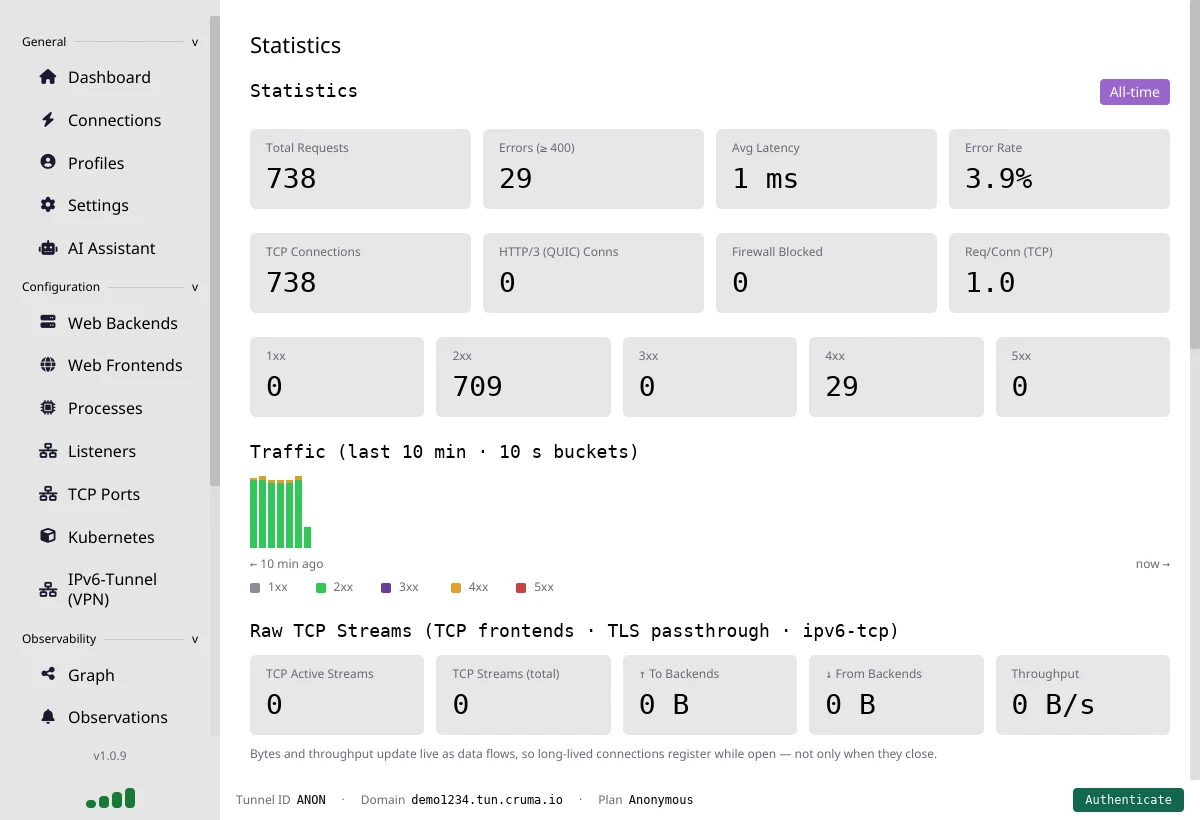
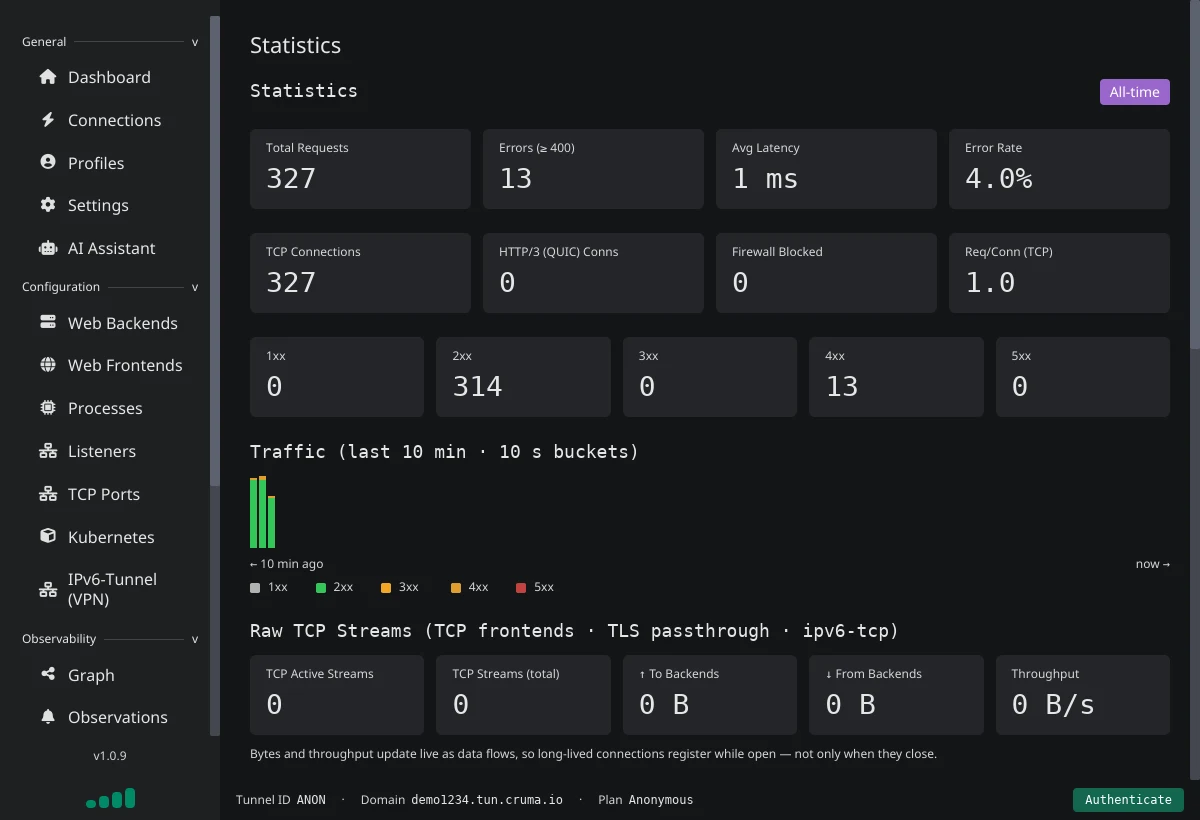
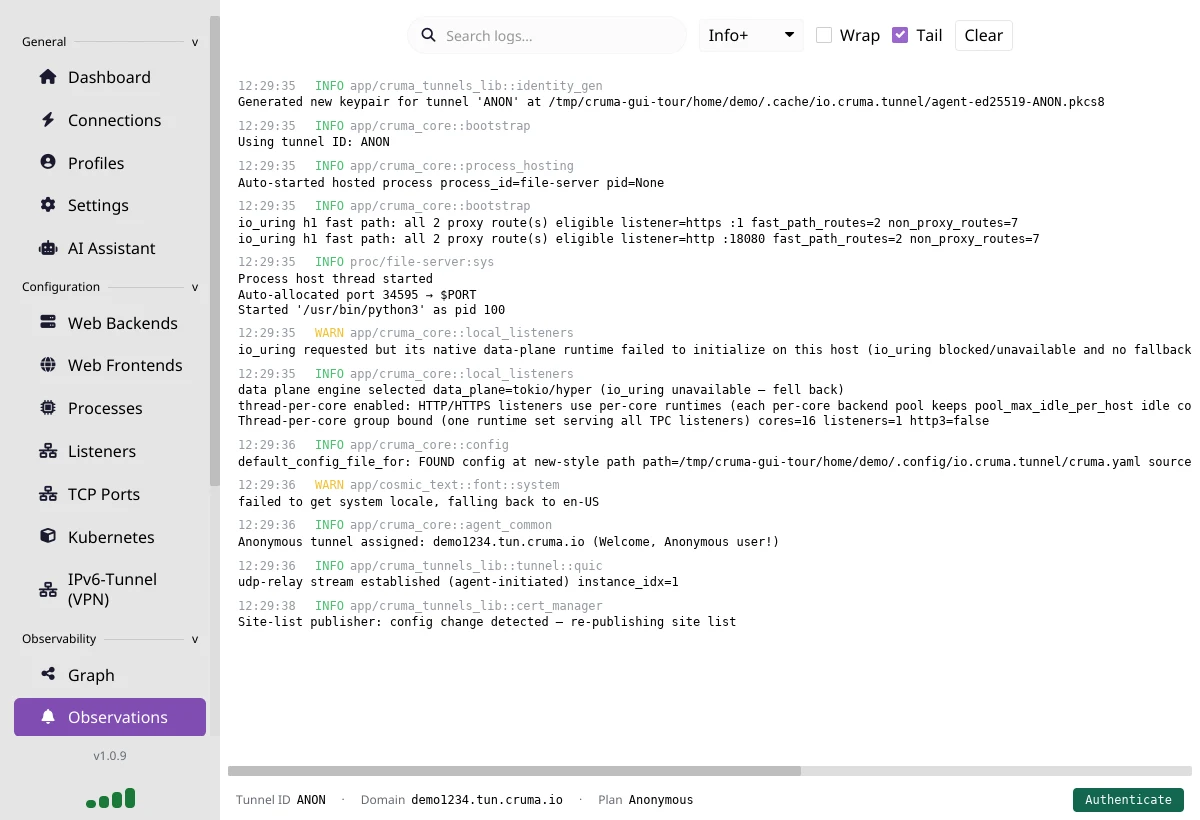
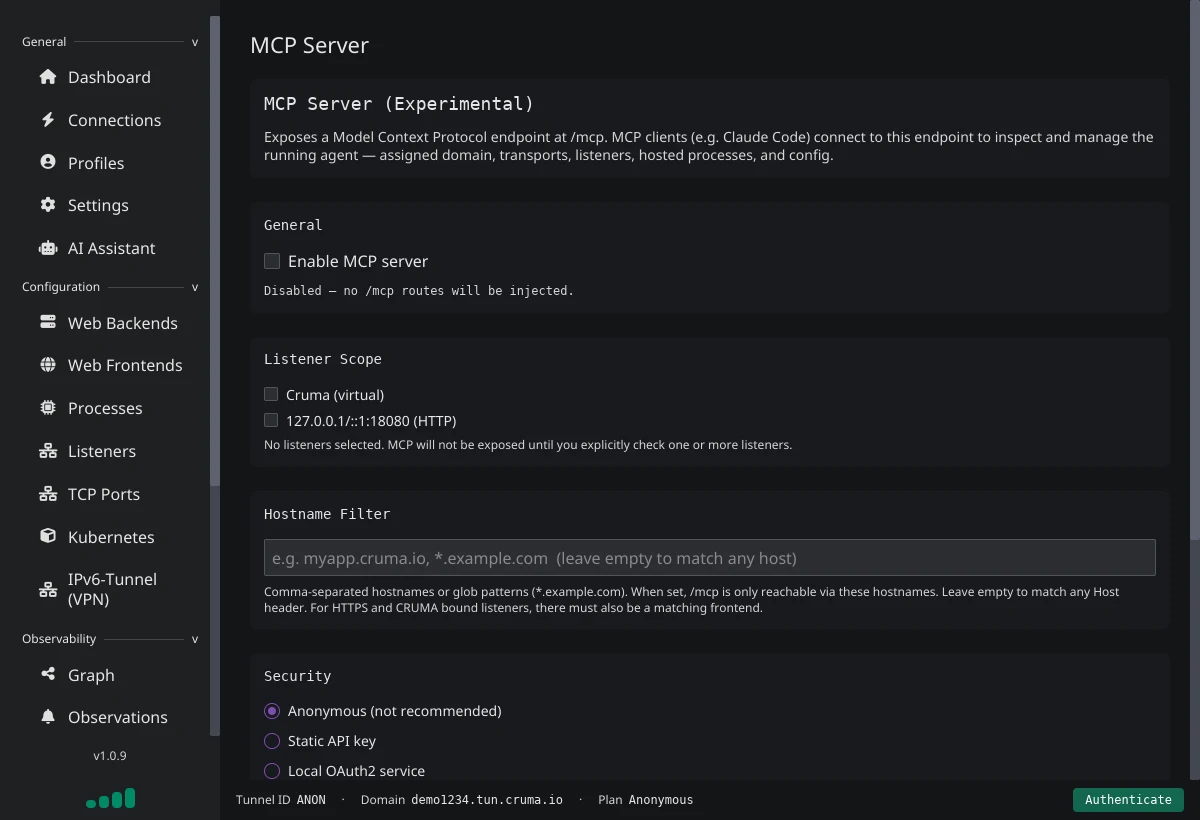
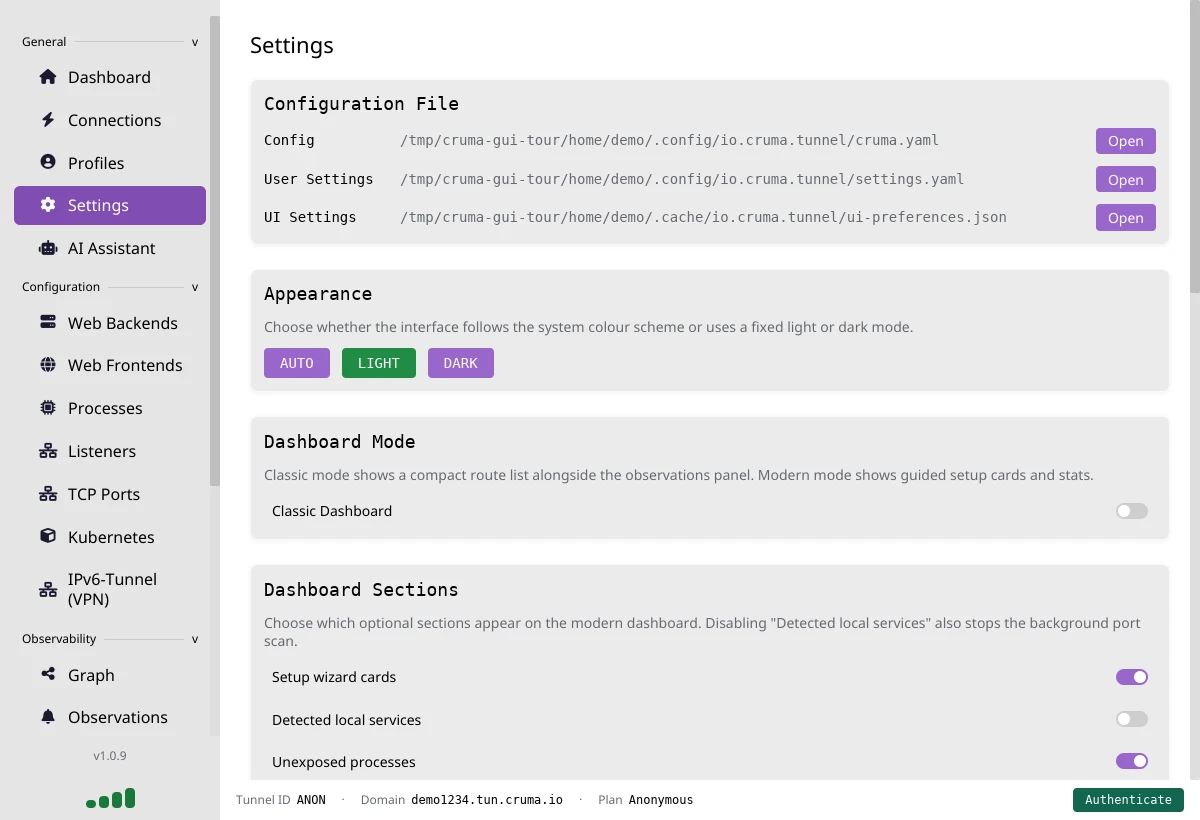
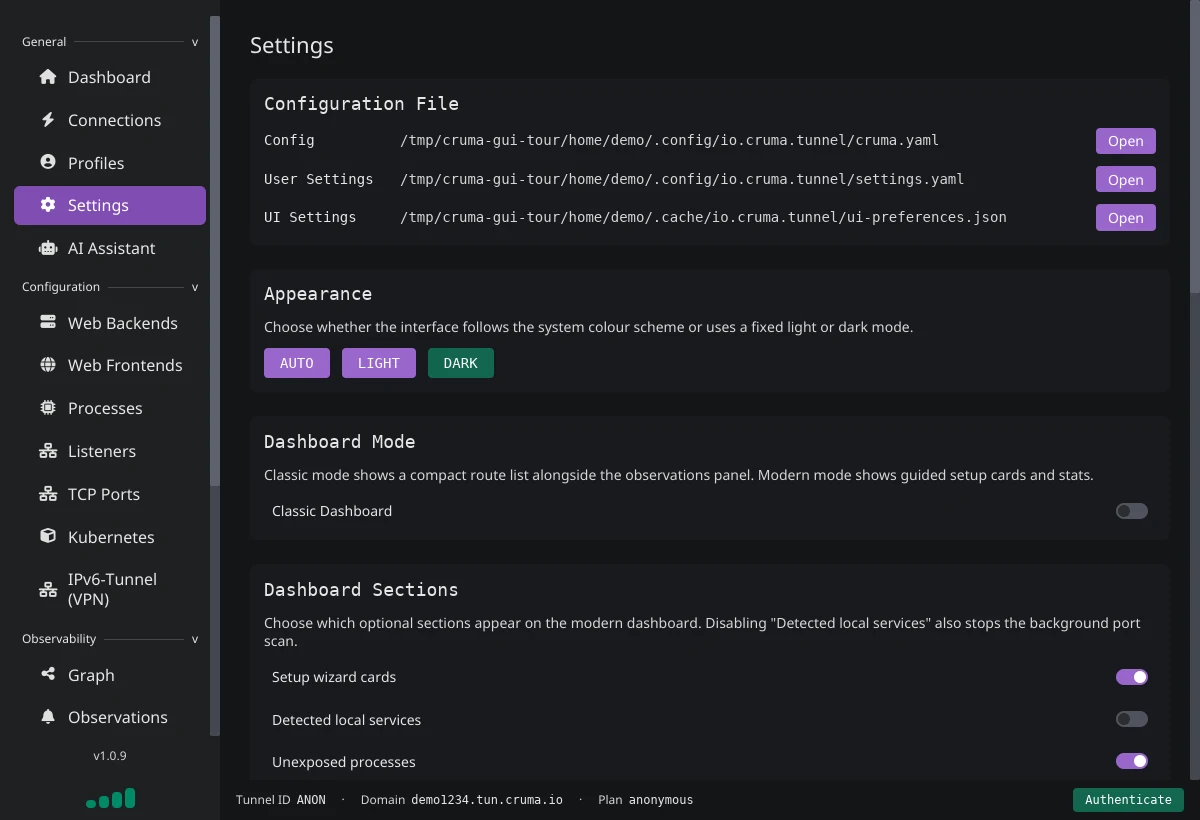
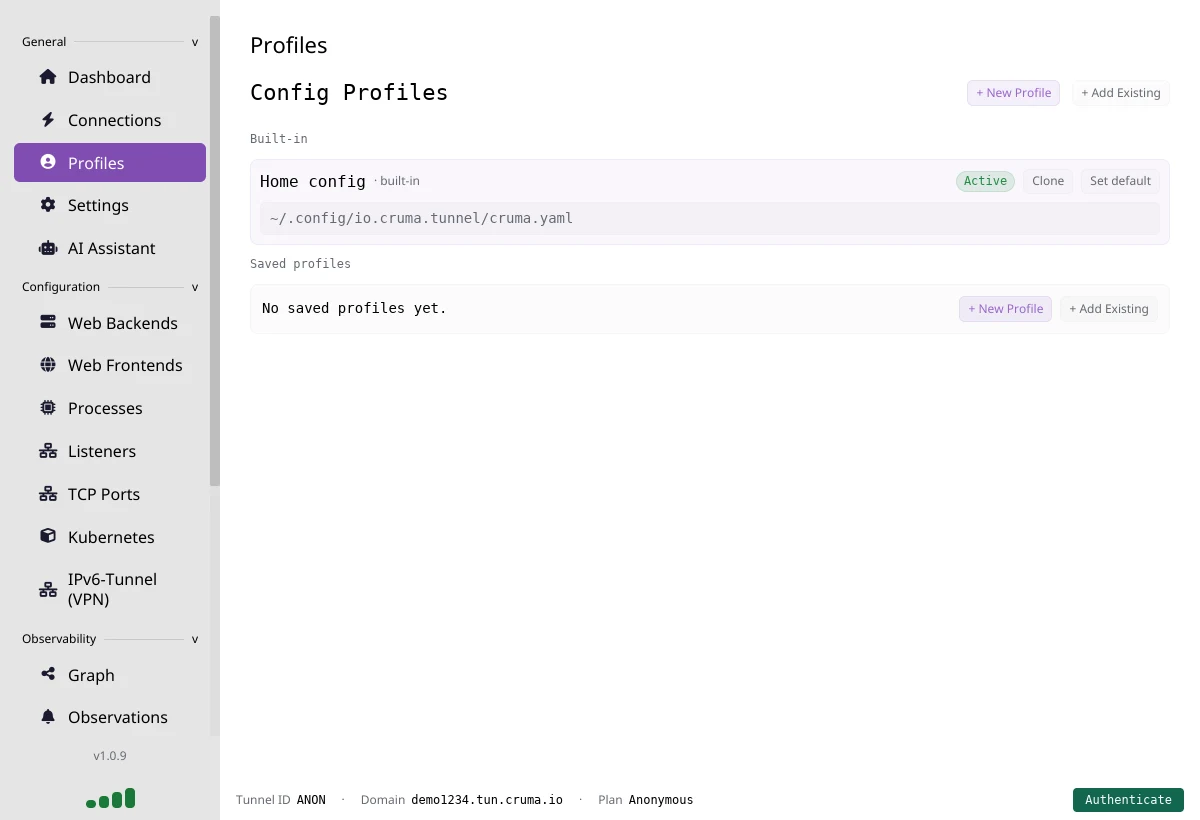
Cruma gives anything running on your machine a public HTTPS URL — from a quick CLI tunnel to a full desktop app with request inspection. Free for personal dev, with paid tiers for custom domains, end-to-end encryption, and built-in authentication. It also functions as a capable web and proxy-server with many built-in features for all your developer needs, entirely free.
Free tunnels for quick testing, paid tunnels for custom domains, stronger privacy, and consistent performance. Free is for individual, non-commercial development use — not company-wide rollout.
Anonymous$0no signup
Disposable quick tunnels
Best for trying Cruma fast or sharing a localhost app for a short test.
Cruma is a focused tunnel for developers, small teams, and homelabs. We optimize for fast setup, local-first tooling, and privacy options rather than enterprise policy suites. High-level comparison with Cloudflare Tunnel and ngrok based on publicly documented features.
Legend✓ Available~ Limited / extra config$ Paid plans× Not available
Feature
Cruma
Cloudflare Tunnels
ngrok
Account-free quick tunnels
✓ Yes — anonymous mode for quick tunnels without an account. Aggressively rate-limited for fair usage.
✓ Yes — supported via "Quick Tunnels" at trycloudflare.com. Aggressively rate-limited; relaxed with a free account.
× No — requires an account and auth token.
Custom domains with E2E encryption
$ Yes (subscribed) — create a CNAME to your tunnel's domain; the agent terminates TLS locally and forwards to your app. Requires a paid subscription.
× No (for E2E) — custom domains supported, but HTTP(S) terminates at Cloudflare's edge, so plaintext is visible at that point.
$ Paid — custom domains on paid plans.
Multi-endpoint
✓ Yes — serve any number of endpoints using different hostnames.
✓ Yes — serve any number of endpoints using different hostnames.
$ Paid — multiple endpoints on paid plans only.
Protocol forwarding
~ TCP — TCP forwarding today; UDP is on the roadmap.
~ TCP — ngrok's public service currently supports TCP forwarding.
Agent uplink protocols
✓ QUIC + HTTP/2 — agents keep TLS-encrypted QUIC and HTTP/2 sessions for lower latency and resilience.
✓ QUIC + HTTP/2 — cloudflared can use QUIC uplinks and HTTP/2 over TLS in supported configs.
~ HTTP/2 — speaks HTTP/2 to its control plane; no public QUIC uplink.
Local UX & tooling
✓ TUI + desktop app — desktop app for config and request inspection, plus a terminal TUI. Headless mode available.
~ CLI + hosted dashboard — configured via CLI and Zero Trust dashboards; no full local web UI.
~ CLI + remote inspector — request inspector and many options live in the cloud dashboard.
HTTP request inspection
✓ Local UI — inspect in the TUI and desktop app; request logs never leave your machine.
~ Zero Trust dashboards — routes through Cloudflare's edge, so logs live in their SaaS; no local inspector.
× Remote-only — primary inspector UI runs in their cloud dashboard.
Serve local directories
✓ Built-in directory server — serve a local directory straight from the agent, no nginx needed.
× No built-in static server — run your own web server or use Cloudflare Pages.
× No built-in static server — run a local server yourself and point ngrok at it.
Built-in access controls
✓ IP allow-lists, forms & API keys — allow-list source IPs per tunnel, or put form auth / header API-key enforcement in front of any HTTP backend.
~ Via Zero Trust policies — HTTP access control via Cloudflare Access, managed in their SaaS control plane.
$ Paid — access control and traffic-shaping on paid plans.
End-to-end encryption
✓ Supported (subscribed) — TLS terminates on the agent as soon as a cert is generated, so Cruma only sees encrypted payloads. TLS passthrough also supported.
× Not provider-blind — for standard HTTP(S) tunnels, TLS terminates at Cloudflare's edge, so plaintext is visible there.
This policy explains what cruma.io and the Cruma app collect, why, and how to
turn it off. Questions and requests go to
[email protected].
What we collect, and why
We run our own product analytics so we can see how visitors move from the
website to a download, to the first launch of the app, and to a first tunnel
connection. On the website this works without cookies: our analytics store
nothing in your browser.
On our websites and downloads
When you view a page on cruma.io, click one of its download links, download a
file from files.cruma.io, or the app checks for updates or connects to our tunnel service, we log:
A visit ID. A random value your browser creates for each page view. It is
never stored on your device, so it cannot recognise you on your next visit.
Links from cruma.io to downloads and the dashboard carry it, so we can tie a
download to the page view it came from.
A hashed IP address. We hash your IP address with a salt that changes
every day. The salt is deleted after 48 hours, and after that the hash can no
longer be linked back to an IP address. We never store the raw IP address.
Country, when our CDN provides it.
Browser and operating system family (for example "Firefox" or "macOS"), not
the full user-agent string.
The referrer, meaning the site that sent you here, plus any campaign tags
(utm_*, and oppref if you arrived from one of our ads) in the URL.
The page, file or endpoint involved, and the time. For a click on a download
link, the platform you picked and whether it was an app store link.
In the Cruma app
When the app checks for updates, and when it connects to our tunnel service, it
sends:
its version, operating system, CPU architecture, release channel, and whether
it is the desktop or command-line build;
a random install ID. It is created the first time the app runs and saved in
the app's cache folder. It is not derived from your hardware, your account or
your tunnels. Deleting the cache folder creates a new one.
a flag on the very first launch.
To turn the install ID off, switch off telemetry in the app's settings
(settings.yaml), or set the environment variable CRUMA_NO_TELEMETRY=1. With
either one set, the app sends only its version and platform, with no install ID
or first-launch flag. Update checks keep working.
Legal basis
We process this data on the basis of our legitimate interest (GDPR
Article 6(1)(f)) in understanding how people find, install and start using
Cruma, so we can improve it. The data is pseudonymous, used only for our own
analytics, and never sold or used to build advertising profiles.
Retention
The daily IP salt is deleted after 48 hours, which makes older IP hashes
unlinkable.
Raw analytics events are kept for at most 13 months, and are then deleted or
reduced to aggregate counts.
Advertising (only with your consent)
We advertise Cruma, and we want to know which ads lead to a download. If you
accept in the banner on cruma.io, we measure that with our ad partner. If
you decline, none of this happens.
Our ad partners. Currently one: OpenAI (OpenAI Ads), which processes data
in the United States. If we add a partner, this list changes and we ask you
again.
What is shared, once you accept:
From your browser: the OpenAI Ads pixel is loaded on cruma.io. It sets
first-party cookies on cruma.io (__oppref, __obref, plus a test cookie
__oaiq_domain_probe it deletes straight away) and sends OpenAI the
page you viewed, your IP address and browser details, together with the
identifiers in those cookies. Until you accept, your browser makes no request
to OpenAI.
From our servers: when you download or start Cruma, we may report that
event (for example "app started") to OpenAI's Conversions API, together with
the oppref ad-click ID from the link you arrived on, so OpenAI can tell which
ad it came from. Links from cruma.io to downloads and the dashboard carry
ads=1 only after you accept, and we send these server-side events only for
visits that carry it. Without your consent we send nothing.
What cruma.io stores on your device.
Always, because the site needs it (no consent asked): your theme
preference in local storage (pm-theme…). cruma.io sets no cookie of its own.
After you make a choice in the banner: your consent choice in local
storage (cruma-consent), so we don't ask again.
Only after you accept ad measurement: the ad partner's cookies on cruma.io
(__obref, and __oppref when you arrive from an ad), a short-lived test
cookie (__oaiq_domain_probe) that the partner's script deletes straight
away, and a session-storage entry (oaiq_cs:…). OpenAI's own servers may also set their own cookies on
their own domains.
When you withdraw ("Privacy choices", then Decline): the ad partner's
cookies and storage are removed from cruma.io and we stop sharing.
Withdrawing consent is as easy as giving it: use the Privacy choices link
in the footer of every page (or the button below), then choose Decline. We
then stop sharing for future visits, delete the cookies and storage the pixel set on cruma.io, and reload
the page without the pixel. Data already sent to OpenAI stays with OpenAI under
its own policy, and you can ask them to delete it.
Your rights
You can ask for access to, correction of, or deletion of your personal data,
and you can object to processing based on legitimate interest. Because we only
keep pseudonymous data, we may need details from you, such as your install ID,
to find your records. Write to [email protected]. You can
also complain to the Swedish Authority for Privacy Protection (IMY).
Cruma Pages
Cruma Sites turns a Git repository of Markdown into a fast, self-contained
website that Cruma builds and hosts for you. You write content; Cruma bakes it
into a single, themed, searchable page and serves it at a Cruma subdomain (or
your own custom domain).
It also happens to be how this website (cruma.io) is created and hosted!
Point Cruma at a Git repo. From the dashboard, connect a public repo — or
a private one via the GitHub App. The repo holds your content/ and a
site.toml; nothing else is required.
Cruma builds it. On every push, Cruma clones the repo, runs the generator,
and publishes the result. There's no build step for you to run and no
framework to configure.
It's served live. Your site appears at <your-site>.pages.cruma.io, and
you can attach a verified custom domain.
What a site looks like
A Cruma site is just a folder:
my-site/
  site.toml            # site-level settings (title, theme, …)
  content/
    home.md            # a page
    not-found.md       # the 404 page
    images/            # images, served from /images/<name>
    _components/       # reusable HTML components (optional)
    _themes/           # custom themes (optional)
    book/              # documentation books (optional)
    blog/              # dated posts (optional)
The only truly required pieces are site.toml and a content/ directory with
at least a home.md. Everything else is opt-in.
The rest of this book covers each piece in turn:
Content & pages — pages, front matter, and
how to link between them.
Everything under content/ becomes part of your site. There are a few special
kinds of content, distinguished by where the file lives.
Pages
A content/*.md file is a page. Pages are hash-routed (#home, #pricing)
and share the site's chrome. Optional front matter at the top of the file controls
how the page appears:
---
slug: pricing      # the #hash / tab id      (default: file name)
title: Pricing     # nav + tab label         (omit to hide from the nav)
order: 2           # nav order               (default: 1000)
layout: splash     # page shape              (default: content)
---

# Pricing

Your Markdown here…
The Markdown is CommonMark plus tables and strikethrough, and raw HTML passes
through — so you can drop in a <div> or a component
wherever you need one.
Front matter reference
Every field is optional. The common ones:
Key
What it does
slug
The page's #hash id. Defaults to the file name without .md.
title
Nav/tab label. Omit it to keep the page off the nav (still reachable by its slug).
order
Position in the nav; lower comes first (default 1000).
layout
content (a carded article, the default) or splash (a full-bleed landing page with no card).
eyebrow
A small kicker line shown above the first heading.
hidden: true
Drop the page from the nav and search (used by not-found.md).
chrome: off
Hide the top bar while this page is active — for pages that bring their own nav/footer.
on renders every top-level list on the page as feature cards (default off).
Pages also accept the per-page banner keys (image, header-mode, header-fade, …)
covered in Banners & headers, and blog metadata (date,
authors, description) covered in Books & blog.
Linking between pages
Links are plain Markdown. What you put in the target decides where it goes:
[Pricing](#pricing)                        <!-- another page, by its slug -->
[Introduction](#cruma-pages/introduction)  <!-- a book chapter: #<book>/<chapter> -->
[Latest release](#blog/v2-launch)          <!-- a blog post: #blog/<slug> -->
[All posts](#blog)                         <!-- the blog index -->
[Cruma](https://cruma.io)                  <!-- an external link, opened as-is -->
To a page — use its slug: [text](#slug).
To a book chapter — use #<book-folder>/<chapter-slug> (the folder name,
then the chapter's slug). Ordering prefixes like 01- are dropped from slugs,
so content/book/guide/02-setup.md is #guide/setup.
To a blog post — #blog/<post-slug>; the index itself is #blog.
To a heading on the current page — headings get an automatic id from their
text, so [Front matter](#front-matter-reference) scrolls to that section.
External — any http(s)://, root-absolute /…, or mailto: link is left
untouched and opens normally.
Inside a book, you can also link to a sibling chapter with a relative
Markdown path and Cruma rewrites it to the right hash for you:
See [Themes](07-themes.md) for the full list. <!-- → #cruma-pages/themes -->
Only relative *.md links are rewritten; everything else passes through as
written.
Lists as cards
Some themes (like the Cruma and Tako themes) can render a bulleted or numbered
list as a grid of feature cards. This is opt-in — by default every list
renders as a normal list. To turn a single list into cards, put a <!-- cards -->
comment on the line right before it:
<!-- cards -->
- **Fast** — builds on every push
- **Secure** — HTTPS out of the box
- **Yours** — bring your own domain
To make every list on a page render as cards, set list-cards: on in the
page's front matter; a <!-- plain --> comment before a list opts that one back
out. Themes that don't style cards just show a normal list.
The 404 page
content/not-found.md is served for unknown paths. If you don't ship one, Cruma
provides a sensible default.
Images
Put images in content/images/ and reference them as images/<name>:

Cruma serves them from your site's asset store, so they stay fast and cached.
Keep the folder flat — one level, no subdirectories.
Search
Every site ships a search palette that indexes all pages, chapters and posts.
Readers open it from the … button in the top bar or with a keyboard
shortcut (Ctrl/⌘+K by default — change it with
search-key).
Books and blog
Two folders get special treatment — content/book/ for documentation books and
content/blog/ for dated posts. Both have their own chapter:
Books & blog.
Navigation & the top bar
The bar across the top of every page is built for you — from your pages, plus a
few site.toml keys when you want more control.
How the nav is built
Each top-level page with a title becomes a nav tab, ordered by its order
front matter (lowest first). To keep a page out of the nav, omit its title
(it stays reachable by its slug) or set hidden: true.
Books and the blog add their own entries — see
Books & blog. When there are more tabs than fit,
the rest collapse into the searchable … menu.
Books in the nav
By default each book gets its own tab. If you have several books, fold them into
a single Books menu:
books-nav = "folded" # one "Books" tab; default is "tabs" (a tab per book)
Books that share a _book.tomlcategory are grouped under one nav entry per
category (this documentation sits under Docs). See
Books & blog.
Brand
The top-left brand is the site title by default. Override it in site.toml:
title      = "Acme"              # browser tab + default brand text
brand      = "Acme Docs"         # brand text (overrides the title here)
brand-link = "#home"             # where the brand links (default: #home)
logo       = "images/logo.svg"   # a logo image instead of text
Use a #hash for brand-link to point at one of your own pages; an external
URL opens in a new tab.
External links & a call-to-action
Add links to other sites (docs, a status page, social) and one prominent
call-to-action button (Sign in, Get started, Book a demo…) to the top bar:
[[nav.links]]
label = "Docs"
url   = "https://docs.example.com"

[[nav.links]]
label   = "Changelog"
url     = "https://example.com/changelog"
new_tab = false            # optional; external links open in a new tab by default

[nav.cta]
label = "Sign in"
url   = "https://app.example.com/login"
style = "solid"            # solid | outline | plain
[[nav.links]] — repeat the block for each link. label and url are
required; new_tab defaults to true for external URLs.
[nav.cta] — a single button. style picks how much it stands out:
solid (filled with the theme's accent), outline, or plain (a plain link).
The colours come from the active theme, so the button
always looks native.
On a phone the call-to-action stays visible while the external links fold into
the … menu, so the bar never overflows.
Banners & headers
A banner is the wide image strip at the top of a page. You can set one for the
whole site, override it per page, or let a page take the header over entirely.
A site-wide banner
Set a default image (and optional tuning) in site.toml. It appears as a band at
the top of every page unless a page opts out:
banner          = "images/hero.jpg"   # the default header image
header-height   = "320px"             # band height (a CSS length)
header-position  = "center"           # focal point — any CSS background-position
header-blur     = "0"                 # blur radius (px); 0 = off
header-fade     = "0"                 # bottom fade height (px); 0 = off
header-position keeps the important part of a photo in frame on every screen
size — e.g. top, or 50% 20% to favour faces near the top.
To hide the banner on a single page, add banner: off to that page's front
matter.
A per-page banner
Give a page its own image with the image key, and tune it with the same
header-* controls (without the header- prefix as banner-* also works):
aligned — the image sits within the content measure, lined up with the
rest of the page.
full — the image runs edge-to-edge and the page's title sits over it.
A per-page image overrides the site-wide banner for that page; the two can also
coexist (a site band plus a page cover) depending on the theme.
Splash pages
For a landing page with no card and the header taking the whole hero, use the
splash layout together with a full header:
---
title: Home
slug: home
layout: splash
image: images/landing.jpg
header-mode: full
---

# Build docs your way
Spacing controls
Two more site.toml keys fine-tune the gap between the chrome and your content —
handy if a fixed top bar or a tall banner crowds the first line:
header-pad     = "110px"   # top padding for content that sits under a banner
nav-clearance  = "72px"    # gap below the floating nav on pages with no banner
Per-page front matter of the same names overrides these for a single page.
Books & blog
Two folders get special layouts: content/book/ for multi-chapter documentation
and content/blog/ for dated posts. This book you're reading is, itself, a book.
Books
A folder under content/book/ is a book. Each .md inside is a chapter,
rendered with a table-of-contents sidebar, a sub-section list, and prev/next
links.
content/book/guide/
  _book.toml          # book settings (optional but recommended)
  01-introduction.md
  02-setup.md
  03-configuration.md
Chapter front matter
A chapter is just a page in a book, so it takes the same front matter as any
page — title, order, image (a per-chapter
cover), eyebrow, banner: off, the header-* overrides, and so on.
Chapter order follows each chapter's order; without one, the 01-,
02- filename prefixes decide. Those prefixes are dropped from the slug, so
02-setup.md is reached at #guide/setup.
Titles come from title (or the file name).
_book.toml
The optional _book.toml names the book, places it in the nav, and sets
defaults for its chapters:
title       = "The Guide"      # the book's nav label + TOC heading
order       = 10               # position among top-level nav entries
category    = "Docs"           # group several books under one nav entry
description = "Set up and go." # blurb for the library card
image       = "images/guide.jpg"  # default banner for chapters that set none
banner      = "off"            # opt the book's chapters out of the site banner
# header-mode / header-fade / header-height / header-blur / header-position —
# book-level defaults, each overridable per chapter (see Banners & headers).
Books that share a category are collected under a single nav entry (labelled
with the category) with a small library index; a category with one book links
straight to it. Uncategorised books each get their own tab. image and the
header-* keys are inherited by every chapter that doesn't set its own — see
Banners & headers.
The table of contents
Every book has a TOC sidebar. Move or hide it site-wide in site.toml:
book-toc = "left" # left (default) | right | off
Blog
content/blog/ is an optional blog: one post per file, with an
auto-generated index sorted newest-first. Each post routes at #blog/<slug>.
---
title: v2 is here
date: 2026-07-11        # ISO YYYY-MM-DD; sorts newest-first
authors: [Ada Lovelace]
description: What changed in the 2.0 release.
image: images/v2-cover.jpg   # optional post cover
---

# v2 is here

Post body…
date is shown on the post and drives the index order.
description feeds the index card and link previews.
The generated index lives at #blog. To give it a title, position, or intro
text, add content/blog/_index.md:
---
title: Blog
order: 20
---

News and release notes from the team.
Custom components
Components are reusable HTML snippets you can drop into any page or chapter with a
{{name}} tag. They're how the Cruma marketing site builds its hero, pricing
cards, and comparison table without repeating markup.
Defining a component
Create content/_components/<name>.html. Inside it, use placeholders:
{{ attr }} — a named attribute, HTML-escaped.
{{ &attr }} — a named attribute inserted raw (already-safe HTML).
{{ body }} — the content between the opening and closing tags.
Invoke it from any Markdown file. Attributes are key="value" pairs; the content
goes between the tags:
{{callout tone="warn" title="Heads up"}}
Custom domains need a verified DNS record first.
{{/callout}}
When a component takes no body, self-close it:
{{callout tone="info" title="Note" /}}
Styling and behaviour
A component can bring its own CSS and JS: put them beside the template as
<name>.css and <name>.js in content/_components/. Cruma bundles them into
the page automatically, only when the component is actually used.
That's the whole system — plain HTML in, {{placeholders}} filled, scoped CSS/JS
attached. The cm-* components that build this very site are just a larger set of
the same thing.
Themes
A theme controls the whole look of a site — colours, typography, the top bar, and
the footer. Cruma ships several built-in themes, and you can add your own.
Choosing themes
List the themes you want in site.toml, active one first:
themes = ["cruma", "default", "kanagawa"]
The first theme is the default the site loads with.
Listing more than one adds a theme picker; listing a single theme drops the
picker and strips the others' CSS from the output.
This site uses a single cruma theme for a consistent, branded look.
Custom themes
Add a stylesheet at content/_themes/<name>.css and it becomes selectable like a
built-in one. A theme scopes its rules under html[data-theme="<name>"], so it
only applies while active:
content/_themes/<name>.footer.html — a site footer.
The cruma theme uses exactly this to render the CRUMA.IO brand bar and the
Umbra·Yurei footer.
Site branding
A couple of site.toml keys feed the chrome regardless of theme:
title = "Cruma"              # browser tab + default brand
logo  = "images/logo.jpg"    # navbar logo image (else the title as text)
site.toml reference
site.toml holds your site-level settings. Every key is optional — a bare
title and a content/home.md are enough to publish. Keys are grouped below;
several have a whole chapter of their own, linked inline.
Identity & SEO
title       = "Acme"                 # browser tab + default brand
brand       = "Acme Docs"            # brand text (overrides title in the bar)
brand-link  = "#home"                # where the brand links (default: #home)
logo        = "images/logo.svg"      # a logo image instead of brand text
favicon     = "images/favicon.png"   # tab icon
description = "Docs for Acme."        # <meta description> for SEO / link previews
search-key = "ctrl+k" # shortcut that opens the search palette
Analytics
google-analytics = "G-XXXXXXXXXX"      # GA4 measurement id
google-ads       = "AW-XXXXXXXXX"      # Google Ads id
When set, Cruma injects the gtag.js loader for you. Ids are validated before
injection.
Built-in, cookie-free page analytics
Cruma Pages can count page views for you without cookies, without a consent
banner and without any third-party service. It is off by default: a site
without an [analytics] table is built exactly as before.
Who can use it. Pages analytics is a feature Cruma turns on per account.
It works for a site only when both are true: the site has [analytics]
turned on, and the account that owns the site has Pages analytics. If your
account doesn't have it, ask Cruma to turn it on. Sites owned by an
organization can use it once Pages analytics is available to every account.
When Cruma turns it on or off for your account, that takes effect within about
a minute, with no rebuild.
Until both are true, the site collects nothing. Its pages are served without the
analytics script, messages sent to it are refused just as for a site with
analytics off, your servers' events are refused, and you can't create ingest
tokens or read reports (the API answers 403 with
analytics_not_entitled). Your settings, registered events and existing tokens
stay as they are, and you can still change or revoke them.
Optional list of hostnames. At click time, links to these hosts get a ref=<visit id> parameter (plus your oppref campaign tag, if the visitor arrived with one), so a visit can be followed to a download or sign-up on another site you run. Only plain hostnames are accepted.
What is collected. Once per page load, the visitor's browser sends one small
message to your site. From it and the request that carries it, Cruma records:
a visit ID: 16 random bytes made fresh in the browser on every page load.
It is never stored on the visitor's device (no cookie, no localStorage, no
sessionStorage), so a returning visitor gets a new ID and cannot be
recognised across visits or devices;
the page path, and the address of the page the visitor came from, if any.
Cruma keeps only that page's host and discards the rest of the address;
the campaign tags utm_source, utm_medium, utm_campaign and oppref, if
they were in the address;
the visitor's country, only when the site is served through Cloudflare, and
a coarse browser family (Chrome, Firefox, Safari, Edge, other) with a flag for
known crawlers and scanners;
a hashed network address: SHA-256 of the visitor's IP address combined
with a random secret that changes every day at 00:00 UTC and is deleted after
48 hours. The IP address itself is never written to any log or database, and
the hash cannot be matched from one day to the next.
What is not collected. No cookies, no device storage, no fingerprinting, no
name, email or account information, and no raw IP address.
Good to know.
Visitors who have JavaScript turned off are not counted.
Known bots and crawlers are still recorded, but tagged so you can leave them
out of your numbers.
The counting works the same when your site is served through a CDN that
caches your pages, because the visit ID is created in the browser rather than
in the page.
Requests are rate-limited per hashed address and per site, and oversized
messages are rejected. Each site can store up to 500,000 page views and
browser events per day (UTC); past that, further ones are not counted until
the next day.
Page views and custom events are only counted for sites with [analytics]
turned on whose owner's account has Pages analytics (see Who can use it
above). A message sent to any other site is refused.
A message that does not come from one of your site's own pages (its origin is
missing or belongs to another site) is still stored, but flagged as
suspicious so it can be left out of your numbers. A script can send fake
browser events, so the limits and flags reduce that rather than rule it out.
Because nothing is stored on the visitor's device, this usually needs no
consent banner under ePrivacy rules, but check that against your own
jurisdiction before relying on it.
For text you can adapt for your privacy policy, covering page views, custom
events from the browser and your servers, and retention, see
Analytics and your privacy policy.
Custom events from the browser
With [analytics] on, your pages also get a small function you can call from
your own scripts to record something other than a page view, such as a click on
a sign-up button:
name: a string. page_view is reserved for the automatic page view and is
ignored.
props (optional): a flat object whose values are strings, booleans or finite
numbers. Nested objects, arrays and null are not accepted. A call with
props that do not fit is ignored as a whole rather than sent half-empty. A
single event may carry at most 20 properties, and the whole message must stay
under 1 KB.
An event is sent with the same visit ID as the page view of that page load, so
it adds nothing to what the browser stores: still no cookie and no device
storage. The call never throws and never retries, so a refused or lost event
cannot break your page.
Only names you have registered for your site are stored, and only if the name
is registered as browser-allowed. A name that is not registered, or is
registered as server-only, is refused by the server and nothing is stored. The
property values you send are stored with the event, so send only what you are
willing to describe in your privacy policy, and never personal data such as
an email address. Registered events are managed by your site's owners and
members.
Like page views, browser events can be forged by anyone who can run a script
against your site, so treat them as counts, not proof. An event that matters,
such as a purchase, should be sent from your server instead.
Cookies
Cruma itself sets no cookie on sites it hosts or on custom domains pointed at
them, so a CDN in front of your site can cache your pages. Only the
pages.cruma.io editor uses a load-balancing cookie.
Custom code
Raw HTML injected verbatim — your own code, on your own origin, so it is not
escaped:
head-code = "<script>/* verification / pixels */</script>"   # before </head>
body-code = "<script>/* chat widget */</script>"             # before </body>
Beyond page views, a site with built-in analytics turned on, owned
by an account that has Pages analytics, can record custom events: a download, a sign-up, anything you want to count. A
custom event must be registered first, so nothing is stored under a name you
did not choose. Events come from two places:
The visitor's browser, only for events you register as browser-allowed.
Your own servers, which post events with an ingest token instead of a
login.
The same settings cover how long events are kept (retention). You set all of
this up in the dashboard; the API reference further down is for
automating it.
Setting it up in the dashboard
Open your site in the pages dashboard (on pages.cruma.io, or embedded in
dash.cruma.io), choose the Settings tab and scroll to Analytics. You need
access to manage the site. If analytics is not turned on for the site yet, the
section says so: add enabled = true under [analytics] in site.toml, save,
and come back once the site has rebuilt. Pages analytics also has to be turned
on for the account that owns the site (see
Who can use it); without it, creating or
regenerating a token is refused.
Register your events. Under Events, choose Register event, give it
a name, and optionally list the properties it carries and their types. Tick
May be sent from the browser only for events a page should send with
cruma.track(...). Example on an event shows a ready-to-copy
cruma.track(...) line (for browser events), the ingest tokens that may
send the event from your server, and a link to the curl example under
Sending events from your server. Edit and
Delete change or unregister it.
Create an ingest token for each server that sends events. Under Ingest
tokens, choose Create token, give it a label (for example the server's
name) and, if you like, limit it to some of your events. The token is shown
once, with a copy button: store it in your server's secrets right away.
The list afterwards shows each token's label, allowed events, when it was
created and last used, and whether it is active, replaced or revoked, never
the token itself.
Rotate or revoke tokens.Regenerate shows a new token once. The old one
keeps working for the time the dashboard states (24 hours), and both are
listed until then. Revoke asks for confirmation and then refuses the
token at once.
Choose the retention under Retention, between 1 and 396 days.
Errors are shown with the reason the server gave, for example a reserved event
name or an event that is already registered.
API reference
Everything the dashboard does is also available through the Pages API; its
complete, machine-readable description is served at /openapi.json and you can
generate a client from it. Every route below is relative to /api/sites/{id},
where {id} is your site's id, and needs a login with access to the site:
pages:read to look, and pages:write (or being the owner or an organization
admin) to change anything.
Registered events
An event name is 1 to 64 lowercase letters, digits or underscores, starting with
a letter (download, first_connect). page_view and every name starting with
cruma_ are reserved. A site can register up to 100 events.
Unregisters it. Events already stored are kept until retention removes them.
browser_allowed defaults to false: the event can only be posted by your
servers. Turn it on only for events that are fine to count even though a
script in a visitor's browser could forge them.
expected_props declares the properties the event may carry and their types
(string, number or bool), at most 20 properties with names up to 64
characters. When set, properties outside the list and values of the wrong type
are refused. Declared properties may be left out. Properties are always flat:
no nested objects or lists, at most 20 of them and 1 KB in total.
Ingest tokens
An ingest token lets one of your servers post events for one site. It starts with
cru_ and is sent as Authorization: Bearer <token>.
Route
What it does
GET /analytics/tokens
Lists the tokens: label, allowed events, when each was created and last used, and whether it was revoked or replaced. Never the token itself.
POST /analytics/tokens
Creates one: { "label", "allowed_events"? }.
POST /analytics/tokens/{token_id}/regenerate
Issues a replacement.
DELETE /analytics/tokens/{token_id}
Revokes it. Revoking twice is fine.
The raw token is in the response of creating or regenerating, once. Cruma
stores only a hash of it, so a lost token cannot be shown again; regenerate it.
A label is 1 to 100 characters, to tell tokens apart (for example the name of
the server that holds it).
allowed_events limits a token to the listed names (which may include
page_view). Without it, the token may post every registered event.
Creating and regenerating a token are refused with 403 and
{ "error": "analytics_not_entitled" } when the account that owns the site
doesn't have Pages analytics. Listing and revoking tokens still work.
Regenerating makes a new token that works at once. The old token keeps working
for 24 hours so you can roll it out without downtime, then stops. The response
says how long, in previous_token_valid_for_secs. Times in the list are Unix
seconds.
Sending events from your server
POST /api/sites/{id}/events with Authorization: Bearer <ingest token>:
A batch holds 1 to 100 events. Each needs an id of your choosing; sending the
same id again for a site is reported as a duplicate and not stored twice, so
a retry is safe.
Optional per event: ts (Unix milliseconds, within 24 hours of now; the
receive time if left out), visit_id, install_id, user_id, props,
client_ip, user_agent and ref (the visit ID a tagged link carried to
your server, used as visit_id when that is left out).
Cruma never stores or logs the client_ip or the raw user_agent: the address
becomes the same daily-salted hash page views use, and the user agent is
reduced to a browser family.
The answer has one result per event, in order: stored, duplicate or
rejected with a reason (for example unregistered_name,
props_mismatch or token_not_allowed). It is 200 when anything was stored
or already known and 422 when every event was refused.
A whole request can be refused with a JSON body { "error", "message" }:
401 for a missing, unknown, revoked or expired token, 403 with
analytics_disabled when analytics is not turned on for the site or
analytics_not_entitled when the account that owns the site doesn't have
Pages analytics, 404, 400 for a malformed or empty batch (or
invalid_path_parameter when the site ID in the URL is not valid text), 413
for a batch or body that is too large, and 429 when you are sending too fast
(600 events per token per minute, 3,000 per site per minute) or the site's
daily quota of 500,000 server events is used up.
Retention
Events are deleted once they are older than the site's retention, between 1 and
396 days (13 months, the default).
Route
What it does
GET /analytics/settings
Returns retention_days and its allowed range, and whether analytics is turned on (analytics_enabled, which you change in site.toml, not here).
PUT /analytics/settings
Sets it: { "retention_days": 90 }. Values outside 1 to 396 are refused.
Shortening the retention deletes the older events at the next daily clean-up.
Reading your analytics: counts, journeys and funnels
Once your site stores page views and custom events,
three read-only routes answer questions like "how many people downloaded the
app today, and how many of them went on to sign up?":
Route
Answers
GET /analytics/counts
How many of each event, per day.
GET /analytics/journeys
What each visitor of one day did, in order.
POST /analytics/funnel
How many visitors got through each step of a list you choose, per day.
The funnels the dashboard saves are under /analytics/funnels; see Saved
funnels API at the end.
Like the other analytics routes, each is relative to /api/sites/{id} and needs
a login that can read the site (pages:read, or being the owner or an
organization admin). Anyone else gets 404, as if the site did not exist. If
the account that owns the site doesn't have Pages analytics (see
Who can use it), all three answer 403 with
{ "error": "analytics_not_entitled" }; once it is turned on, the events stored
before are readable again. All three are in the machine-readable API description
at /openapi.json. In the
examples below, $PAGES is the address of the Pages dashboard you sign in to,
$SITE your site's id and $TOKEN your login token.
You don't need the API to read your numbers: the dashboard's Analytics tab
shows the same data. The API is for scripts and your own reports.
The Analytics tab
Open your site in the Pages dashboard and choose the Analytics tab, next
to Themes. Anyone who can read the site can use it. Only you and the people
you gave access to can see a site's analytics. If analytics is not turned on
for the site, the tab says how to turn it on (see
Custom events).
The row at the top applies to everything below it:
From and To choose the days (UTC). The tab opens on the last 14 days.
Show bots and suspect events is off by default, so the numbers count
people. Tick it to include bots and suspect events too.
The tab has three parts:
Events over time. One line per event name, per day. Hover a day to see
its counts. Show table shows the same numbers as a table.
Funnels. Pick a saved funnel to see how many visitors got through each
step in the chosen days. Each step shows its count, the share of the step
before it and the share of the first step. Breakdown splits the numbers
by Platform (the platform property, for example macos or windows)
or by Source:
Ad: the visit came from an ad (it has oppref).
Referrer: it came from a link on another site.
Direct: neither.
A step that uses a best-effort join (see Best-effort joins below) is
marked best-effort and drawn hatched. It also shows how many of its visitors were reached that way. Read
those numbers as estimates. A funnel covers at most 31 days; with a longer
range, the tab uses the last 31 days and says so.
Journeys. Choose a day to see what each visitor did, one row per visit:
the visit's events in order, followed by what its install and user IDs led
to later. Best-effort join (24 h) is on by default. It links a visit that
reached no install to the app install that came from the same network. Events
linked that way are drawn dashed and marked best-effort. Load more
shows the next visits.
Building a funnel
Choose New funnel, name it, and add up to 10 steps. Each step is an event
name, optionally narrowed by properties (for example first_launch = true).
From the second step on you can tick Best-effort join, with the number of
hours it may look ahead. Use it where nothing carries an ID from one step to
the next, such as between downloading an app and its first launch. Window
is how long a visitor has, from the first step, to reach the last one (default
72 hours). Save keeps the funnel for everyone who can read the site. Saving,
editing and deleting a funnel needs permission to change the site
(pages:write).
If the site has no saved funnels yet, Start from the app download template
fills in the funnel for an app that is downloaded from your site:
Step
Event
Visits
page_view
Download clicks
download_click (sent from the download button's click handler, for example cruma.track('download_click', { platform: 'macos' }))
Downloads
download
First launches
manifest_fetch with first_launch = true, best-effort within 24 hours
First connects
first_connect
Sign-ups
signup
Change the steps to match the events your site sends.
A visitor counts at a step only if they also reached every earlier step. If
nothing sends one of these events, every step after it shows zero: remove the
step, or send the event.
Things all three have in common
Days are UTC calendar days, written YYYY-MM-DD.
Bots and suspicious events are left out by default. Add
include_bots=true and/or include_suspect=true (in the funnel's request
body, "include_bots": true) to count them too. Bots are recognised by their
user agent; an event is suspicious when, for example, it was sent from a page
that is not on your site.
Visits, installs and users. Events are tied together by the IDs they
carry: the visit ID of a page load, an install ID your app sends, and
a user ID your servers send. An event that carries two of them, such as a
sign-up with both the visit ID and the new user ID, links them.
A refused request gets a JSON body { "error", "message" } with status 400,
for example invalid_date_range, invalid_funnel or invalid_page.
from and to are both included, and the range is at most 92 days.
Optional filters: source=browser or source=server, and a property match
with prop_key and prop_value together (for example
prop_key=platform&prop_value=macos). The value is compared as text, so
true or 42 also match booleans and numbers.
The answer lists every day of the range, oldest first, each with its events
sorted by name. A day without events has an empty list:
For every visit ID seen on day, a journey lists that visit's events and every
event its install and user IDs lead to, oldest first. IDs are followed as far as
they go, through every event from that day on, however much later it came. Only
your retention setting limits how far back the data reaches. Another visit's ID is
not followed: each visit is its own journey. An event reached through a shared
install or user can therefore appear in more than one journey.
Each event shows joined_by (visit, install or user), the ID that brought
it into the journey.
Paging. Journeys come in pages, in the order the visits were first seen that
day. limit sets the page size (1 to 2,000, default 500) and offset how many
visits to skip. The answer says how many visits the day has (total_visits)
and where the next page starts (next_offset, or null on the last page):
steps: 1 to 10, each an event name and, optionally, props the event must
carry with exactly those values.
The range is at most 31 days. A visitor is counted on the day of their first
step.
Each later step is the earliest matching event that comes after the step before
it, within window_hours of the first step (1 to 720, default 72), and shares
a visit, install or user ID with an event matched so far.
breakdown (optional) splits each day's numbers by a property:
{ "by": "prop", "key": "platform" } splits by the property's value, taken
from the earliest matched event that has it. It is null when none has it.
{ "by": "has_prop", "key": "oppref" } splits into true and false,
depending on whether any matched event has the property.
{ "by": "source" } splits by where the visitor came from. Each row then
has "value": null and a source:
{ "kind": "ad", "oppref": "…" } when a matched event has oppref;
otherwise { "kind": "referrer", "host": "…" } when one has
referrer_host;
otherwise { "kind": "direct" }.
The earliest matched event that has the property decides.
Each day of the answer has one { "count", "best_effort_count" } per step, plus
the same per breakdown value. A visitor who stopped after step 2 counts in steps
1 and 2 only.
Best-effort joins
Some steps have no ID in common. When a visitor downloads your app, nothing
carries the visit ID into the app, so the app's first launch cannot be linked to
the download by ID. Both journeys and funnel steps can opt into a best-effort
join for such gaps, with best_effort_hours (1 to 72):
In a journey, a visit that reached no install is linked to an install
whose events came from the same hashed network address, between the visit's
first event and best_effort_hours after its last one.
In a funnel step that finds no event by shared ID, the step takes a
matching event from the previous step's hashed network address within
best_effort_hours of it.
The link is only made when there is exactly one candidate. With two or
more, for example several people behind the same office network, nothing is
joined.
Whatever was reached this way is marked:
in a journey, the events have "best_effort": true and the journey names
the best_effort_install_id;
in a funnel, the step has "best_effort": true and best_effort_count
says how many of its count came through such a link, at that step or an
earlier one.
Treat these numbers as estimates.
The network address is hashed with a value that changes every day (UTC), so a
best-effort link cannot cross midnight UTC.
Saved funnels API
The funnels you save on the Analytics tab are stored per site, and you can
manage them with these routes too. Each one holds a name, the steps and the
window_hours of a funnel request. The breakdown is chosen when you look at
the funnel, so it is not saved.
The steps and window follow the same rules as a funnel request. Steps that
break them are refused with invalid_funnel.
A name is 1 to 80 characters (invalid_funnel_name) and unique within the
site. Reusing one gets 409 funnel_name_taken.
A site can save up to 50 funnels (409 too_many_funnels).
An unknown funnel_id, or one that belongs to another site, gets
404 funnel_not_found.
A login that can read the site but not change it gets 403 on the last
three routes.
Analytics and your privacy policy
This chapter is for site owners who turn on Cruma's built-in analytics and need
to tell their visitors what is collected. It brings together what the previous
chapters describe in detail (site settings,
custom events and
reports). It ends with a paragraph you can
adapt for your own privacy policy, and with the rules you have to follow for
that paragraph to stay true.
Turning it on
Analytics is off until you add this to site.toml:
[analytics]
enabled = true
Pages analytics must also be turned on for the account that owns the site (see
Who can use it). Without it, nothing is collected
and pages are served without the script below.
Once the site has rebuilt, every page carries a small inline script. On each page
load it:
creates a visit ID: 16 random bytes, made fresh in the browser on every
page load and kept only in the page's memory;
sends one page view (page_view) to your site with that ID, the page path,
the full address of the referring page (Cruma keeps only its host) and any
utm_source, utm_medium, utm_campaign or oppref tags in the address;
if you listed hosts under tag_links, adds ref=<visit ID> to links to those
hosts when they are clicked, plus the page's own oppref tag if the visitor
arrived with one, so a visit can be followed to your download or sign-up
site.
The script sets no cookie and writes nothing to localStorage,
sessionStorage or indexedDB. A returning visitor gets a new visit ID and
cannot be recognised across visits or devices.
Defining events
Apart from page_view, which is built in, an event is only stored under a name
you have registered for the site (in the dashboard's Analytics settings,
see Custom events). An event with any other
name is rejected, so nothing is stored under a name you did not choose.
Each registered event has a May be sent from the browser switch. It is off by
default, so the event can only come from your own servers with an ingest token.
Turn it on only for events where a forged one would not matter (see
Forged browser events below).
Sending events from the browser
On a page with analytics turned on, your own scripts can call:
The event is sent with the same visit ID as that page load's page view, so
it adds nothing to what the browser keeps. props must be a flat object of
strings, booleans and finite numbers; a call that doesn't fit is ignored, and
track never throws and never retries. Only names registered as
browser-allowed are stored.
Sending events from your server
Your servers post events to POST /api/sites/{id}/events, where {id} is your
site's id, with an ingest token. A batch holds 1 to 100 events:
id is yours to choose and makes retries safe: sending the same id
again answers duplicate and stores nothing new.
client_ip is the visitor's address, if you have it. It is hashed the
moment it arrives, with the same daily-changing secret page views use, and is
never stored or logged.
user_agent is reduced to a browser family (firefox, chrome and so on)
and a bot flag; the full string is never stored.
ref is the visit ID a tagged link carried
to your server. It becomes the event's visit ID, which ties the event to the
page view the visitor came from. An explicit visit_id takes precedence.
The other optional fields (ts, visit_id, install_id, user_id, props)
and every error are listed under
Sending events from your server.
Ingest tokens
An ingest token lets one of your servers post events for one site. You create
tokens in the dashboard or through the API.
A token starts with cru_. It is shown once, when it is created. Cruma
stores only a hash of it, so a lost token cannot be shown again; make a new
one.
Give each server its own named token, for example billing or
downloads, so you can see which one was last used and revoke one without
touching the others.
A token can be scoped to some of your events. A scoped token cannot post
any other name: that event is rejected and the rest of the batch is still
stored.
Rotating without downtime, by overlap: create a second token, deploy it,
check in the token list that it is being used, then revoke the old one. Both
work in between.
Rotating in one step:Regenerate issues a replacement at once. The old
token keeps working for a grace period of 24 hours, then stops.
Revoking a token refuses it immediately.
What is stored for each event
Field
What it holds
id
Your event ID (server events) or a random ID Cruma makes (browser events).
name
page_view or one of your registered names.
ts
When it happened, in Unix milliseconds.
source
browser or server.
visit_id
The random per-page-load visit ID, if any.
install_id, user_id
Only if your server sends them.
props
The event's properties: for page views the path, referring host and campaign tags; for your events whatever you send.
ip_hash
A daily-salted SHA-256 hash of the visitor's address. Never the address itself.
country
The two-letter country, only when the site is served through Cloudflare.
ua_family
A browser family such as firefox, never the full user agent.
is_bot
Set for known crawlers and scanners.
suspect
Why an event looks forged, if it does, for example origin_mismatch.
Retention
Each site keeps its events for a number of days you choose, between 1 and 396
(13 months). The default is the maximum, 396 days. Once a day, Cruma deletes
every event older than that. The daily secret behind ip_hash is deleted after
48 hours, after which a hash can no longer be matched to any address.
Forged browser events
Anything a browser can send, a script can send too. Browser events carry no
secret: anyone can post a page view or a browser-allowed event for your site,
with any visit ID and any properties.
Cruma bounds this rather than preventing it:
at most 30 browser events per minute from one (hashed) address, and 3,000 per
minute per site;
at most 500,000 page views and browser events per site per UTC day;
events that don't come from one of your own pages are stored but flagged as
suspect, and known bots are flagged too. Both are hidden by default
in the dashboard and the read API.
So anything that matters, such as sign-ups, purchases or downloads, should be
a server-only event, sent by your server after it has seen the real thing.
Treat browser events as rough counts.
Your part
No personal data in props or user_id. Use opaque IDs only (such as
u_8f3a2c, an ID your own system maps back to an account), never an email
address, a name or a phone number. Cruma stores what you send as it is.
Only server-sent events may ever be forwarded to an ad partner. Cruma
does not send your events to anyone. If it ever offers forwarding, for example
to an ad platform's conversion API, it will forward only events your servers
sent and never browser events, because those can be forged. If you forward
events yourself, follow the same rule.
For your privacy policy
The paragraph below describes Cruma's analytics as shipped. Replace the parts in
square brackets, delete the sentences about features you don't use, and list
the events you have registered.
Analytics. We count visits to this site with Cruma's built-in analytics,
which uses no cookies and stores nothing on your device. When a page loads,
your browser creates a random visit ID that exists only for that page view, so
we cannot recognise you on a later visit or on another device. With each page
view we record that visit ID, the page you opened, the website that linked to
it (its domain only), any campaign tags in the address, your country [when our
CDN provides it], a coarse browser type such as "Firefox", and a hash of your
IP address. The hash is computed with a secret that changes every day and is
deleted after 48 hours, after which it cannot be linked back to your address;
your IP address itself is never stored. We also record the actions listed
below, which may be sent by your browser or by our servers, and may tie them
to the visit ID of the page you came from [and to a pseudonymous account ID
that contains no name or email address]. We record: [your events, for example
"sign-ups, with the plan chosen"]. Our hosting provider, Cruma, stores this
data for us. We keep it for [13 months] and then delete it. We use it only to
understand how our site is used, and we do not share browser-recorded data
with advertising partners.
Quick Start Guide
This guide should be simple enough to get your locally hosted web-site or service accessible on the public Internet within 1-3 minutes.
💡 Prefer clicking? Do it in the desktop app
You don't need the terminal at all. The desktop app has a three-step wizard that does the same job. See Your first site in the app.
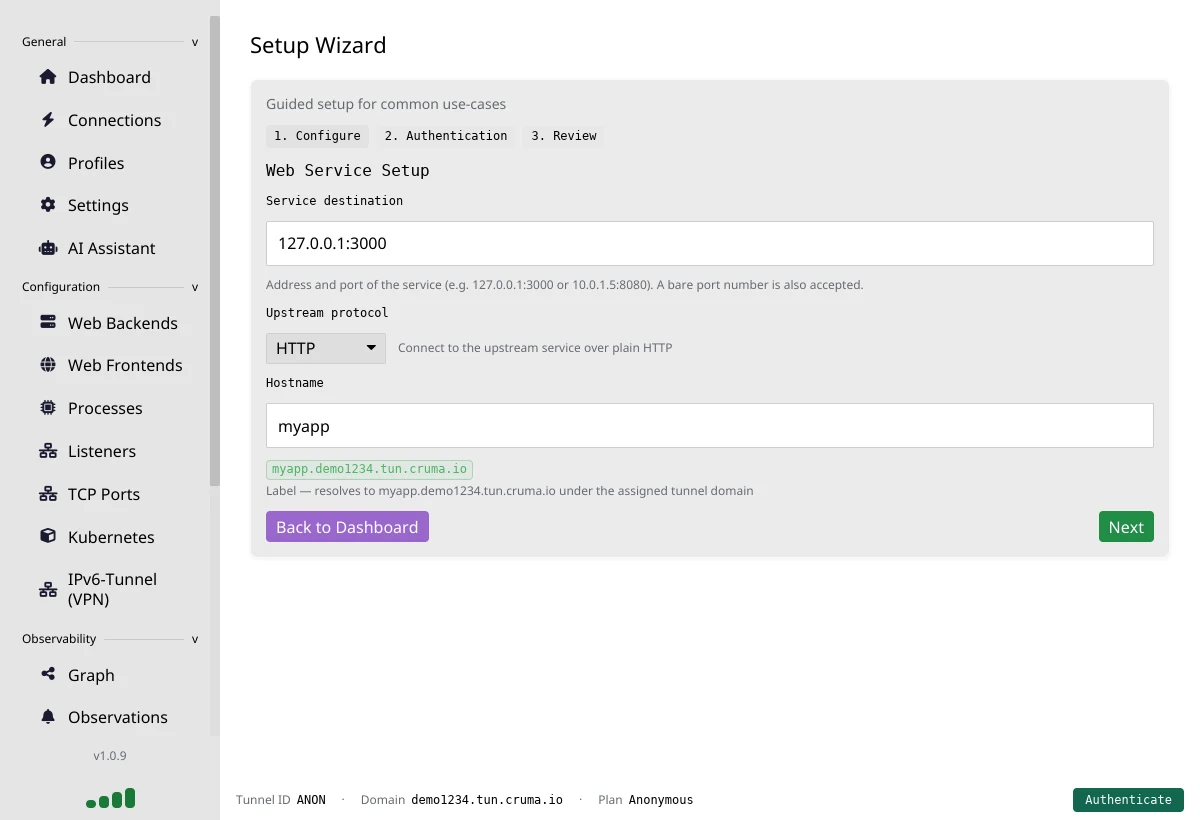
The Setup Wizard in the desktop app: no commands required.
What is Cruma?
Cruma is a local-first tunneling agent that gives you a public URL for local or private services with a single command. It comes with a desktop app (GUI), a TUI (terminal UI), and a headless mode for inspection and control. It supports HTTP, HTTPS, TCP, raw TCP, serving local directories, and hosting processes.
If you bring your own domain via CNAME, TLS is terminated on your agent using a certificate automatically obtained from Let's Encrypt (ACME TLS-ALPN-01). This provides end-to-end encryption between clients and your agent — Cruma infrastructure only forwards the encrypted stream and sees control-plane metadata.
Key concepts
tunnel_id defines the public FQDN and routing pool; agents sharing a tunnel ID are load‑balanced together.
profile (config-file setting) scopes the cached identity (useful for multiple anonymous identities).
temp (config-file setting) creates a one‑off identity for a fresh FQDN each run.
Accessing the agent
Cruma is now in public beta. The service is free during this period while features, limits, and pricing evolve based on real‑world use.
Download the tunnel agent at https://cruma.io and pick your platform. Running cruma with no arguments creates a default configuration file (with anonymous credentials and no routes) and starts it — opening the desktop app on a graphical desktop, or the TUI when no display is available. If no default config location can be determined, a short numbered prompt in the terminal offers a few starting points (run without routes, serve a directory, or expose an HTTP/HTTPS service). Run cruma --help to see all options.
Install & run (fast path)
Download the agent from https://cruma.io and install for your OS.
Start your local service (for example on port 3000).
Run:
cruma proxy http 3000
That's it — you'll get a public URL printed in the terminal.
Anonymous quick test
You can run an anonymous tunnel without a tunnel ID or secret. A unique FQDN is assigned and persisted in the agent cache directory (see cruma show-cache):
cruma proxy http 3000
This is great for quick local tests; anonymous tunnels have tighter limits (see Rate Limits & Fair Use).
Anonymous mode is zero‑setup. When you're ready for custom domains or higher limits, add --tunnel-id and --secret-key from your account.
For a fresh anonymous FQDN each run, set temp: true in your config file. For multiple stable anonymous identities, set profile: <id> in your config file.
Basic usage with credentials
This assumes your service is running locally on port 8080. Replace TUNNEL_ID and SECRET_KEY with the values from your account.
The target can be host:port (e.g. 127.0.0.1:8080), just a port number (e.g. 8080, defaults to 127.0.0.1), or a hostname (e.g. example.com).
--tunnel-id (alias --id) is the tunnel name; leave it out to use the default (sourced from your configuration file, otherwise ANON).
--secret-key (alias --key) is only used in combination with --tunnel-id; also sourced from your configuration file if not provided.
--tower-server defaults to tower.cruma.io:443; optional override to target a different region. It is a global option, so it goes before the subcommand: cruma --tower-server HOST:PORT proxy http 8080.
--protocol auto|quic|h2 selects the transport used for the tunnel channels (auto is the default). It sits between proxy and the kind: cruma proxy --protocol quic http 8080.
You'll receive the public URL after the tunnel is established.
UI modes
Cruma is one program with three faces, all driving the same runtime and config file:
Desktop app (GUI) — the default when you run cruma, cruma start, or a config file on a machine with a graphical desktop.
TUI — the terminal UI. It is used automatically for proxy and serve, and whenever no graphical desktop is detected. Pass --tui to force it (for example cruma --tui start).
Headless — no interface at all; pass --headless (useful for scripts, services, and CI).
Related global options (place them before the subcommand):
--minimized — start the desktop app hidden, showing only the tray icon.
--theme light|dark|system — control the UI theme (system is the default).
Serve a local directory
You can serve static files from a local directory without any other server:
cruma serve ./public
Options:
--allow-dir-index — show directory listing when no index file is present.
--render-markdown — render .md files as HTML.
--spa — SPA fallback: serve the nearest index.html instead of 404 for missing paths.
In the desktop app, the same choice lives under Settings → Tower Server.
Using a config file
For multi-target setups, use a config file (YAML or JSON). The config uses backends (where traffic goes) and frontends (hostname routes that point to backends):
The kind: cruma listener is what connects the agent to the Cruma cloud. Config files without one run local-only; the one-off proxy and serve commands add it for you.
Run it with:
cruma start ./cruma.yaml
Shortcuts: a bare .yaml/.yml/.json path (cruma ./cruma.yaml) or --config/-c (cruma -c ./cruma.yaml) mean the same thing. cruma start with no path uses the platform default config file, creating it if missing (cruma config locate shows where it lives). On a desktop this opens the desktop app; add --tui or --headless to choose otherwise.
You can also manage configs from the CLI without editing YAML by hand:
config add supports http, https, tcp, raw, dir, and process targets; config show lists everything with indices you can pass to config update, config remove, config remove-process, and config remove-listener. Add -c PATH right after config to operate on a file other than the default.
See the configuration guide for the full reference including processes, listeners, middlewares, and local-only mode.
Forwarding TCP services
Use proxy tcp to forward plain TCP to your backend after TLS termination:
Use --port to pick the ingress TCP port to expose; it defaults to the destination port.
For assigned FQDNs (*.tun.cruma.io), TLS is terminated at the Cruma ingress. For CNAME'd custom domains, TLS is terminated on your agent. Either way, your backend receives a plain TCP stream.
Use proxy raw for TLS pass-through to your backend (the backend handles TLS itself):
cruma proxy raw 127.0.0.1:4943 --tunnel-id TUNNEL_ID --secret-key SECRET_KEY
Note: raw only provides true TLS pass-through when using a CNAME'd custom domain. With assigned FQDNs, TLS is always terminated at the Cruma ingress, so raw behaves the same as tcp.
The platform will provide the reachable endpoint once the tunnel is up.
Upstream protocol
When proxying HTTP/HTTPS traffic, you can select the protocol used to talk to your backend with --upstream-protocol:
h1 — HTTP/1.1 (default, most compatible)
h2 — HTTP/2, ALPN-negotiated for HTTPS backends; falls back to HTTP/1.1 on cleartext backends
h2pk — HTTP/2 Prior Knowledge (speak HTTP/2 directly without negotiation; use this for cleartext HTTP/2)
Global options (--headless, --tui, --minimized, --theme, --tower-server) go before the subcommand.
Desktop app
The Desktop App
The Quick Start gets you online from the terminal with a single command. But Cruma is also a full desktop application — a visual control panel for the exact same agent. Everything the CLI does, you can do here by clicking, and you get live dashboards, request inspection, and a built-in assistant on top.
This chapter is the overview; the chapters after it tour the app page by page. It assumes no prior experience with proxies or web servers — if a term is new, we explain it as we go.
💡 Three ways to run the same agent
Cruma is one program with three faces: the desktop app (a graphical window), the TUI (a text interface that runs inside your terminal, great over SSH), and headless (no interface at all, for servers and CI). They all drive the same runtime and the same config file — pick whichever fits where you are. On macOS, Windows, and Linux desktops the graphical window opens by default when you run cruma, cruma start, or a config file; add --tui for the terminal UI, --headless for none, or --minimized to start with only the tray icon. The one-shot proxy and serve commands always use the TUI. Without a graphical desktop (SSH, servers), Cruma falls back to the TUI.
New to proxies? The 30-second mental model
Cruma sits in front of your own programs and decides where each incoming web request should go. Picture a receptionist at a front desk:
Someone walks in the door → that's a request arriving.
The receptionist reads who they're here to see (the website address, or hostname) → that's routing.
They send the visitor to the right office → that's your service (a website, an API, a folder of files).
Along the way they can check ID, turn away banned visitors, or stamp a form → those are middlewares (auth, rate limits, header tweaks).
Cruma is that receptionist. Three nouns describe the whole job, and the app has one page for each:
Noun
Plain meaning
Page
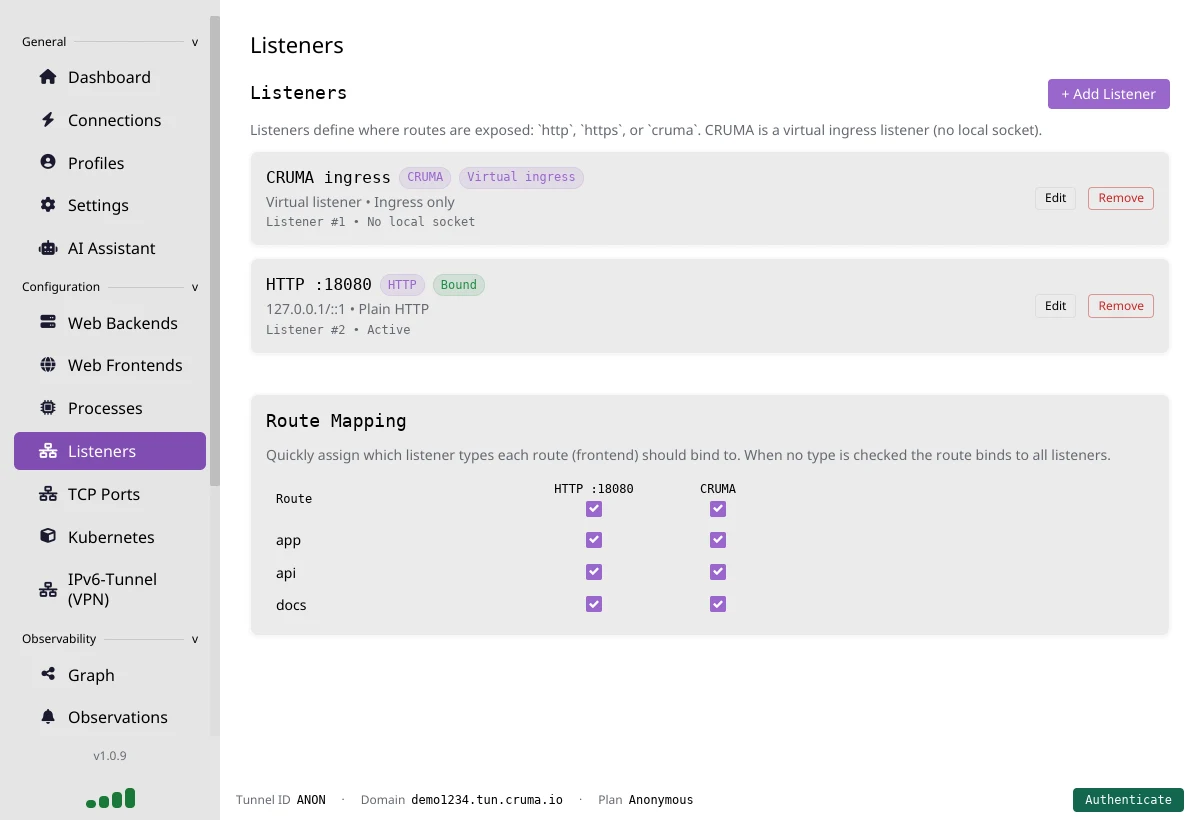
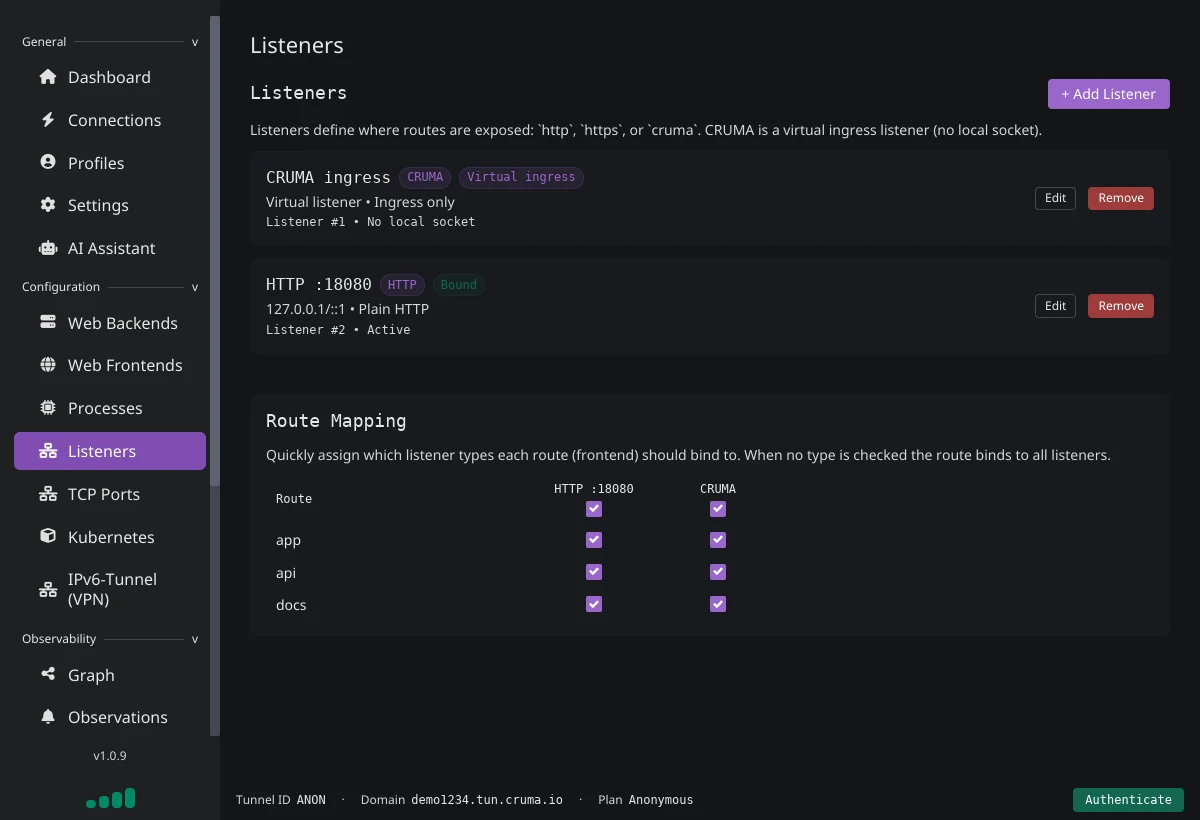
Listener
The door traffic comes in through — a local port, or the Cruma tunnel from the internet.
Listeners
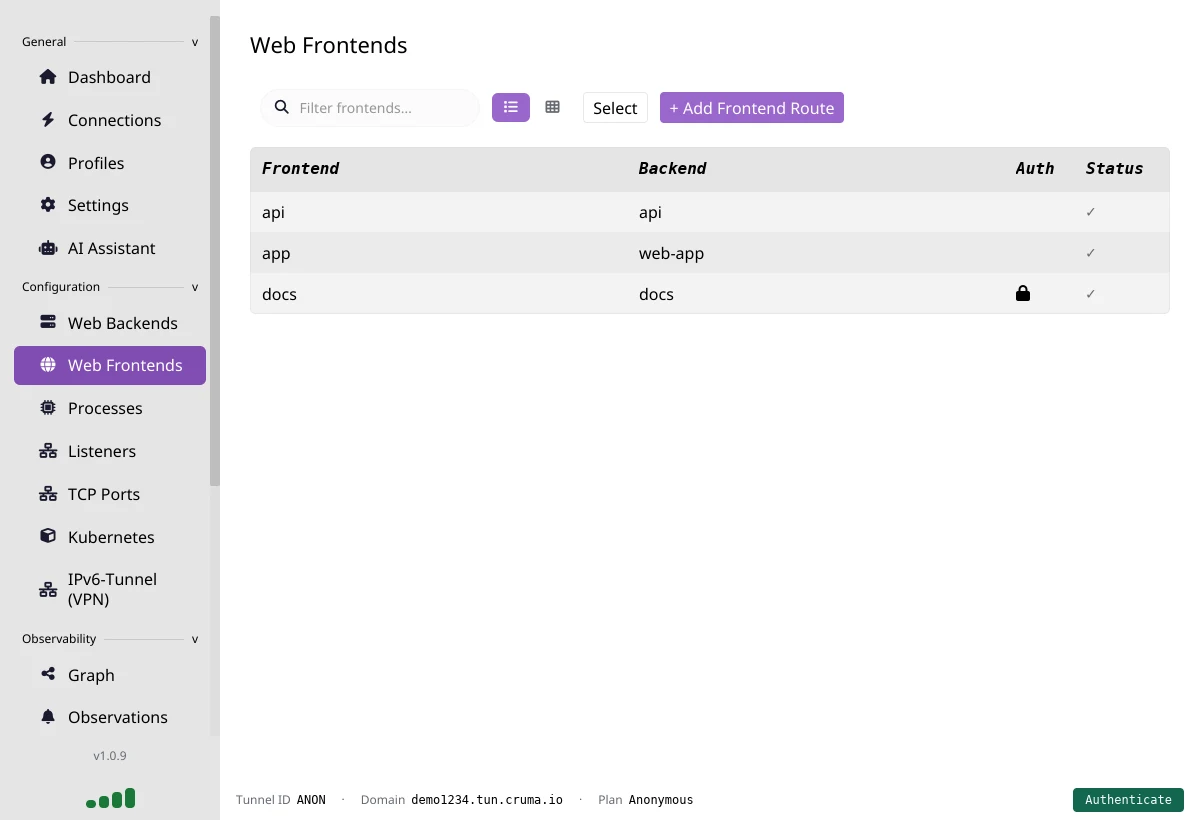
Frontend
A rule: "requests for this address go to that service," plus any checks to run first.
Web Frontends
Backend / Process
The destination — a service you point at (localhost:3000), a folder of files, or a program Cruma runs for you.
Web Backends / Processes
(Plain TCP services that aren't HTTP get their own TCP Ports page.)
Once those three click, the rest of the app is just windows onto the running system.
First launch
Opening the app for the first time (or running cruma with no arguments) creates a default config file with an anonymous tunnel and no routes yet. The Dashboard then offers Guided Setup cards that start a short wizard. The next chapter, Your first site in the app, walks through it.
Closing the window doesn't quit Cruma
Closing the app's window — the red button on macOS, or the close button on Windows and Linux — leaves Cruma running in the background; your tunnels and routes stay up. To get the window back:
Click the tray icon (the menu bar on macOS, the system tray elsewhere) and choose Show.
On macOS, Cruma → Show All in the menu bar also reopens it, as does Cruma Window in the Window menu.
On macOS, clicking the Dock icon reopens the window instantly.
A tour of the window
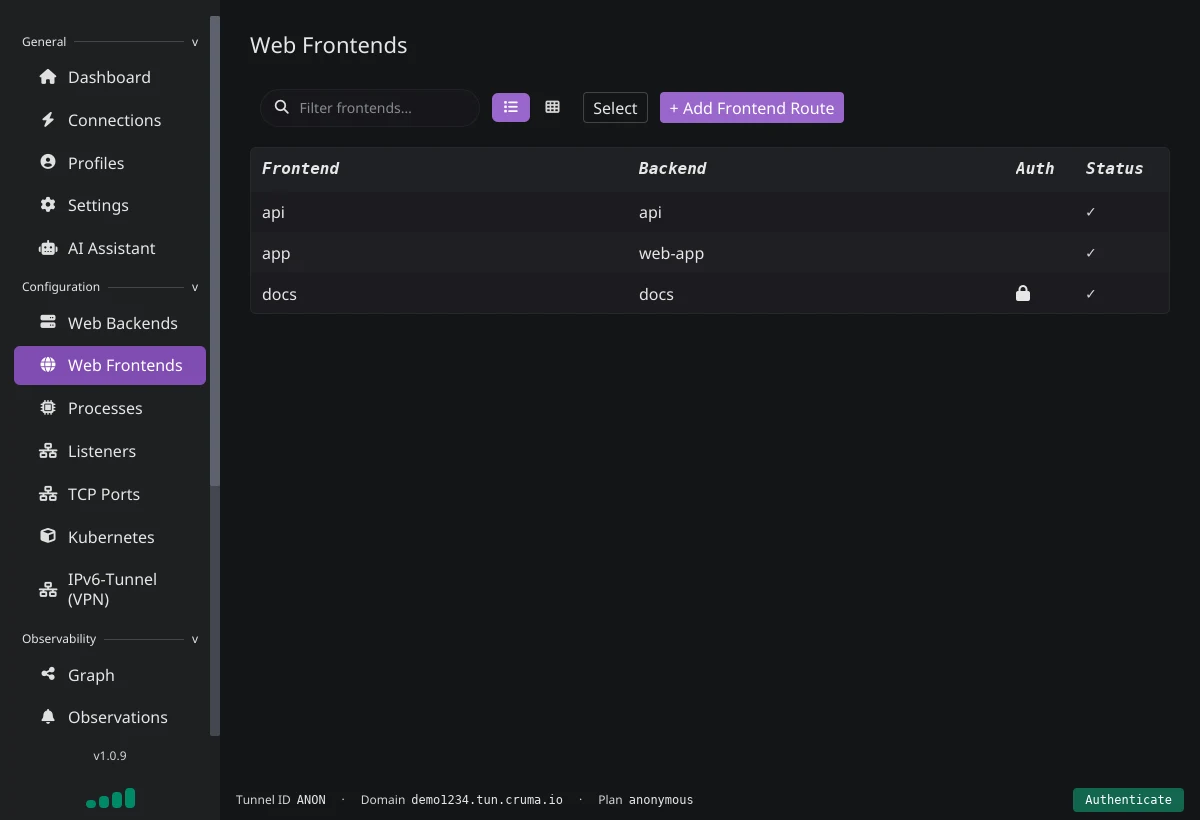
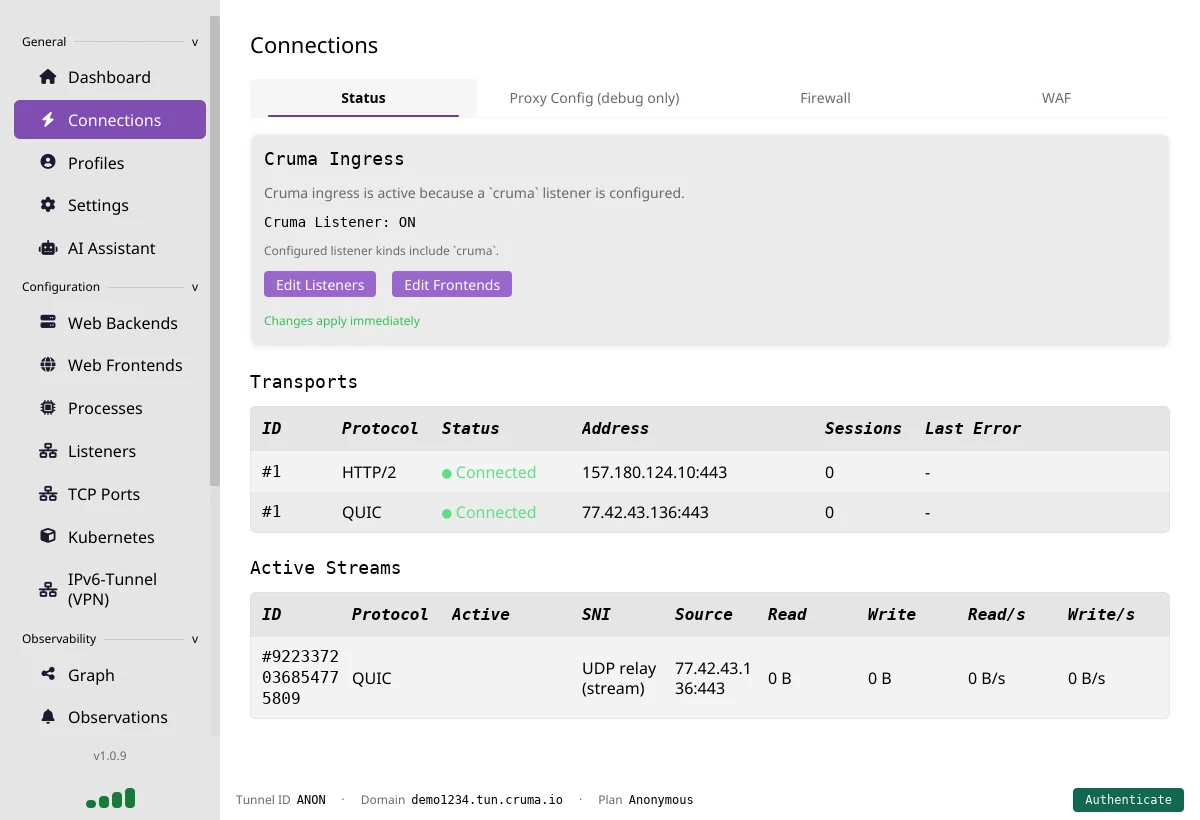
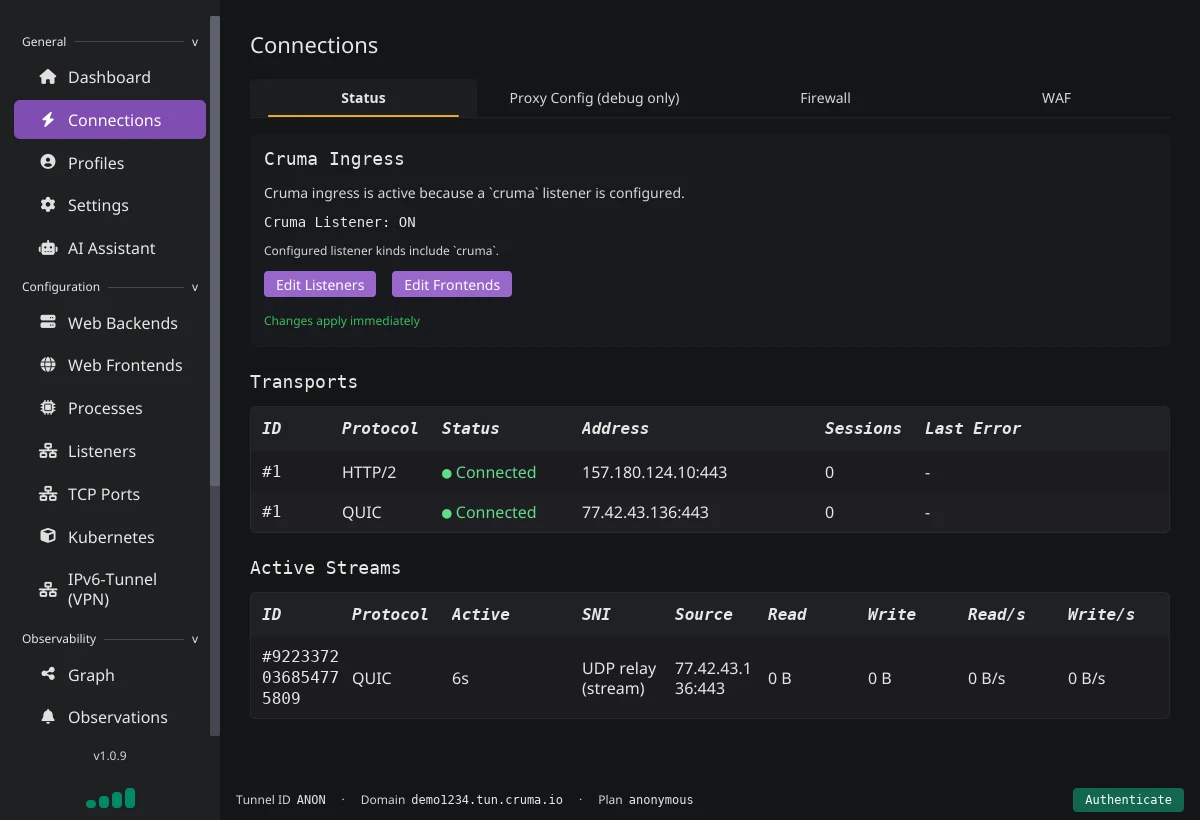
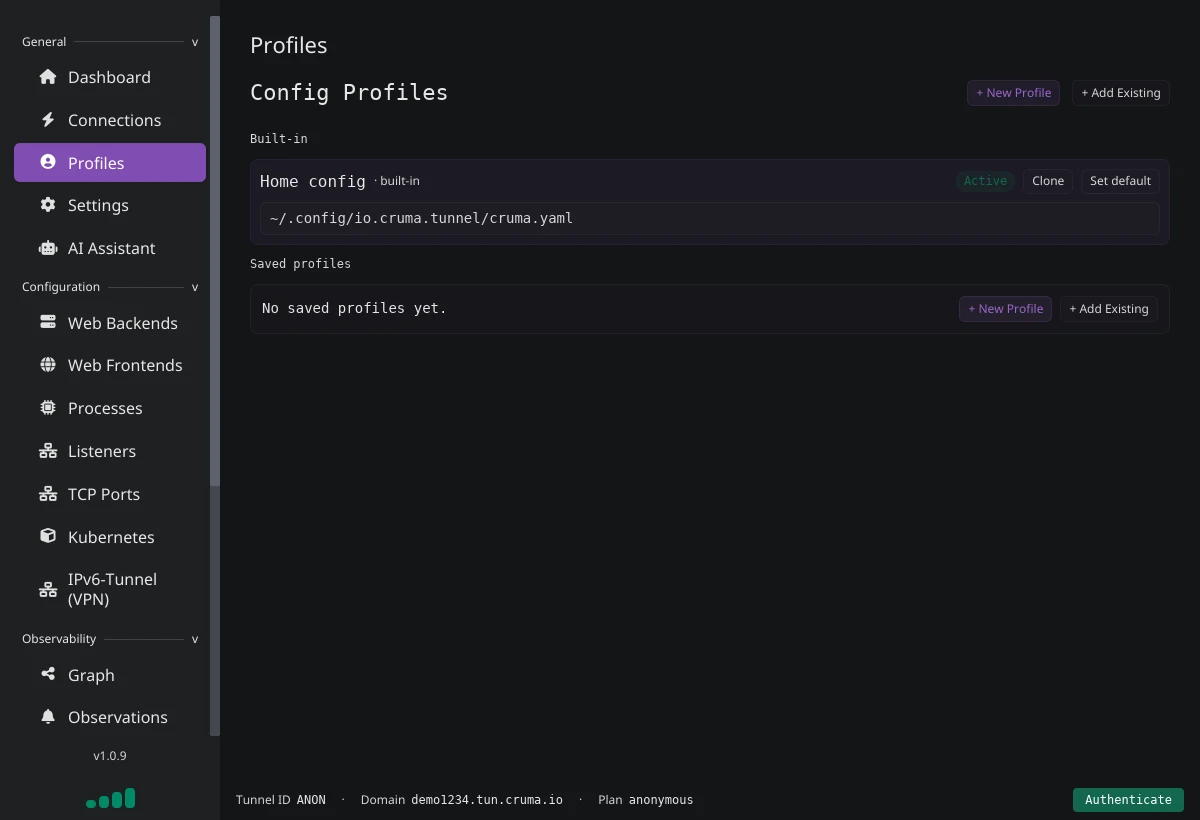
The app has a sidebar on the left and the current page on the right. At the bottom of the window a status bar shows your Tunnel ID, your assigned Domain, and your Plan. On the anonymous plan it also offers an Authenticate button. The sidebar is split into groups:
General — Dashboard, Connections, Profiles, Settings, and AI Assistant.
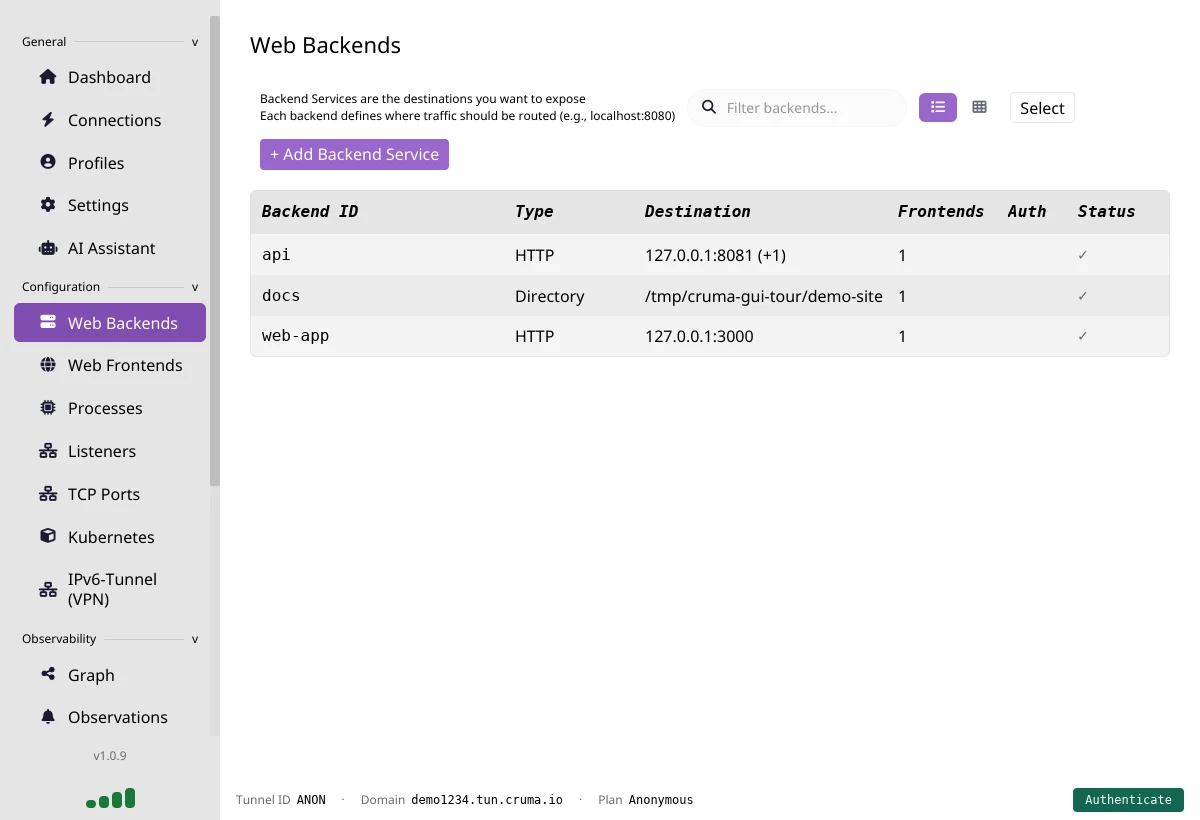
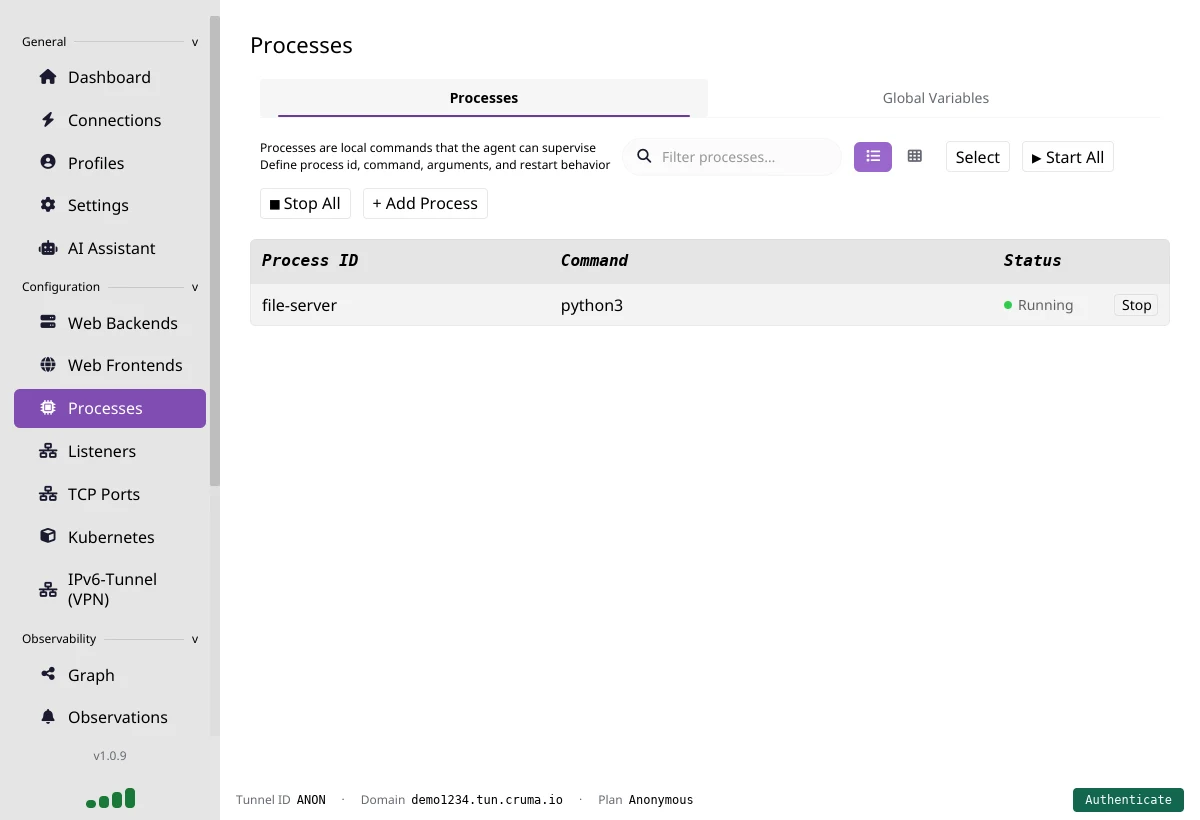
Configuration — the pages where you build your setup: Web Backends, Web Frontends, Processes, Listeners, TCP Ports, Kubernetes, and IPv6-Tunnel (VPN).
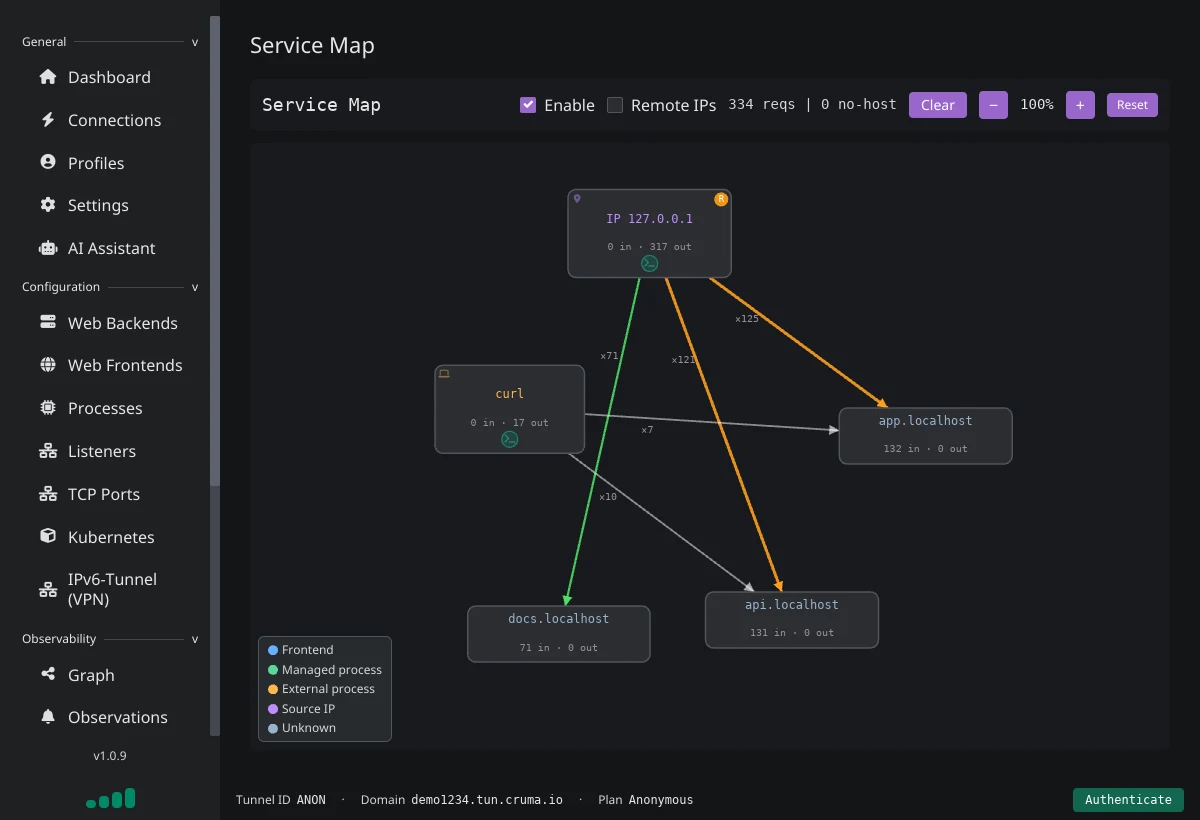
Observability — live views of what is happening: Graph, Observations, and further down the list Requests, Statistics, Service Map, and more. Scroll the sidebar if your window is short.
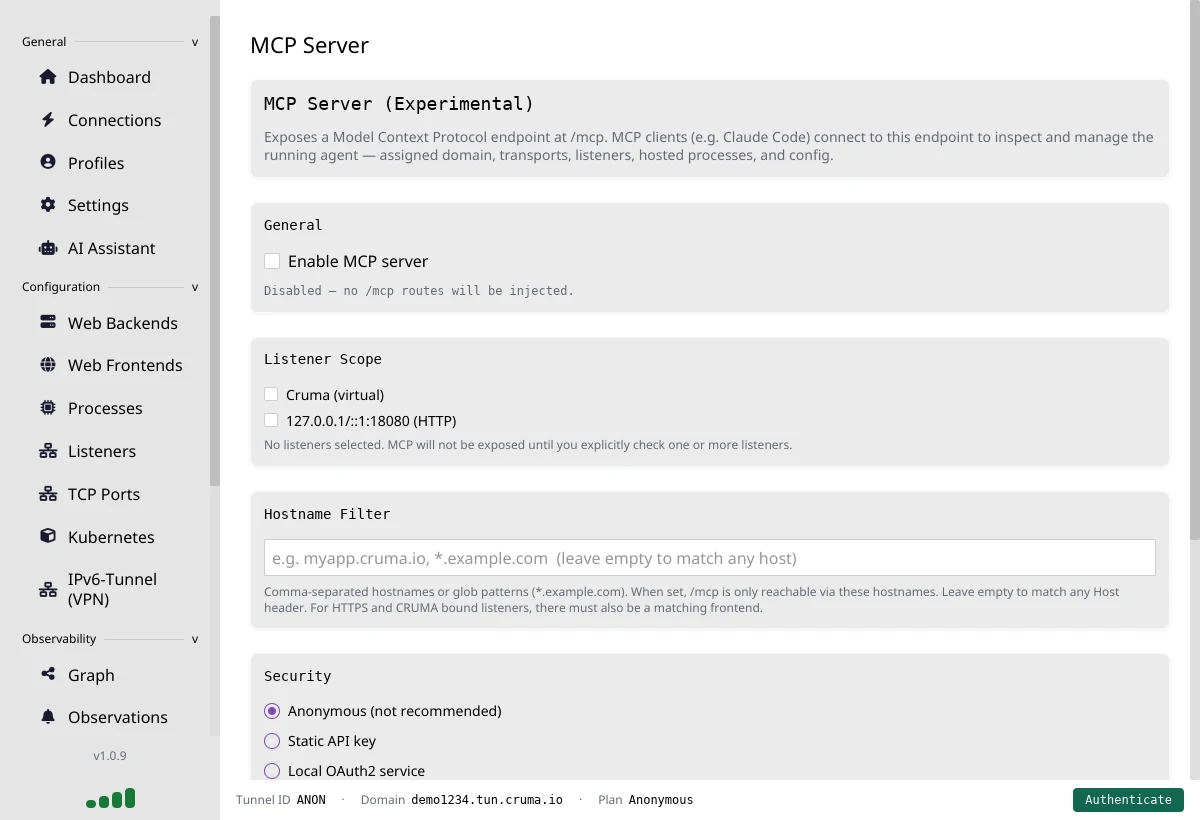
Certificates, auth, the MCP server, notifications, and About have their own pages further down the sidebar. The small signal indicator at the bottom of the sidebar shows tunnel health; clicking it opens Connections.
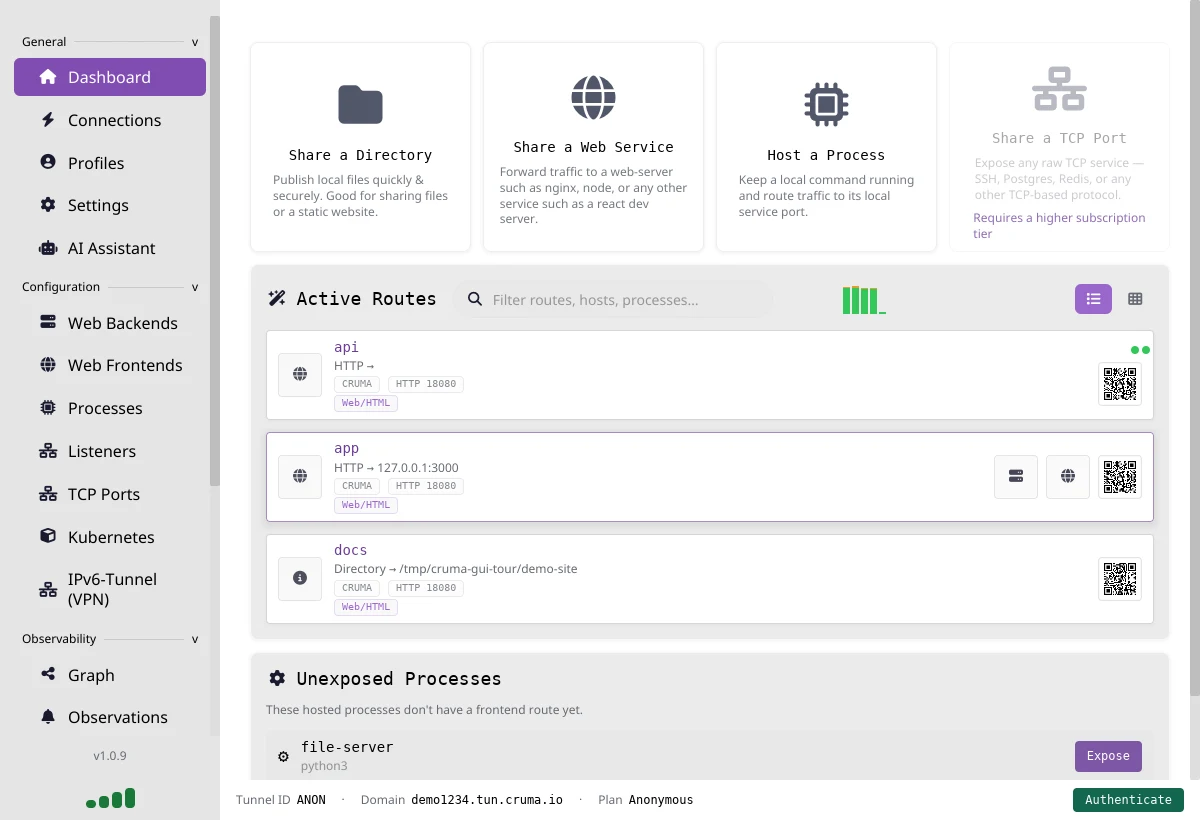
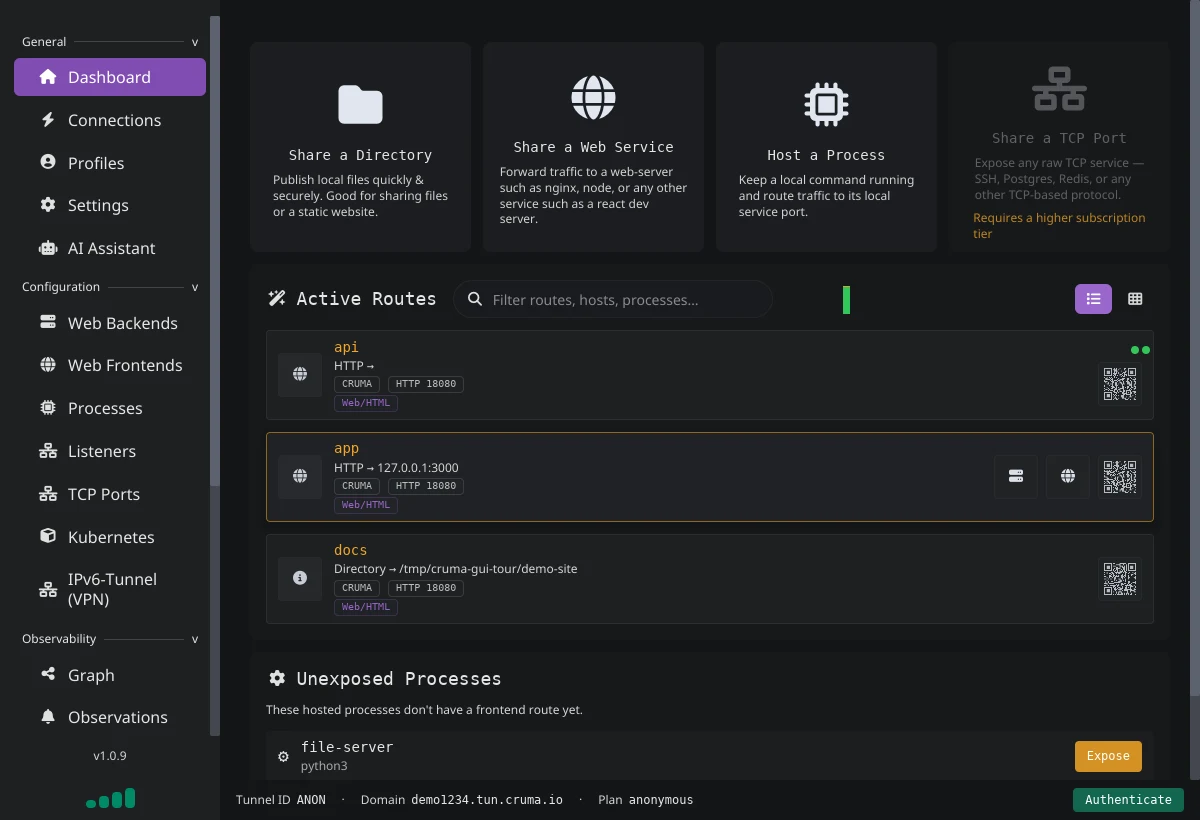
The Dashboard: guided-setup cards, your routes, and processes that aren't exposed yet.
The Dashboard is where you land. From top to bottom it shows:
Guided Setup cards — Share a Directory, Share a Web Service, Host a Process, and Share a TCP Port (greyed out with "Requires a higher subscription tier" on the anonymous plan).
Active Routes — every route you've configured, with its backend, which listeners it is on, and a QR code so you can open it on your phone. You can filter the list and switch between a list and a grid view.
Unexposed Processes — programs Cruma is running that don't have a route yet, each with an Expose button.
Modern or Classic dashboard
The Dashboard has two looks, switchable in Settings under Dashboard Mode:
Modern (the default) — guided-setup cards plus a card per site, each with a QR code and copy and open buttons. Great for grabbing a URL onto your phone.
Classic — a compact route list alongside the observations panel.
📝 The domain follows your agent, not your config
You don't pick your *.tun.cruma.io hostname — it's tied to your agent's identity on disk. Reinstall with the same identity and you get the same domain back. See Custom Domains to put your own domain in front of it.
None of this is GUI-only. The same actions exist as cruma config add … commands, and the --tui interface has pages for listeners, processes, requests, certificates, events, logs, and a QR code for your public URL; they all read the same config file. Mix and match freely — see Configuration for the file format behind the buttons.
Desktop app
Your first site in the app
This is the visual version of the Quick Start: put a service running on your machine on the public Internet without typing a command. It takes about a minute. Before you start, run something locally (for example a dev server on port 3000) so there is something to share.
Start from Guided Setup
Open the Dashboard. At the top are four Guided Setup cards: Share a Directory, Share a Web Service, Host a Process, and Share a TCP Port. Pick the one that matches what you want to share. For a program that is already listening on a port, choose Share a Web Service.
Step 1 of the wizard: say where your service lives and pick a hostname.
The wizard has three steps, shown as 1. Configure, 2. Authentication, and 3. Review. In the first one you fill in:
Service destination — the address and port of your service, such as 127.0.0.1:3000. A bare port number works too.
Upstream protocol — how Cruma talks to your service. Leave it on HTTP for ordinary local servers.
Hostname — a short label. It is added in front of your assigned domain, so myapp becomes myapp. followed by your tunnel domain (for example myapp.abc123.tun.cruma.io). A green preview under the field shows the full address.
Click Next.
Decide who can visit
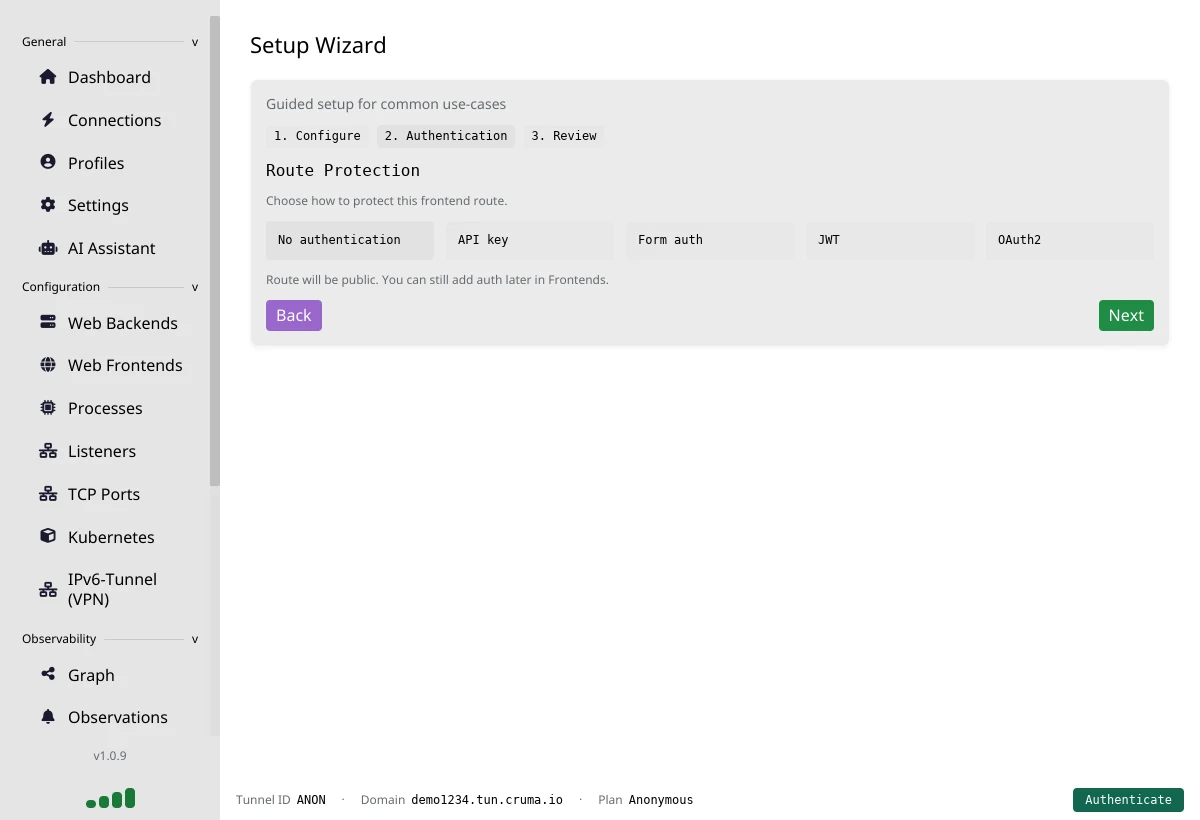
Step 2: choose how to protect the route, or leave it public.
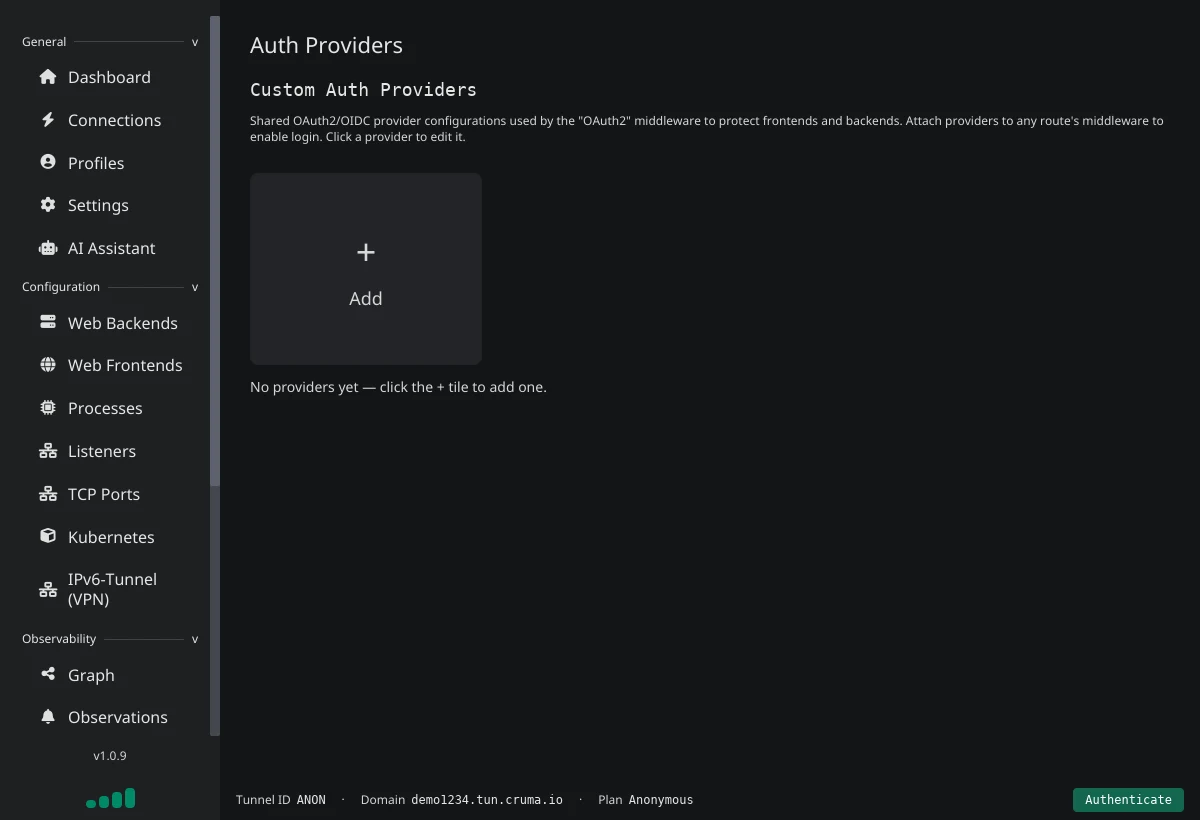
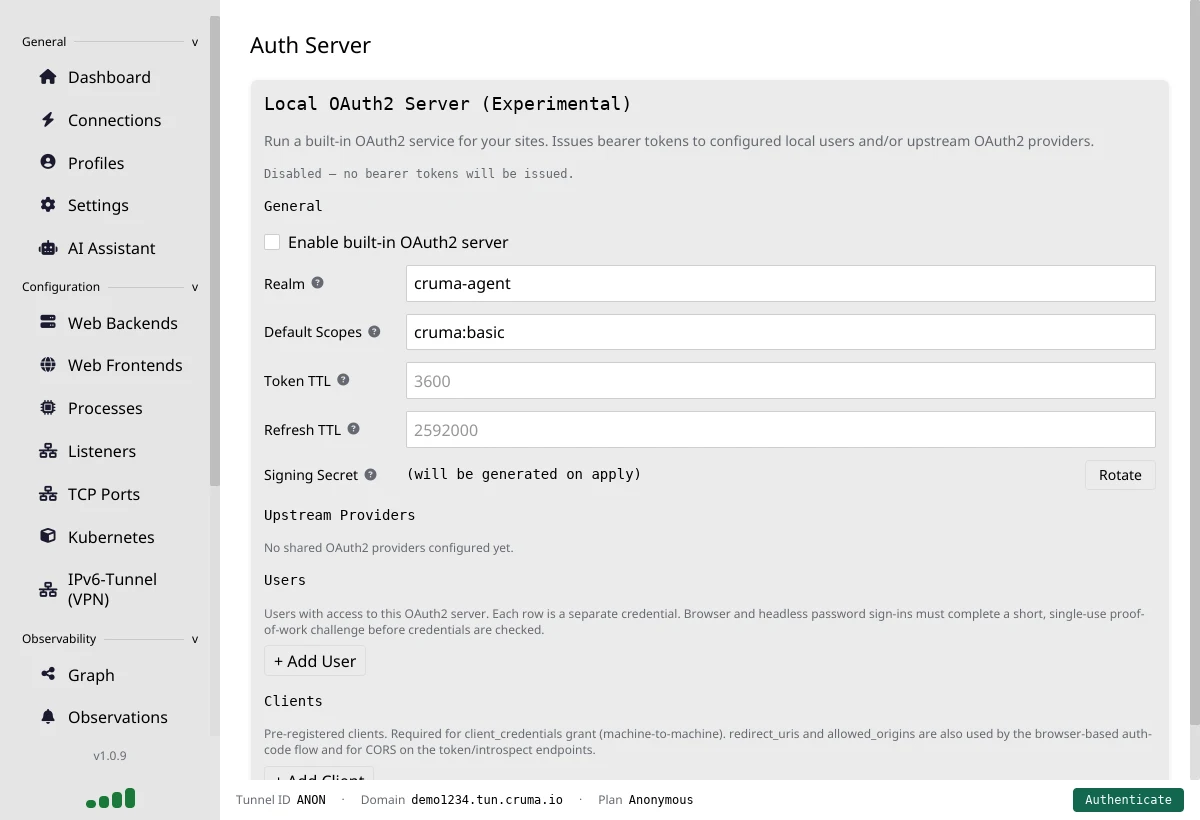
The second step is Route Protection. You can pick No authentication, API key, Form auth, JWT, or OAuth2. With No authentication the page tells you the route will be public; you can still add auth later in Web Frontends. For a first test, public is fine. See Certificates, auth, and MCP for the pages that manage login providers.
Review and save
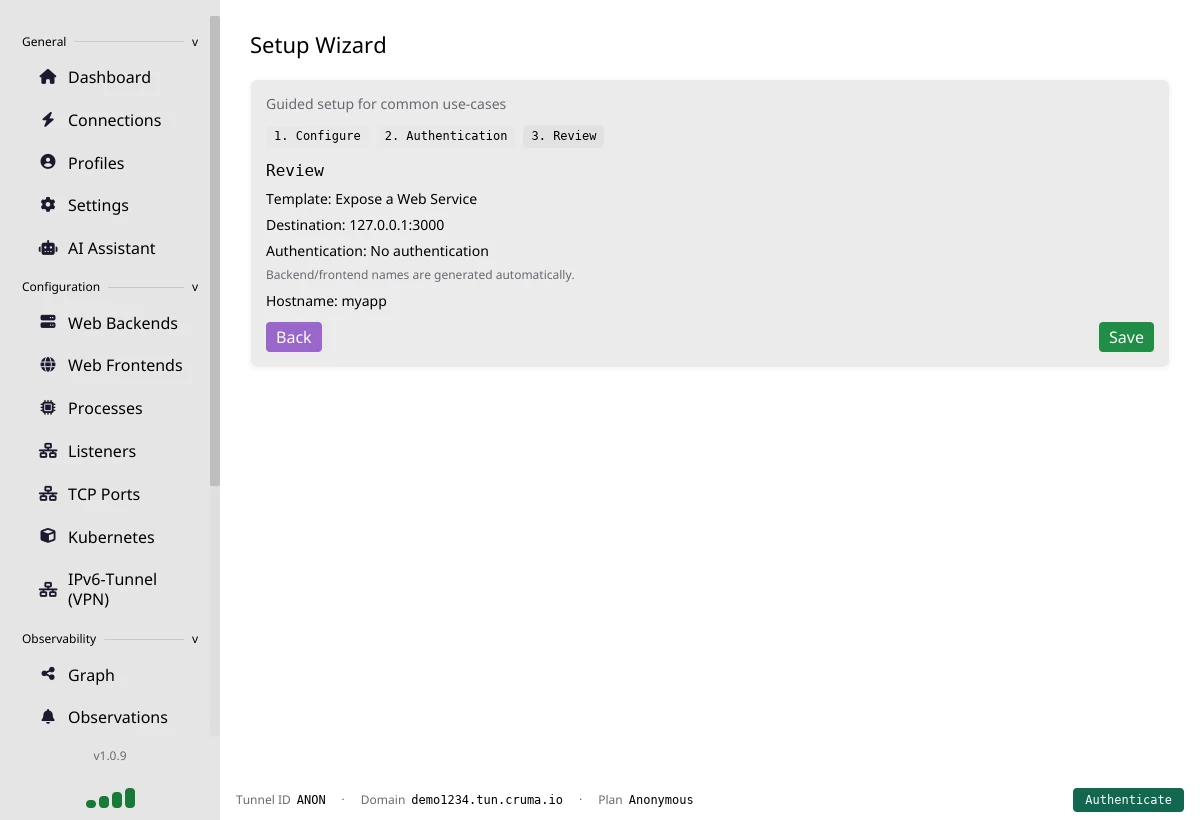
Step 3: check the summary, then save.
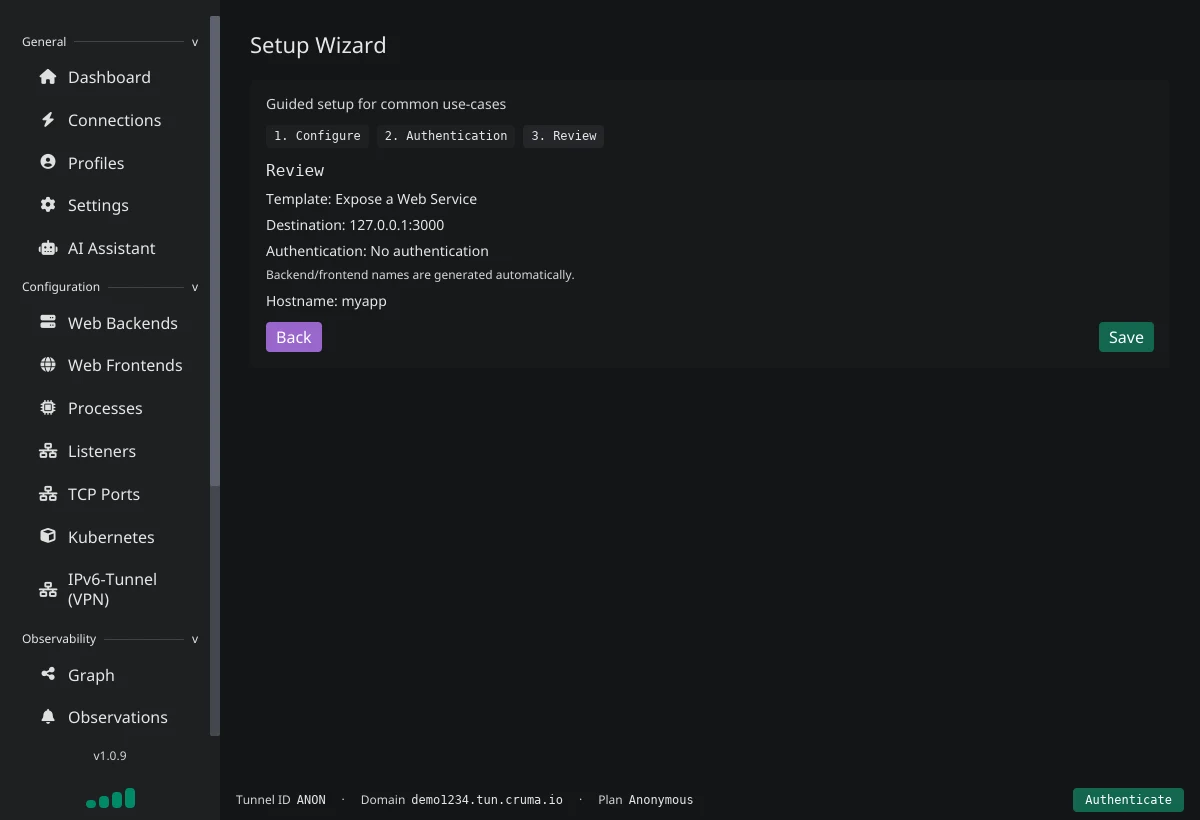
The Review step summarises your choices: the template, the destination, the authentication, and the hostname. A note on the page says the backend and frontend names are generated automatically. If something looks wrong, use Back. Otherwise click Save. Cruma writes the config and applies it right away.
See it on the Dashboard
Back on the Dashboard, your new site appears under Active Routes. Each route has copy and open buttons and a QR code for your phone (in Modern dashboard mode, see The desktop app). Click the open button, or paste the address into a browser. There is no DNS setup and no certificate step; you are live.
💡 Check the tunnel first
If the address doesn't load, look at the signal indicator at the bottom of the sidebar, or open Connections, and confirm the tunnel shows Connected. Also make sure your local service is actually running.
Watch the request arrive
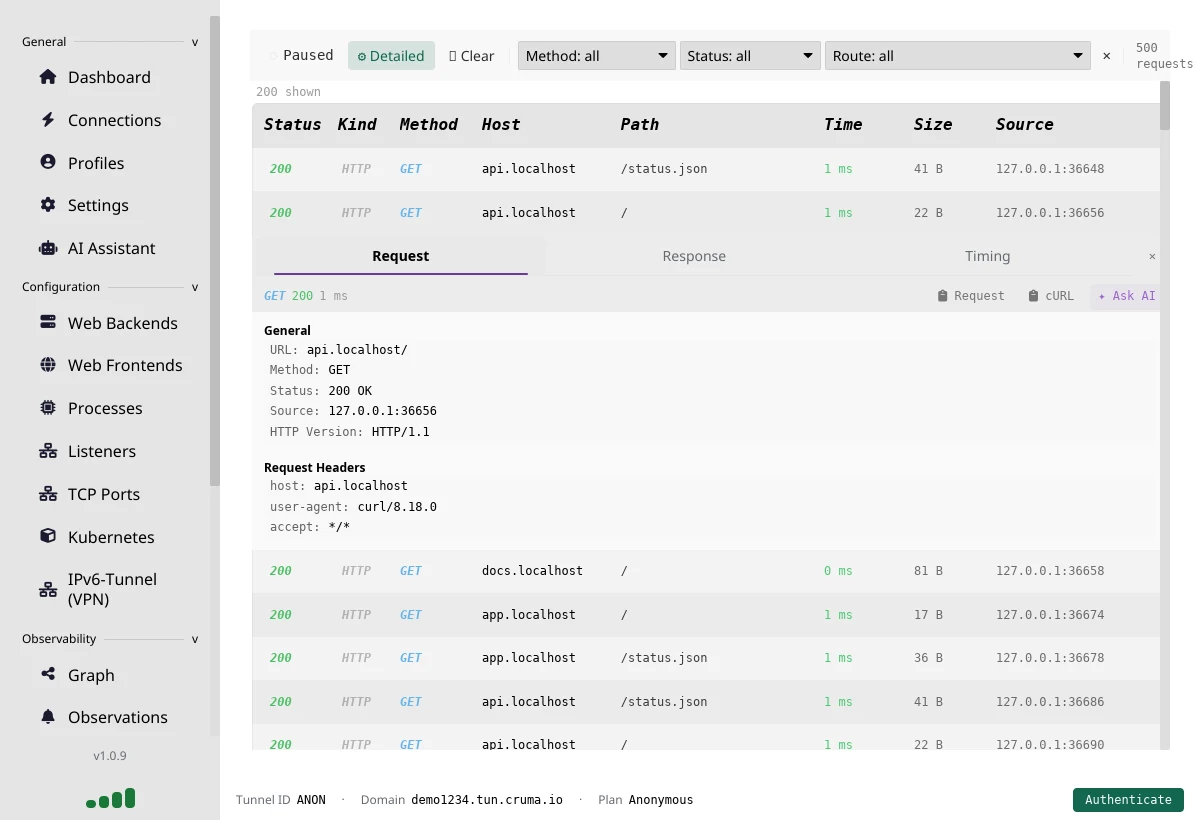
Open Requests in the sidebar, turn recording on, and reload your site. Each request shows up in the list as it happens. Watching your traffic shows how to inspect them.
The manual route: backend, then frontend
The wizard just creates two things for you, and you can make them by hand whenever you want more control:
Go to Web Backends → Add Backend Service, choose HTTP, and enter your local server (e.g. localhost:3000). Save.
Go to Web Frontends → Add Frontend Route, set the match to your assigned domain (or a subdomain of it), and pick the backend you just made. Save.
Open https://<your-domain>. You're live.
That's the whole loop: a door (listener), a rule (frontend), a destination (backend). The next chapter covers each page in detail.
Desktop app
Routing: listeners, frontends, backends, and processes
These are the pages under Configuration in the sidebar. They map directly onto the mental model from The desktop app: a door (listener), a rule (frontend), and a destination (backend or process).
Listeners — where traffic enters
A listener is a door. Cruma has three kinds:
http / https — bind a local port (like 80 or 8443) so browsers on your machine or network can reach you. https also handles the encryption (TLS) for you.
cruma — the tunnel door. It dials out to Cruma's cloud and receives traffic from your public domain. This is what makes a local service reachable from the internet without opening any ports on your router. It is a virtual listener: it has no local socket.
Listeners: the Cruma ingress door, a local HTTP port, and which routes use which.
Each listener is a card with Edit and Remove buttons, and + Add Listener adds another. A local listener shows its port and a Bound badge when it is actually listening. A listener can be configured but fail to bind if another program already holds that port. HTTPS listeners also serve HTTP/3 (QUIC) by default for faster connections.
Below the cards, Route Mapping is a grid of checkboxes: one row per route, one column per listener. Tick the boxes to choose which listeners each route is reachable on. When no box is ticked for a route, it binds to all listeners.
Web Frontends — the routing rules
A frontend answers "when a request comes in for this address, what do I do with it?"
Web Frontends: one row per route, with its backend and a lock on protected routes.
The list shows each frontend, the backend it sends traffic to, whether it has authentication (the lock icon), and its status. Click + Add Frontend Route to create one. Each frontend has:
A match — a hostname and (optionally) a path, e.g. app.example.com or abc123.tun.cruma.io/api.
A target — the backend, process, folder, or Kubernetes service to send it to.
An optional list of middlewares — checks and transforms applied before the target sees the request: login walls, IP allow/deny, rate limits, CORS, header rewrites, and more.
The editor lets you build all of this visually. One hostname can even fan out to different targets by path (an /api route to one service, everything else to another).
Web Backends — the destinations
A backend is where a frontend sends traffic.
Web Backends: an HTTP backend, a load-balanced one, and a directory.
The table lists each backend's Type, Destination, how many Frontends use it, and its Status. Click + Add Backend Service to make a new one. A backend can be:
an HTTP, HTTPS, or TCP address (localhost:3000, or a remote server);
a Directory — Cruma's own built-in static file server for a folder on disk (directory listings, Markdown-to-HTML, single-page-app fallback, image thumbnails).
Load balancing means giving one backend several upstream addresses so Cruma spreads requests across them. In the table, the api backend shows 127.0.0.1:8081 (+1), meaning one more upstream behind it. HTTP backends can also have health checks and a maintenance-mode switch.
Processes — programs Cruma runs for you
A process is a program Cruma starts and supervises, so you don't need a separate terminal for it.
Processes: Cruma starts, stops, and watches your programs.
The page lists each process with its command and a status such as Running, plus a Stop button. Start All, Stop All, and + Add Process sit above the list, and a Global Variables tab holds values shared between processes.
For each process you set its command, arguments, working directory, and environment. Cruma hands the program a PORT environment variable and proxies to that port, so a frontend can point straight at the process. It can restart on crash or when the binary changes, and can start lazily on the first request and stop again when idle. Advanced options include pinning it to specific CPU cores.
💡 Unexposed processes
A process with no frontend is running but unreachable from outside. The Dashboard lists these under Unexposed Processes with an Expose button that creates the route for you.
TCP Ports — non-web services
On the anonymous plan, TCP Ports shows an upgrade notice.
The TCP Ports page is for services that aren't web traffic, such as SSH, Postgres, or Redis. On the anonymous plan, this page only shows "Requires a higher subscription tier" with a note that you need to upgrade to enable IPv6 TCP support and expose direct TCP ports. The matching Share a TCP Port card on the Dashboard is greyed out for the same reason. On a plan that includes it, this is where you manage those ports.
Desktop app
Watching your traffic
The app isn't just for setup. It is also a live lens on what Cruma is doing. These pages answer "is it working?" and "what just happened?"
Requests — every request, inspectable
Requests: a live list, with one request opened for inspection.
Turn on recording and every request through Cruma is captured. The bar at the top has a record toggle (it reads Paused when recording is off), a Detailed switch, Clear, and filters for Method, Status, and Route. A counter on the right shows how many requests are stored.
Each row shows the status, method, host, path, time, size, and the source address. Click a row to open it. The panel has Request, Response, and Timing tabs with headers, status, and body (bodies are truncated at a capture limit). Three buttons copy or hand off the request:
Request copies the request.
cURL copies it as a curl command you can replay in a terminal.
Statistics: totals, error rate, status codes, and a ten-minute traffic chart.
Statistics shows Total Requests, Errors (≥ 400), Avg Latency, and Error Rate, then connection counts (TCP Connections, HTTP/3 (QUIC) Conns, Firewall Blocked), and a count per status class (1xx to 5xx). A Traffic chart covers the last 10 minutes in 10-second buckets. Further down, a Raw TCP Streams section covers non-HTTP traffic.
Observations — logs and events
Observations: a combined log stream from the agent and your hosted processes.
Observations is a searchable log stream from the agent and the processes it hosts. Use the search box, the level filter (here Info+), Wrap for long lines, Tail to follow new lines, and Clear to empty the view. It is the first place to look when a process won't start or a listener won't bind.
Graph and Service Map — two different pictures
Both pages draw diagrams, but they answer different questions:
Graph is drawn from your configuration. It shows what should happen: listeners on the left, then frontends, then the backends they point at.
Service Map is drawn from real traffic. It shows what did happen: who actually talked to which host, and how many times.
Graph: your configured routes, from listener to frontend to backend.
The Graph header counts your backends, frontends, processes, listeners, and unique hostnames. You can filter routes, zoom with + and −, and tick Show unbound to include items that aren't attached to a listener. A lock marks a protected frontend.
Service Map: arrows show who actually called which host, with request counts.
On the Service Map, tick Enable to start collecting. Arrows are labelled with how many requests went from a source to a host, and a legend explains the colours (frontend, managed process, external process, source IP, unknown). Remote IPs adds outside visitors to the picture and Clear resets the counts.
Connections — is the tunnel up?
Connections: the state of your link to Cruma's cloud.
Connections has tabs for Status, Firewall, and WAF. (A Proxy Config tab appears only in debug builds.) Status shows whether Cruma ingress is on, with shortcuts to Edit Listeners and Edit Frontends. Transports lists each connection to the cloud, with its protocol (HTTP/2 or QUIC), status, and last error. Active Streams lists the live streams with their bytes and rates.
Notifications
Notifications: messages from Cruma's servers about your tunnel and plan.
Notifications collects messages from Cruma's servers. On the anonymous plan these include a reminder that anonymous tunnels are limited to 180 minutes of uptime (after that, new visitors see a notice page until you reconnect) and a Tier Info card listing your plan's limits, such as bandwidth, agents per tunnel, and whether TCP ports or HTTP/3 are included.
Desktop app
Certificates, auth, and MCP
These pages control who can reach your sites and how the connection is encrypted. For the bigger picture, including what Cruma can and cannot see, read Security & TLS.
Certificates
Certificates: which certificate covers each of your hostnames.
The Certificates page shows the encryption certificate for each of your HTTPS names and its status. Cruma can obtain and renew free certificates automatically (Let's Encrypt via ACME), use a self-signed one for local testing, or use PEM files you provide. No manual certificate wrangling is required.
The Overview counts your cached certificates and the TLS Coverage tab lists each frontend, the listener it is on, and its mode. On the anonymous plan the page notes that TLS for the Cruma ingress is terminated by cruma.io on your behalf, and that local TLS termination requires a higher subscription tier. The other tabs are ACME Certs, Self-Signed, Local CA, and Activity.
Auth Providers holds shared OAuth2 / OIDC provider configurations. You attach a provider to a route's OAuth2 middleware to put a sign-in in front of a frontend or backend. Click the + tile to add one; there are ready-made templates for common providers such as GitHub. Other protection types (API key, form auth, JWT, and basic auth) are set directly on the route, or in the wizard's Route Protection step.
Auth Server
Auth Server: Cruma's built-in OAuth2 service, switched off by default.
The Auth Server page lets Cruma act as its own OAuth2 provider. It is marked Experimental and starts Disabled. Tick Enable built-in OAuth2 server, then set the Realm, Default Scopes, token lifetimes (Token TTL and Refresh TTL), and a Signing Secret (use Rotate to replace it). You can add Users and pre-registered Clients (needed for machine-to-machine access), and link upstream providers. Password sign-ins must complete a short proof-of-work challenge before credentials are checked.
MCP Server
MCP Server: let an AI coding tool inspect and manage the running agent.
The MCP Server page (also marked Experimental) exposes a Model Context Protocol endpoint at /mcp. MCP clients such as Claude Code connect to it to inspect and manage the running agent: assigned domain, transports, listeners, hosted processes, and config. It starts Disabled. The page has a Listener Scope (nothing is exposed until you tick a listener), an optional Hostname Filter, and Security options: Anonymous (not recommended), Static API key, or Local OAuth2 service.
Connect an AI coding tool to MCP
The MCP Server page can give your AI coding tool a live, controlled view of
the running Cruma agent. Enable the server, select the listener that should
expose it, choose authentication, and then copy the connection example shown
on that page. The examples use your current hostname, port, transport, and API
key, so they stay correct when you change the server settings.
The page includes ready-to-paste setups for Claude Code, Codex, and
OpenCode. Use the generated command or configuration in the corresponding
tool, then ask it to inspect routes, listeners, processes, or the live MCP
status. If you use an API key, treat the generated snippet like a password:
keep it out of shared configuration files and source control.
The Codex example stores the key in CRUMA_MCP_API_KEY. Keep that environment
variable set whenever you start Codex (for example, add it to your shell
profile); an export command only applies to the terminal session where you
run it.
For local-only use, select a loopback listener. To connect from another
machine, use a reachable hostname and protect the endpoint with an API key or
your local OAuth2 service. Builds that include the AI Assistant page can
also use the same local MCP server from that page.
Desktop app
Settings, profiles, and the assistant
The last few pages are housekeeping: how the app looks, which config file it uses, and your built-in helper.
Settings
Settings: config file locations, appearance, and dashboard options.
Settings is organised in cards:
Configuration File — the paths of your config (cruma.yaml), your user settings, and the UI settings file, each with an Open button.
Appearance — Auto follows your system colour scheme, or pick fixed Light or Dark.
Dashboard Mode — the Classic Dashboard switch. Off is Modern (guided-setup cards and stats); on is Classic (a compact route list beside the observations panel).
Dashboard Sections — choose which optional sections appear on the Modern dashboard: Setup wizard cards, Detected local services, and Unexposed processes. Turning off Detected local services also stops the background port scan that finds programs already listening on your machine.
Scroll down for more options, including the tower server (your ingress region, see Quick Start) and auto-start on login.
Profiles
Profiles: keep several config files and switch between them.
A profile is a separate config file. Keep one per project, for example, and switch between them when you want separate public domains or isolated setups. The built-in Home config is your default and shows as Active. Use + New Profile to create a profile, + Add Existing to register a config file you already have, Clone to copy one, and Set default to choose which one opens at launch.
About
About: version, install source, and update status.
About shows the app Version, how it was installed, where the executable lives, and whether you are running the latest version, plus a link to cruma.io. It's the page to quote when you report a problem.
The AI assistant
The AI Assistant page (in the General group of the sidebar) is a chat that understands Cruma and can see your live setup when you allow it. Ask it things like "why isn't my site loading?" or "add a login wall to my API route" in plain English. The Ask AI button on a captured request drops that request straight into the chat.
The assistant needs a provider to talk to, so the first time you open it you sign in or connect one. It can be backed by Anthropic Claude, GitHub Copilot, an OpenAI-compatible endpoint, or the Claude Code CLI, depending on what you connect (some builds also offer a small local model).
📝 Not in every build
The assistant ships in desktop builds. If your build doesn't include the AI Assistant page, you can still connect an external AI tool through the MCP server.
Common Scenarios
Quick recipes for typical setups. Replace SECRET_KEY/TUNNEL_ID with your account credentials, or omit --tunnel-id and --secret-key entirely for anonymous mode.
Config files need a cruma listener
The agent only connects to Cruma cloud when the config contains a listener with kind: cruma. The one-off proxy and serve commands add it for you, but in a config file you declare it yourself — every cloud example below includes it. Leave it out to run as a purely local reverse proxy.
Start your dev server (npm start/yarn start), then run the tunnel.
If your dev server uses HTTPS, use proxy https instead of proxy http.
The target can be <address>:<port>, just <address> (e.g. example.com), or just a port (3000 means 127.0.0.1:3000).
Without --hostname, the tunnel's own address (<tunnel-id>.tun.cruma.io) routes to the target. Pass --hostname app to expose it as app.<tunnel-id>.tun.cruma.io instead, or a full domain for a custom hostname.
API server on port 8080 with custom domain
tunnel_id: "api-demo"
tunnel_secret: "SECRET_KEY"

listeners:
  - kind: cruma

backends:
  - id: api
    kind: http
    destination: "127.0.0.1:8080"

frontends:
  - hostname: "api"
    backend_id: api
  - hostname: "api.dev.yourdomain.com"
    backend_id: api
Run it:
cruma start ./cruma.yaml
CNAME api.dev.yourdomain.com to <tunnel-id>.tun.cruma.io, then add it to the hostname list.
api expands to api.<tunnel-id>.tun.cruma.io. A hostname containing a dot is used as-is; @ (or an empty hostname) means the tunnel's own address.
Or add it to an existing config via CLI:
cruma config add http 127.0.0.1:8080 --hostname api --hostname api.dev.yourdomain.com
Multi-target config file
Use a config file to run multiple targets with one command:
tunnel_id: "demo-tunnel"
tunnel_secret: "beta-secret-123"

listeners:
  - kind: cruma

backends:
  - id: api
    kind: http
    destination: "127.0.0.1:8080"
  - id: web
    kind: http
    destination: "127.0.0.1:3000"

frontends:
  - hostname: "api"
    backend_id: api
  - hostname: "api.dev.yourdomain.com"
    backend_id: api
  - hostname: "react-dev"
    backend_id: web
  - hostname: "react.dev.yourdomain.com"
    backend_id: web
Run it:
cruma start ./cruma.yaml
Backend kind is one of http, https, tcp, or local-directory.
Add --allow-dir-index to enable directory listing when no index file is present.
Add --render-markdown to render index.md (and other .md files) as HTML.
Add --spa to enable SPA fallback: serve the nearest index.html instead of 404 for missing paths.
You can add simple auth with --user USERNAME PASSWORD or --api-key X-API-Key secret123.
In a config file the equivalent backend is kind: local-directory with destination set to the directory path, plus the optional allow_directory_indexing, render_markdown, and spa_fallback booleans. With cruma config add dir ./public, note that --user and --api-key take a single username:password / header:value argument instead of two words.
SPA (single-page application)
If you're building a React, Vue, or similar SPA and want client-side routing to work:
cruma serve ./dist --spa
With --spa, any request that would 404 instead serves the nearest index.html, so your client-side router handles the path.
In a config file, set spa_fallback: true on the backend:
The agent will start the process, restart it according to the restart policy (never, on-failure (default), or always), and route traffic to it. If you omit PORT from env, the agent allocates a free port and passes it to the process as PORT, so your app should listen on process.env.PORT (or the equivalent). $VAR/${VAR} references in args are expanded against the process environment, including that PORT.
Lazy process start (start on request)
You can configure a process to only start when the first request arrives, and optionally stop it after a period of inactivity:
cruma config add process node --arg server.js --start-on-request --hostname app
When a request arrives for a frontend backed by this process and the process is not running, the agent will start it and wait for it to become ready before proxying the request (the wait is bounded by backend_timeout_seconds, or 30 seconds by default). With idle_timeout_seconds, the process is automatically stopped after being idle for the specified duration. Add auto_start: false (CLI: --no-auto-start) if the process should only ever be started on request rather than at agent boot.
Local-only reverse proxy (no cloud tunnel)
The agent only connects to Cruma cloud when a cruma-kind listener is present. Simply don't define one to run the agent as a purely local reverse proxy — no traffic goes through Cruma cloud:
Access your service at https://localhost:8443. If you use a name like web instead of localhost, the loopback listener answers for both web and web.localhost. Listener kind is http, https, or cruma; addr is localhost (default) or all, or set bind_ip for a specific address. cert_mode is self_signed (default) or acme_alpn.
The same is possible for one-off commands with --listen, which replaces the default cruma listener:
cruma proxy http 3000 --listen http:8080
--listen accepts cruma, http:PORT, http:ADDR:PORT, https:PORT, https:ADDR:PORT, and https:[ADDR:]PORT:CERTMODE (where CERTMODE is self-signed or acme-alpn), and can be repeated. HTTPS listeners require an explicit --hostname.
Local listener alongside cloud tunnel
You can have both cloud access and a local listener at the same time:
Now your service is available both at app.<tunnel-id>.tun.cruma.io and http://app.localhost:8080. On local listeners a single-label hostname stays local (app, plus app.localhost on loopback) rather than expanding to the tunnel domain. Frontends attach to all listeners by default; set listener_kinds on a frontend (e.g. ["cruma"] or ["http:8080"]) to restrict it.
High-assurance (pinning/mTLS)
Use a custom hostname (CNAME to <tunnel-id>.tun.cruma.io). The agent automatically obtains a Let's Encrypt certificate via ACME TLS-ALPN-01 and terminates TLS locally — payloads are end-to-end encrypted between clients and your agent by default.
On paid plans with an active subscription, the agent can also terminate TLS for its assigned *.tun.cruma.io hostname after obtaining a certificate via ACME DNS-01. If that process is not ready or fails, Cruma falls back to ingress termination automatically.
For additional hardening, pin your agent's certificate in clients (or use mTLS) so only your cert is accepted.
Set CAA records on your domain to restrict certificate issuance to your chosen CA (and optionally to your specific ACME account).
CORS headers for an API
Use the allow_cors middleware on a frontend:
backends:
  - id: api
    kind: http
    destination: "127.0.0.1:8080"

frontends:
  - hostname: "api"
    backend_id: api
    middlewares:
      - type: allow_cors
        origins: { mode: any }
        allow_credentials: false
        handle_preflight: true
        allow_private_network: false
origins.mode can also be list (origins: [...]), wildcard (patterns: [...]), regex (patterns: [...]), or mirror (allowlist: [...]). Middlewares can be set on a backend too; backend middlewares run before frontend middlewares. They apply to http, https, and local-directory backends, not tcp.
Path-based routing with rewrites
Strip a path prefix before forwarding to the backend:
Available values: H1 (default), H2, H2PK (HTTP/2 Prior Knowledge). H2 is negotiated via ALPN and therefore only takes effect for https backends — on a cleartext http backend it falls back to HTTP/1.1. For cleartext HTTP/2 (gRPC servers, for example) use H2PK.
⚠️ Casing differs between the CLI and the config file
The CLI flag takes lowercase (--upstream-protocol h2). The config-file value is uppercase — H1 / H2 / H2PK. A lowercase upstream_protocol: h2 in YAML/JSON/TOML will fail to parse ("unknown variant h2").
Forwarding the Host header
By default the original Host header is forwarded to your backend (--forward-host defaults to true; forward_host_header: true on a frontend). If your backend expects to be addressed by its own address instead, pass --forward-host=false or set forward_host_header: false on the frontend.
Choose Your Path
Pick the path that matches your experience. Each path gives you a minimal set of steps to get your site reachable.
Beginner: get a site online fast
Not comfortable in a terminal? Start with the desktop app: The desktop app explains the window, and Your first site in the app walks you through the Setup Wizard with screenshots. Prefer the command line? The steps below get you there too.
Static files (your own server): python -m http.server 8080
React/Vite dev server: npm create vite@latest && npm install && npm run dev -- --host --port 3000
Run the tunnel (anonymous mode, no signup):
React/Vite on 3000:
cruma proxy http 3000
If you ran cruma serve, that command already started the tunnel; you can skip this step.
Copy the public URL shown in the terminal UI and open it in your browser.
If it doesn't load, check: is your local server running? Is your firewall blocking the port? Try curl http://127.0.0.1:8080 (or :3000) locally first.
Intermediate: custom domains and multiple services
Prefer the desktop app? Routing covers listeners, frontends, backends, and processes as pages you click through.
Use a config file with backends and frontends (plus a kind: cruma listener for cloud access) to run multiple services from one agent, and start it with cruma start ./cruma.yaml (see Configuration).
Add a CNAME to use your own domain and add that hostname as a frontend route (see Custom Domains).
Let the agent host your app process (cruma config add process ...) so you manage everything in one place (see Common Scenarios).
Review Security & TLS to decide on pinning/CAA for custom domains.
Use separate tunnels for isolation between teams/apps.
Run local-only by omitting a cruma-kind listener for a purely local reverse proxy — no cloud tunnel (see Configuration).
Add middlewares (auth, CORS, header manipulation, path rewrites, redirects, rate limiting) to frontend routes, or fan one hostname out to several backends with path_routes (see Configuration and Common Scenarios).
Bind local http/https listeners next to the cloud tunnel and use --listen on one-off commands to expose a service locally (see Common Scenarios).
Enforce issuance and trust: set CAA on your domain, pin your agent's cert (or use mTLS) for custom hostnames (see Security & TLS).
Multiple Targets and Tunnels
One agent, many targets
You can expose multiple services from a single agent and tunnel. Use the config file to declare multiple backends and frontend routes; you usually do not need separate tunnels for each service on the same machine.
A single backend can also spread load across several local upstreams: replace destination with a destinations list of host:port strings (for http, https, and tcp backends), optionally with a health_check to take failing endpoints out of rotation. And one hostname can fan out to several backends by path prefix with path_routes (see Common Scenarios).
Shared tunnel IDs (important)
A tunnel ID defines the public FQDN and the routing pool at cruma.io. If you run multiple agents with the same tunnel_id, they all share that same public address and traffic is load‑balanced between them.
This is great for multi‑region or multi‑host deployments as long as the configs are the same across those agents. If configs differ (different hostnames, targets, or auth), routing becomes unpredictable because requests may land on a different agent than you expect.
Rule of thumb: if you need different hostnames/routes/configs, use different tunnel IDs. If you want the same public address served from multiple places, keep the same tunnel ID and keep configs identical.
Profiles are separate from tunnel IDs: the profile config key only scopes the agent's cache directory and cached identity (useful for anonymous tunnels), while the tunnel ID controls the public FQDN and routing pool.
Example:
tunnel_id: "demo-tunnel"
tunnel_secret: "beta-secret-123"

listeners:
  - kind: cruma

backends:
  - id: api
    kind: http
    destination: "127.0.0.1:8080"
  - id: web
    kind: http
    destination: "127.0.0.1:3000"

frontends:
  - hostname: "api"
    backend_id: api
  - hostname: "api.dev.yourdomain.com"
    backend_id: api
  - hostname: "react-dev"
    backend_id: web
  - hostname: "react.dev.yourdomain.com"
    backend_id: web
Run with:
cruma start ./cruma.yaml
Multiple frontends can reference the same backend — for example, a shortname (api) and a custom domain (api.dev.yourdomain.com) both routing to the same service. Each frontend points at exactly one target: a backend_id, a process_id (hosted process), or a path_routes table. The kind: cruma listener is what connects the agent to Cruma cloud; without it the config runs as a local-only reverse proxy.
When one tunnel is enough
A few services owned by the same team/environment.
Shared credentials are acceptable (same tunnel secret).
Simple DNS: one tunnel ID with shortnames or custom hostnames.
When to use separate tunnels
You need different hostnames/routes/configs that should not be load‑balanced together.
Isolation per app/team/environment (different credentials and blast radius).
Different domains/hostnames that you want to keep apart.
Different usage profiles or rate-limit buckets.
Multiple agents for the same tunnel
You can run multiple agents with the same tunnel ID for load spreading and regional placement. Each agent connects to its nearest Cruma datacenter; callers are routed to the nearest datacenter where that tunnel is connected. Common patterns:
Regional presence: one tunnel, agents in EU and US to serve users closest to each region.
Simple load sharing: multiple agents behind the same tunnel ID on different servers.
Coordinate credentials and targets carefully when sharing a tunnel across agents. Use distinct tunnels if you need stricter isolation or different routing behavior.
Configuration via file
You can run cruma from a config file instead of passing flags. The CLI accepts YAML, JSON, or TOML (picked by file extension: .json → JSON, .toml → TOML, anything else → YAML) and will validate the structure before starting the tunnel. The agent watches the file and applies changes to credentials and targets automatically.
Quick reference
Command
Description
cruma config locate
Print the default config file path
cruma config init [PATH]
Create a new config with ANON credentials and no targets
cruma config reset
Delete and recreate the default config
cruma config profiles
List known profile IDs
cruma config show
Display the current configuration
cruma config set-credentials <TID> <SK>
Set tunnel credentials
cruma config clear
Remove all frontends, backends, and processes
cruma config add <type> ...
Add a backend + frontend route
cruma config remove <INDEX>
Remove a frontend/backend by index
cruma config remove-process <INDEX>
Remove a hosted process by index
cruma config update <INDEX> ...
Update a target by index
cruma config add-listener <PORT>
Add a local listener
cruma config remove-listener <INDEX>
Remove a local listener by index
cruma config update-listener <INDEX> ...
Update a local listener by index
cruma schema
Print the full JSON schema for the config file
All config subcommands accept -c <PATH> / --config <PATH> to target a specific file instead of the default.
Config file structure
The config file has two required top-level arrays — backends and frontends — plus optional sections for credentials, processes, listeners, and agent behavior.
⚠️ Warning
Older configs that used a flat targets array are no longer supported. The agent will reject them with an error and suggest running cruma config reset --config <path> to migrate.
Note
The agent only connects to the Cruma cloud when the config contains a listener with kind: cruma. A freshly created config (cruma config init, or the file auto-created on first cruma start) includes one; if you write a config by hand, add it yourself or your routes will only be reachable through local listeners (see Local-only mode).
When true, the backend is excluded from traffic and clients get a maintenance response instead (default: false)
backend_timeout_seconds
no
Upstream response timeout in seconds before a 504 is returned. 0 or omitted means the built-in default of 10
upstream_protocol
no
Protocol to the upstream: H1 (default), H2, H2PK. Uppercase in the config file. (http/https only)
middlewares
no
Backend-level middleware list, run before the frontend's middlewares for every frontend that uses this backend
Form-based and API key auth are configured as middlewares on a frontend, not as backend fields — see Access controls below.
destination (and destinations) may reference $cfg_dir (the config file's directory), $root_dir (see root_dir in the top-level reference), or a leading ~ — handy for local-directory backends that should move with the config file.
Load balancing and health checks
Give a backend several upstreams with destinations and Cruma spreads traffic across them. Add a health_check and it will probe each one and route around the ones that fail.
backends:
  - id: web
    kind: http
    destinations:
      - "127.0.0.1:3000"
      - "127.0.0.1:3001"
      - "127.0.0.1:3002"
    health_check:
      kind:
        type: http           # or: { type: tcp } (plain connect check)
        path: "/healthz"     # default "/"
        expected_status: 200 # default 200
      interval_secs: 5       # default 10
      timeout_secs: 2        # default 3
      healthy_threshold: 2   # consecutive OK probes to mark healthy (default 2)
      degraded_threshold: 2  # consecutive failures to mark degraded (default 2)
      down_threshold: 3      # consecutive failures to mark fully down (default 3)
Only kind is required inside health_check; every other field falls back to the default shown. HTTP probes always use plain HTTP, even for https backends.
Set maintenance_mode: true on a backend to take it offline gracefully (clients get a maintenance response) without deleting its config.
Backend kinds
http — connect to the backend over plain HTTP.
https — connect to the backend over HTTPS (TLS to origin).
tcp — forward TCP to the backend. Whether the backend receives plain TCP or the raw (still-encrypted) TLS stream is controlled per-frontend by tcp_terminate_tls — see TCP pass-through below.
local-directory — serve static files from a local directory path.
There is no separate raw backend kind — raw is a CLI convenience (cruma proxy raw / cruma config add raw) for a tcp backend with tcp_terminate_tls: false on its frontend.
Frontends
A frontend maps a hostname pattern to a backend, a hosted process, a Kubernetes target, or a set of path routes. Each hostname gets its own frontend entry.
Field
Required
Description
kind
no
web (default) or tcp. tcp frontends expose a port instead of a hostname — see TCP frontends
Route different paths on this hostname to different targets — see Path-based routing
middlewares
no
Ordered list of HTTP middlewares (see Middlewares) — this is also where form-based and API key auth are configured
listener_kinds
no
Restrict this frontend to specific listeners. Each entry is "cruma", "http:PORT", "https:PORT", or "all". Omitted means all listeners; an empty list detaches the frontend from every listener
request_limits
no
Per-frontend request limits: max_request_body_bytes, max_header_count, max_header_bytes, max_header_name_bytes, max_header_value_bytes, header_read_timeout_secs (default 30), body_read_timeout_secs (off by default). Same block is accepted on path routes and listeners; a route can only tighten a listener's value
forward_host_header
no
Send the client's original Host header to the backend instead of rewriting it to the backend address (default: true)
forwarded_headers_mode
no
What to do with incoming X-Forwarded-*/Forwarded headers: preserve (default — keep and append), strip_incoming (drop what arrived, add fresh ones), or none (backend receives none)
ALPN protocol list offered on the TLS handshake for this route (tcp backends only; must be non-empty when set)
cert_mode_overrides
no
Per-listener certificate mode for custom (non-Cruma-assigned) domains: { https: <mode>, cruma: <mode> } — see Certificate overrides
Exactly one of backend_id, process_id, kubernetes_target_id, or path_routes must be set on a web frontend; combining them is a validation error.
TCP pass-through
For a tcp backend, the frontend's tcp_terminate_tls controls what the backend receives:
true (default) — TLS is terminated before the backend; it receives a plain TCP stream.
false — the raw, still-encrypted TLS stream is forwarded untouched (routed by SNI); the backend must terminate TLS itself (true end-to-end encryption between client and backend).
cruma proxy raw and cruma config add raw are shortcuts that set this to false on a tcp backend automatically; proxy tcp/config add tcp leave it at the true default. Note that those commands create a port-based TCP frontend rather than a hostname-based one.
This only gives true pass-through for CNAME'd custom domains, where TLS always terminates on your agent. For assigned Cruma hostnames (*.tun.cruma.io), where TLS may instead terminate at the Cruma ingress (see Security), tcp_terminate_tls: false still avoids local termination on the agent, but can't control a decision made upstream of it.
TCP frontends
A frontend with kind: tcp exposes a port on the Cruma TCP ingress instead of a hostname. It must reference a tcp backend via backend_id, must set port, and must not set hostname or path_routes. Ports must be unique across tcp frontends.
Let the Cruma edge accept raw TCP connections arriving on the assigned TCP DNS name/port and forward them straight to the backend. When false (default) only connections that arrived through a normal Cruma tunnel are forwarded
tcp_terminate_tls, alpn, listener_kinds
no
As for web frontends
This is what cruma config add tcp <dest> [--port N] and cruma config add raw <dest> [--port N] produce (--port defaults to the destination's port).
Hostname patterns
app — expands to app.<assigned-fqdn> (e.g. app.abc123.tun.cruma.io)
@ (or an empty hostname) — the bare assigned FQDN itself
*@ — the assigned FQDN and all of its subdomains
app.yourdomain.com — exact match on a custom domain (requires CNAME)
*.yourdomain.com — wildcard match for any subdomain
*.api — any subdomain of api.<assigned-fqdn>
app-* — glob match on a single label
* — matches any hostname (not recommended)
On local http/https listeners, single-label names are not expanded with the assigned FQDN: app matches app (and app.localhost on loopback listeners), so local routing stays intuitive.
Multiple frontends can point to the same backend (e.g. a shortname and a custom domain both routing to the same service).
Path-based routing
One hostname can fan out to different targets by URL path prefix using path_routes. Each entry needs a path_prefix and exactly one target (backend_id, process_id, or kubernetes_target_id), and may carry its own request_limits. path_routes replaces the frontend's own backend_id/process_id (setting both is a validation error), so add a / route as the catch-all:
frontends:
  - hostname: "app"
    path_routes:
      - path_prefix: "/"       # catch-all: everything not matched below
        backend_id: web
      - path_prefix: "/api"
        backend_id: api
      - path_prefix: "/admin"
        process_id: admin-app
Longer prefixes win over shorter ones regardless of declaration order, so /api/v2 can override /api. Path routes can target http, https, and local-directory backends (not tcp).
Kubernetes targets
Frontends (and path routes) can point straight at a service in a Kubernetes cluster. Define the target once under the top-level kubernetes_targets, then reference it by id:
For custom (CNAME'd) domains the agent obtains certificates via ACME TLS-ALPN-01 by default; Cruma-assigned hostnames always use Cruma's built-in provider and ignore these settings. To change how a specific frontend gets its certificate, set cert_mode_overrides with a mode per listener kind (https for local HTTPS listeners, cruma for the cloud ingress):
frontends:
  - hostname: "app.yourdomain.com"
    backend_id: web
    cert_mode_overrides:
      cruma:
        type: acme_dns01
        provider: cloudflare
        api_token: "cf-token"
        # zone_id: "..."
      https:
        type: static_pem
        pem_path: "./certs/app.pem"   # key + chain in one bundle
Available modes (type): self_signed, static_pem (pem_path), acme_alpn, and acme_dns01 with a provider of cloudflare (api_token, optional zone_id), hetzner (api_token), digital_ocean (api_token), cruma_dns (api_key), or custom_webhook (url, optional headers). The older single-value cert_mode_override field is still read for backwards compatibility but no longer written.
Processes
The agent can supervise local processes and optionally create frontend routes backed by them. This is useful for running your app server alongside the tunnel in a single command.
Field
Required
Description
id
yes
Stable process identifier
command
yes
Binary or command to run
args
no
List of arguments. $VAR/${VAR} references are expanded against the process's environment (including the auto-allocated PORT) before launch
working_directory
no
Working directory for the process
env
no
Map of environment variables (merged over the top-level global_env; per-process values win)
auto_start
no
Start the process automatically (default: true)
start_on_request
no
Lazily start the process on first incoming request (default: false). The request waits for readiness, bounded by backend_timeout_seconds or 30 s
restart_policy
no
never, on-failure, or always (default: on-failure)
upstream_protocol
no
HTTP protocol to the process: H1 (default), H2, or H2PK. Uppercase in the config file (the CLI flag uses lowercase).
upstream_tls
no
Use HTTPS to connect to the process (default: false)
backend_timeout_seconds
no
Timeout for upstream response in seconds (default: 10)
idle_timeout_seconds
no
Auto-stop the process after being idle for this many seconds. Combined with start_on_request for full spin-up/spin-down lifecycle. 0 or omitted means never auto-stop.
binary_watch
no
React when the executable (or another path) changes on disk: { watch_path?, recursive?, on_change: warn | restart }. watch_path defaults to the resolved binary, or the working directory when recursive: true; on_change defaults to warn
shadow_copy
no
Run from a copied binary so the original can be replaced while running: { scope: BinaryOnly | WorkingDirectory, deterministic_paths?: bool }. scope defaults to BinaryOnly
cpu_affinity
no
all (default — every online CPU, even if cruma itself is pinned), inherit (keep cruma's affinity), or a list of core indices such as [8, 9, 10, 11]
command, args, working_directory, and env values may use $cfg_dir, $root_dir, and a leading ~, just like backend destinations.
To route traffic to a process, add a frontend with process_id instead of backend_id:
Listeners bind to local addresses so you can access your routes directly on localhost (or on a LAN) without going through the Cruma cloud ingress. They share the same routing table as the cloud ingress. The cloud ingress itself is a listener too — the virtual kind: cruma entry — and the agent only connects to the Cruma cloud when one is present (at most one is allowed).
Field
Required
Description
kind
no
http, https, or cruma. When omitted, defaults to https if TLS is enabled, http otherwise.
port
yes
Port number to listen on (ignored for kind: cruma)
addr
no
localhost (default, loopback only) or all (all interfaces)
bind_ip
no
Bind to a specific IP instead of the addr preset
tls
no
Legacy field. Prefer using kind instead.
cert_mode
no
self_signed (default) or acme_alpn (Let's Encrypt via TLS-ALPN-01; requires port 443 reachable from the internet). from_frontend is a legacy alias for acme_alpn — per-frontend cert_mode_overrides always take precedence regardless of the listener's mode.
http3
no
Serve HTTP/3 (QUIC) alongside HTTP/1.1 + HTTP/2 on an HTTPS listener (default: true)
request_limits
no
Listener-wide request limits (same fields as on frontends)
max_connections
no
Cap total concurrent connections on this listener (unset = unlimited)
max_connections_per_ip
no
Cap concurrent connections from a single client IP (unset = unlimited)
There's no dedicated local_only setting. The agent only connects to the Cruma cloud when a cruma-kind listener is present — so to run purely as a local reverse proxy, simply don't define one. Only your local http/https listeners will be active.
backends:
  - id: web
    kind: http
    destination: "127.0.0.1:3000"

frontends:
  - hostname: "web"
    backend_id: web

listeners:
  - kind: https
    port: 8443
Access controls
Form-based and API key auth are middlewares on a frontend (see Middlewares), not backend fields.
Form-based authentication
Form auth provides a built-in login page with signed-cookie sessions:
The authentication middleware also accepts variant: basic (with a users list of [username, password] pairs) and variant: jwt for Bearer-token validation:
      - type: authentication
        auth_type:
          variant: jwt
          # Either a shared HMAC secret …
          secret: "hs256-shared-secret"
          # … or a JWKS endpoint for RSA/EC keys (cached for 5 minutes)
          # jwks_url: "https://issuer.example.com/.well-known/jwks.json"
          issuer: "https://issuer.example.com"     # optional `iss` check
          audience: ["my-api"]                      # optional `aud` check
          algorithms: ["HS256"]                     # default ["HS256"]
OAuth2 / social sign-in
Put a "Sign in with GitHub/Google/…" wall in front of a route. Define the provider(s) once at the top level under oauth2_providers, then reference them from an oauth2 middleware. The middleware needs a session_secret to sign session cookies.
oauth2_providers:
  - id: github
    label: "GitHub"
    client_id: "your-client-id"
    client_secret: "your-client-secret"
    auth_url: "https://github.com/login/oauth/authorize"
    token_url: "https://github.com/login/oauth/access_token"
    userinfo_url: "https://api.github.com/user"
    scopes: ["read:user"]                 # default ["openid", "profile", "email"]
    # For OIDC providers you can instead set `discovery_url` and let Cruma
    # fill in auth/token/userinfo automatically. Other optional knobs:
    # authorize_params: { prompt: select_account }
    # skip_userinfo: true                # id_token already has the claims
    # verify_id_token_signature: true    # check id_token against the JWKS

frontends:
  - hostname: "app"
    backend_id: web
    middlewares:
      - type: oauth2
        provider_ids: ["github"]     # which providers to offer
        session_secret: "replace-with-a-random-secret"
        # callback_path: "/_cruma_auth/callback"   # default
        # logout_path: "/_auth/logout"             # default
        # session_ttl_secs: 3600                   # default
With a single provider the user is redirected straight to it; with several, a picker page is shown. The oauth2 middleware shares the cookie options of form_auth (cookie_name defaults to cruma_oauth2_session).
Cruma can also act as its own OAuth2 authorization server (issue tokens to your apps) via the top-level local_oauth2_server block and the desktop app's Auth Server page. When enabled: true, it is mounted at /_cruma_auth on every TLS listener, and the reserved provider id local-oauth2 can be listed in an oauth2 middleware's provider_ids to offer its local login:
local_oauth2_server:
  enabled: true
  realm: "my-realm"
  default_scopes: ["read"]
  users:
    - username: alice
      password: "alice-pass"
      # scopes: ["read", "write"]      # empty = inherits default_scopes
  clients:                              # pre-registered clients (client_credentials + code flow)
    - client_id: my-app
      client_secret: "app-secret"
      redirect_uris: ["https://app.example.com/callback"]
      # scopes: [], allowed_origins: []
  upstream_provider_ids: ["github"]     # show these oauth2_providers on the local login page
  token_signing_secret: "replace-me"    # generated automatically by the GUI when omitted
  # token_ttl_secs: 3600, code_ttl_secs: 300, refresh_token_ttl_secs: 2592000
Middlewares
Frontends support an ordered list of HTTP middlewares. Backend middlewares run first, then the frontend's, each in the order listed. tcp backends have no HTTP phase and therefore accept no middlewares.
Fixed-window rate limiting by IP, header, cookie, or composite key
cache
In-memory response cache for GET requests (max_size_bytes, default_ttl_secs, max_entry_size_bytes, max_ttl_secs, distributed)
compression
Compress responses to the client (to_client) and/or strip Accept-Encoding towards the origin (decompress_to_origin); optional min_bytes
inject_script
Inject <script>/<link>/<style> tags into every HTML response (entries, optional local_only)
cruma_assistant
Enable Cruma's site-local assistant widget and API for this site
Note: X-Forwarded-Proto, X-Forwarded-For, and X-Forwarded-Host headers are automatically added by the proxy runtime — you don't need to configure them (see forwarded_headers_mode on the frontend to change how incoming ones are handled).
Use cruma schema to see the full JSON schema with all middleware fields and validation rules.
Managing configs with the CLI
Adding targets
The cruma config add command creates a backend and a frontend route in one step:
# Add an HTTP target
cruma config add http 127.0.0.1:3000 --hostname react-dev

# Add an HTTPS target with multiple hostnames
cruma config add https example.com:443 --hostname api --hostname api.dev.yourdomain.com

# Add a TCP target (exposes a TCP frontend on the destination port, or --port)
cruma config add tcp 127.0.0.1:5432
cruma config add tcp 127.0.0.1:5432 --port 15432

# Add a raw TCP target (no TLS termination)
cruma config add raw 127.0.0.1:4943

# Add a local directory with auth
cruma config add dir ./public --hostname docs --enable-index true --render-markdown --user admin:pass123

# Add a hosted process with a frontend route
cruma config add process node --arg server.js --hostname myapp --env "PORT=3000" --restart on-failure

# Add a process that starts lazily on first request
cruma config add process node --arg server.js --hostname myapp --start-on-request

# Add a process without auto-starting it
cruma config add process node --arg server.js --no-auto-start
http, https, and dir targets also accept --api-key "Header:value" to require an API key. If the destination/path is omitted the CLI prompts for it.
Inspecting configuration
cruma config show
This prints an indexed view of all backends, frontends, processes, and listeners, which you need for remove and update commands.
Updating targets
# Change destination
cruma config update 0 --dest 127.0.0.1:4000

# Add/remove hostnames
cruma config update 0 --add-hostname new-host --remove-hostname old-host

# Clear all hostnames at once
cruma config update 0 --clear-hostnames

# Add form auth user
cruma config update 0 --add-user admin:password

# Clear all form auth users
cruma config update 0 --clear-users

# Set API key auth
cruma config update 0 --api-key "X-API-Key:secret123"

# Clear API key auth
cruma config update 0 --clear-api-key

# Enable/disable directory indexing (for directory targets)
cruma config update 0 --enable-index true

# Enable/disable markdown rendering (for directory targets)
cruma config update 0 --render-markdown false
Removing targets
# Remove by index (see 'config show' for indices)
cruma config remove 0

# Remove a process
cruma config remove-process 0

# Remove a listener
cruma config remove-listener 0
# Use the default config file (created with a cruma listener if it doesn't exist yet)
cruma start

# Use a specific file
cruma start ./cruma.yaml

# Shorthand: use -c / --config on the top-level command
cruma -c ./cruma.yaml
--tower-server <HOST:PORT> on the top-level command overrides the file's tower_server.
Default config vs. multiple configs
The default config file is just a convenience. You can run multiple agents by pointing each one at a different config file (with a different profile set in each config):
Use multiple configs when you want separate tunnel credentials or distinct target sets per agent. If you only need one agent with multiple services, keep a single config file and add multiple targets.
Top-level settings reference
Field
Required
Default
Description
backends
yes
[]
Backend services
frontends
yes
[]
Frontend routes
tunnel_id
no
ANON
Tunnel ID for the public FQDN
tunnel_secret
no
ANON
Tunnel secret key
tower_server
no
tower.cruma.io:443
Control plane endpoint. Read from the file but not written back when the CLI/GUI saves it — prefer the --tower-server flag if you also edit the config with those tools
profile
no
—
Named profile to scope cached identity
temp
no
false
Use a temporary identity (fresh FQDN each run)
processes
no
[]
Hosted processes supervised by the agent
listeners
no
[]
Listeners: local http/https sockets and the virtual cruma cloud ingress
kubernetes_targets
no
[]
Named Kubernetes services frontends can target
oauth2_providers
no
[]
OAuth2/OIDC sign-in providers referenced by oauth2 middlewares
local_oauth2_server
no
—
Configuration for Cruma acting as its own OAuth2 authorization server
global_env
no
{}
Environment variables shared by all hosted processes (per-process env wins on conflicts)
acme_directory
no
Let's Encrypt production
Which ACME CA to use: { authority: lets_encrypt, staging: false }, { authority: zero_ssl }, { authority: google_trust_services }, or { authority: custom, url: "…" }. ZeroSSL and Google require acme_eab and do not support TLS-ALPN-01
acme_eab
no
—
External Account Binding for CAs that need it: { key_id: "…", hmac_key: "…" }
root_dir
no
current working directory
What $root_dir / ${root_dir} expands to in config values. A relative value is resolved against the config file's directory; ~ and $cfg_dir are allowed
max_tunnel_connections
no
unlimited
Cap on concurrent tunnel ingress streams; extra streams are dropped
performance
no
—
Data-plane tuning, applied on restart: thread_per_core (auto default, on, off), tpc_cores, tpc_pin (Linux only), pool_max_idle_per_host (default 512), pool_idle_timeout_ms (default 30 s), upstream_retry (default true), io_uring (default true; native completion-based plane where supported, silently falls back otherwise). Environment variables such as CRUMA_IO_URING=0 override the file
Notes:
profile and temp are mutually exclusive.
Changes to tower_server, profile, or temp require a restart to take effect.
Credentials, backends, frontends, listeners, oauth2_providers, and kubernetes_targets are hot-reloaded when the config file is saved.
Anywhere a path or destination is expected you can write $cfg_dir (directory of the config file), $root_dir, or a leading ~; the raw form is preserved when the CLI/GUI writes the file back.
There's no local_only field — omit a cruma-kind listener to run without the cloud tunnel (see Local-only mode above).
Bring your own domain
📝 Subscription required
Custom domains are available on subscribed (Basic/Pro) plans only. Anonymous tunnels and free/unsubscribed accounts cannot use custom domains or CNAMEs.
Each tunnel gets an assigned FQDN based on your tunnel ID (e.g., <tunnel-id>.tun.cruma.io). To use your own domain, add a CNAME and include that hostname in a frontend route.
Add the CNAME
Create a CNAME in your DNS provider pointing to the tunnel FQDN:
Add the custom hostname as a frontend that references your backend. The kind: cruma listener is what connects the agent to Cruma cloud — without it the config only serves local listeners:
tunnel_id: "demo-tunnel"
tunnel_secret: "beta-secret-123"

listeners:
  - kind: cruma

backends:
  - id: web
    kind: http
    destination: "127.0.0.1:3000"

frontends:
  - hostname: "react-dev"
    backend_id: web
  - hostname: "app.yourdomain.com"
    backend_id: web
Multiple frontends can point to the same backend — here both the shortname (react-dev, which expands to react-dev.<tunnel-id>.tun.cruma.io) and the custom domain (app.yourdomain.com) route to the same service. A hostname containing a dot is treated as a fully-qualified custom domain; a single label is expanded under your assigned FQDN.
Wildcard hostnames
You can also use wildcard patterns for custom domains:
frontends:
  - hostname: "*.yourdomain.com"
    backend_id: web
This requires a wildcard CNAME (or individual CNAMEs for each subdomain) pointing to your tunnel FQDN.
Note that the default TLS-ALPN-01 issuance (below) cannot produce wildcard certificates. With a wildcard frontend the agent instead obtains a certificate per concrete hostname, on demand, the first time a client connects to it — so the first request to a new subdomain is slower while the certificate is issued. If you want a single real wildcard certificate, use a DNS-01 override with your DNS provider (see below).
Wildcards under your assigned hostname are limited: the Cruma ingress only routes a single label in front of the assigned FQDN, so a pattern like *.sub (meaning *.sub.<tunnel-id>.tun.cruma.io) is not reachable through the cloud tunnel. Use plain shortnames (api, app-*) or * instead.
TLS for custom hostnames
Once DNS propagates, your custom hostname will resolve through the tunnel just like the assigned address.
TLS for custom hostnames is terminated on your agent, not on Cruma's servers. The agent automatically obtains a trusted certificate via ACME TLS-ALPN-01 — no manual certificate setup is needed. This means payloads are encrypted end-to-end between the client and your agent; Cruma infrastructure only forwards the encrypted TLS stream.
A few details worth knowing:
Certificate authority. Let's Encrypt production is used by default. The top-level acme_directory setting switches to Let's Encrypt staging, ZeroSSL, Google Trust Services, or any custom ACME directory URL; CAs that require External Account Binding take their credentials from acme_eab.
Where certificates live. Issued certificates, their private keys, and the ACME account key are stored in the agent's cache directory (cruma show-cache prints the path). They stay on your machine — they are not uploaded to Cruma. cruma clear-cache deletes them, and the agent will simply re-issue on the next run.
Renewal. The agent checks its cached certificates every minute and logs a warning when one has less than 7 days left (and an error under 24 hours). TLS-ALPN-01 certificates for custom domains are replaced on demand: when a client connects and the cached certificate is no longer valid, the agent obtains a new one during that connection. The assigned-hostname certificate (DNS-01, see below) is renewed proactively in the background once fewer than 7 days remain. Certificates for hostnames no longer in your configuration are left alone and eventually expire.
Bringing your own certificate. Per-frontend cert_mode_overrides let a custom domain use a static PEM bundle (static_pem with pem_path), a self-signed certificate, TLS-ALPN-01 explicitly, or ACME DNS-01 with a Cloudflare, Hetzner, DigitalOcean, or generic webhook DNS provider. Overrides are only honoured for custom domains — assigned Cruma hostnames always use the built-in flow described next.
TLS for assigned hostnames
Assigned Cruma hostnames (<tunnel-id>.tun.cruma.io and *.<tunnel-id>.tun.cruma.io) have two modes:
On paid plans with an active subscription, the agent obtains a certificate covering both the assigned FQDN and its *. wildcard via ACME DNS-01. The DNS challenge records are published for you through the tunnel's control connection, so nothing needs configuring. Once that certificate is cached and valid, the agent advertises to Cruma that it can terminate TLS for those hostnames itself, and the ingress forwards the encrypted stream to it.
Without an active plan, or while issuance is still in progress or has failed, TLS for assigned hostnames is terminated at the Cruma ingress using Cruma-managed certificates. Traffic keeps working either way.
You can see the current state of every hostname — which certificate covers it and whether it is agent- or ingress-terminated — on the TLS Coverage tab of the Certificates page in the desktop app (see Security in the app).
For additional hardening, you can set CAA records on your domain to restrict certificate issuance and consider pinning or mTLS. See Security & TLS for details.
Rate Limits & Fair Use
Cruma.io is built by a small team with limited resources. There is no formal SLA; we will do our best to keep tunnels responsive and reliable. Fair-use limits protect shared capacity.
What to expect
Throughput/latency: Best-effort. Typical dev workloads (web apps/APIs) should feel snappy; heavy load tests or bulk transfers may be throttled.
Concurrent tunnels/targets: Keep to a small number per beta account.
Request/byte volume: We monitor request counts and bandwidth. Sustained high volume may be rate-limited.
Burst control: Sudden spikes can be shaped to keep the service healthy for everyone.
How the agent identifies itself
Which tier applies to you is decided by how the agent registers:
Anonymous: when tunnel_id and tunnel_secret are left at their default (ANON), or you run a one-off cruma proxy/cruma serve without --tunnel-id/--secret-key. On first run the agent generates an Ed25519 keypair in its cache directory and signs every registration with it; your anonymous FQDN is bound to that key, so it stays stable across restarts as long as the cache is kept. cruma clear-cache (or temp: true in the config) gives you a fresh anonymous identity and a new FQDN; profile: <id> keeps several stable anonymous identities side by side.
Registered/Subscribed: set tunnel_id and tunnel_secret (or cruma config set-credentials <id> <secret>). The agent still signs with a per-tunnel-ID keypair from the cache, so the same identity is reused across restarts.
When the connection is established the server tells the agent which plan (if any) is active. The agent uses that to size its transport to Cruma: anonymous tunnels open 1 HTTP/2 + 1 QUIC channel, registered accounts without a plan 1 HTTP/2 + 2 QUIC, and subscribed accounts 2 HTTP/2 + 2 QUIC. The server also pushes a tier snapshot the agent records in its log: the per-stream rate limit, the maximum number of agents per tunnel, channels per agent, concurrent streams per channel, site-list entries, and whether TLS passthrough and control features such as DNS-01 issuance are allowed for the tier.
When you are throttled or disconnected
Per-stream bandwidth shaping happens on the Cruma side; the agent does not need to do anything and the connection stays up.
If the tunnel connection drops, the agent reconnects automatically with an increasing backoff. Authentication failures (wrong tunnel_id/tunnel_secret) use a longer backoff and clear the assigned hostname in the UI until credentials are accepted again.
You can put your own ceiling on inbound load with the top-level max_tunnel_connections config key: streams arriving through the tunnel beyond that number are dropped and the client sees a connection error. Leave it unset for no local cap.
Custom domains
Custom hostnames routed via CNAME are only available on subscribed (Basic/Pro) plans. Anonymous and free/unsubscribed (registered) tunnels cannot use custom domains.
Tiers and typical limits
Anonymous: Intended for quick, disposable tests. Hard limits apply:
No custom domains (CNAMEs)
Max 3 hours of uptime per session
Max 1 GB of traffic per session
Max 1 million requests per session
Free/Unsubscribed (Registered): Higher allowances than anonymous; suited for sustained dev use, moderate bandwidth, and a handful of tunnels/targets.
No custom domains (CNAMEs)
Subscribed (Basic/Pro): Highest allowances and more headroom on concurrency and throughput. Custom domains supported. Exact limits may evolve; the goal is to support heavier workloads reliably.
Bandwidth per TCP stream (caller ↔ target):
Anonymous: ~1 MB/s per stream
Registered: ~5 MB/s per stream
Subscribed: ~10 MB/s per stream
Agent and tunnel connection limits
The server enforces per-tier limits on how many agent processes may connect to a single tunnel at once and how many channels each agent may hold; the agent receives these values at connect time (see above). The exact numbers are being refined and will be better defined after the beta period.
For registered accounts, runner capacity is also counted across the account's tunnels. Runners behind the same office, VPN, or NAT are counted by the authenticated account and tunnel identity, not by their shared public IP address. This lets a legitimate fleet share an egress IP while still preventing one account or one tunnel from consuming all available runner capacity.
Security and TLS
Where TLS terminates
Assigned Cruma hostnames (<tunnel-id>.tun.cruma.io and *.<tunnel-id>.tun.cruma.io): On paid plans with an active subscription, the agent obtains a certificate covering both names via ACME DNS-01 and takes over TLS termination itself. Once the certificate is cached and valid, the agent tells the cloud service which hostnames it can terminate, and TLS for those hostnames ends on the agent. If certificate issuance is unavailable (no active plan), still in progress, or fails for any reason, TLS falls back to the Cruma ingress using Cruma-managed certificates.
Custom CNAME hostnames: TLS is terminated on your agent using a certificate automatically obtained via ACME TLS-ALPN-01 (Let's Encrypt by default). Cruma infrastructure never sees the plaintext payload for these hostnames — it only forwards the encrypted TLS stream to your agent, which terminates it locally. You can replace the automatic certificate with your own PEM bundle or a DNS-01-issued one via per-frontend cert_mode_overrides (see Custom domains).
Local TLS listeners: https listeners use self-signed certificates by default (cert_mode: self_signed, good for local development) or ACME TLS-ALPN-01 (cert_mode: acme_alpn, requires port 443 reachable from the internet). The same per-frontend cert_mode_overrides apply here. See Configuration for details.
TCP backends: terminate or pass through
A tcp backend's frontend has a tcp_terminate_tls setting (see Configuration) that affects what happens after TLS termination. cruma proxy tcp/config add tcp leave it at its default (true); cruma proxy raw/config add raw set it to false:
Assigned Cruma hostname
CNAME'd custom domain
tcp_terminate_tls: true (tcp)
Agent terminates TLS when the assigned-hostname certificate is ready; otherwise Cruma ingress terminates TLS. Backend always receives plain TCP.
Agent terminates TLS (ALPN-01) → plain TCP to backend
tcp_terminate_tls: false (raw)
If the assigned hostname is agent-terminated, the agent terminates TLS and the backend receives plain TCP. If not, Cruma ingress terminates TLS and the backend still receives plain TCP.
Cruma forwards the encrypted TLS stream → agent passes it through untouched (routed by SNI) → backend handles TLS
Key takeaway: raw (tcp_terminate_tls: false) only provides true end-to-end TLS pass-through (where the backend terminates TLS itself) when using a CNAME'd custom domain. With assigned Cruma hostnames, TLS is still terminated before the backend, either on the agent or at the Cruma ingress, so raw and tcp both result in plain TCP at the backend.
Because TCP frontends have no HTTP phase, HTTP middlewares (including the authentication middlewares below) do not apply to them — the agent logs a warning and ignores them. Use the firewall to restrict TCP routes by source IP.
What we can see
Assigned Cruma hostnames: Visibility depends on where TLS terminates for that hostname. If the agent has successfully provisioned its assigned-hostname certificate and is actively terminating TLS, Cruma only forwards the encrypted stream. If the hostname is still using fallback ingress termination, payloads are technically accessible to Cruma infrastructure. Today we only handle what's needed for routing and telemetry (e.g., request counts, health checks) and do not run MITM or payload-inspection features. If we ever add a feature that needs payload inspection, it would be explicitly opt-in.
Custom CNAME hostnames: Cruma sees only control-plane metadata (tunnel ID, target types, health/connection status) plus request/byte counts for abuse prevention. Because TLS terminates on your agent via ACME TLS-ALPN-01, payloads remain end-to-end encrypted between the client and your agent.
What the agent sends to Cruma
Over the control connection the agent sends: its version and operating system name, your tunnel ID and secret, the agent's public key and a signature proving it holds the matching private key, the list of hostnames it serves (with their type — HTTP or TLS — and whether it can terminate TLS for each), and, for assigned-hostname certificates, the DNS-01 challenge values to publish. The connection to the control tower is itself TLS, verified against your operating system's trust store.
Certificates and their private keys are not uploaded: they are stored only in the agent's local cache directory.
Assigned-hostname certificate flow
For eligible paid tunnels, the agent obtains a certificate for its assigned <tunnel-id>.tun.cruma.io hostname and the *.<tunnel-id>.tun.cruma.io wildcard using ACME DNS-01. The challenge records are published through the tunnel's control connection. After the certificate is ready, the agent advertises the hostnames as agent-terminated and Cruma forwards the encrypted stream instead of terminating it.
If that process cannot complete, traffic continues to work with the normal fallback: the Cruma ingress terminates TLS using Cruma-managed certificates.
The Certificates page in the desktop app (TLS Coverage tab) shows the current state of this handoff so you can see whether the assigned hostname is agent-terminated or still using cloud termination.
How custom-domain TLS works
When you CNAME a custom hostname to your tunnel FQDN, the agent automatically provisions a certificate using the ACME TLS-ALPN-01 challenge (Let's Encrypt by default; acme_directory selects another CA). This happens transparently — you don't need to configure certificates manually. The Cruma ingress routes the raw TLS connection to your agent, which presents the certificate and terminates TLS locally.
This means:
Clients connect with a valid, publicly trusted certificate.
The payload is encrypted end-to-end between the client and your agent.
Cruma infrastructure forwards the encrypted stream but cannot decrypt it.
Inspection and opt-in
Ingress-terminated traffic can be inspected in principle because TLS ends on Cruma. No payload inspection is performed today beyond what's required to operate the service; any future feature needing payload visibility would be opt-in.
For custom CNAME hostnames, your agent terminates TLS and Cruma cannot inspect payloads. For additional hardening, see the CAA and pinning options below.
Hardening options (custom domains)
The automatic ACME TLS-ALPN-01 issuance on your agent already provides strong end-to-end encryption for custom domains. The options below are for users who want additional guarantees.
CAA records (restrict certificate issuance)
Set CAA records on your custom domain to restrict which Certificate Authority can issue certificates for it. This prevents anyone (including Cruma infrastructure) from obtaining a certificate for your hostname through a different CA or ACME account.
Example — permit only Let's Encrypt:
app.yourdomain.com. CAA 0 issue "letsencrypt.org"
For tighter control, use accounturi to limit issuance to your agent's specific ACME account:
If your security model requires it, you can pin the certificate your agent presents for custom hostnames. Clients will reject any different certificate, preventing a silent MITM even if someone were to obtain a valid cert for your domain through another path. Pinning is advanced and makes certificate rotation more complex — use it only when your threat model demands it.
Combine CAA with pinning (or mTLS) for the strongest guarantees: CAA restricts who can issue a certificate, and pinning ensures clients only accept the specific certificate your agent presents.
Restricting who can access a route
TLS secures the channel; access control decides who is allowed through. Access control is configured as per-frontend (or per-backend) middlewares (see Configuration → Access controls):
basic_auth — HTTP Basic, a static user list. Simplest, good for quick internal tools.
form_auth — a hosted login page with signed-cookie sessions.
oauth2 — "Sign in with GitHub/Google/…" via an OAuth2/OIDC provider; Cruma can also run as its own OAuth2 server (local_oauth2_server).
authentication — Basic, API key (a required header/value pair), or JWT bearer tokens verified with a shared HMAC secret or a jwks_url, for machine-to-machine access.
ip_filter — allow/deny by client IP. When you run the agent behind your own reverse proxy, set its trust_proxies hop count so the client IP is taken from X-Forwarded-For instead of the proxy's address; leave it at 0 otherwise, or a direct client could spoof the header.
The one-off commands have shortcuts for the two most common cases: cruma proxy http 3000 --user alice s3cret adds form_auth, and --api-key X-API-Key <value> adds an API-key authentication middleware (the config add form takes --user alice:s3cret and --api-key X-API-Key:<value>).
Put an auth middleware at the top of a frontend's middleware list so it runs before anything reaches your service. Backend middlewares run before frontend middlewares, so a backend-level auth middleware protects every frontend that uses that backend.
Firewall and WAF
Independently of middlewares, a firewall runs on every connection before routing — for HTTP requests, TLS connections, and raw TCP alike. Rules are evaluated in order and match on source IP/CIDR, protocol, listener port, and hostname (SNI or Host); the first match decides, and default_action applies otherwise. A deny rule can either respond with an error or silently drop the connection, and drop rules are enforced as early as the TCP accept or the TLS ClientHello, before any handshake work is done. WAF rules can additionally match the request path, method, user agent, or query string and optionally auto-ban the offending client IP for a period.
Request hygiene
The proxy is designed to hold up against hostile clients, and these protections are always on:
Hop-by-hop headers are stripped in both directions. Requests with conflicting Content-Length values are rejected, and Transfer-Encoding/Content-Length combinations are neutralised by re-framing the request before it reaches your backend, so a hostile client cannot desynchronise it (request smuggling).
Routing is by the Host header (or :authority); the port, trailing dots, and letter case are normalised, and a client cannot steer a request to a different route through an absolute-form URL.
X-Forwarded-Proto and X-Forwarded-Host are always overwritten with the real values, so a backend's "require HTTPS" check cannot be forged. X-Forwarded-For handling is per frontend via forwarded_headers_mode: preserve (default) appends the real client, strip_incoming discards whatever the client sent so your backend only sees the real peer, and none forwards nothing.
Slow clients are bounded: request headers must arrive within 30 seconds by default, and an optional per-frontend body idle timeout aborts stalled uploads. Header count and body size limits are also configurable per frontend under request_limits.
Local data and the cache directory
The agent keeps its state in a per-user cache directory (cruma show-cache prints the path; profile scopes it per profile, temp: true uses a throwaway directory). It contains the agent's Ed25519 identity keypair for each tunnel ID (written with owner-only permissions), the ACME account key, issued ACME certificates and private keys, self-signed certificates, and the local development CA. Treat it like any other secret material — anyone who can read it can impersonate your agent's identity and serve your certificates.
cruma clear-cache deletes the whole directory. The agent will generate a fresh identity (and therefore a new anonymous FQDN) and re-issue certificates on the next run.
Install ID and telemetry
When the agent checks for updates (files.cruma.io) and in its HTTP/2 registration with the Cruma tunnel service, it identifies itself with:
User-Agent: cruma/<version> (<os>; <arch>; <channel>; <gui|cli>): version, operating system, CPU architecture, release channel (stable or preview), and whether this is the desktop (gui) or command-line (cli) build.
X-Cruma-Install: <install ID>: a random UUID created the first time the agent runs and saved as the file install-id in the cache directory (cruma show-cache prints the path). It is not derived from your hardware, your account, or your tunnel identity.
X-Cruma-First-Launch: 1, sent only on the run that created the install ID.
Deleting the cache directory (or cruma clear-cache) creates a new install ID, and that run counts as a first launch again. Each release channel has its own cache directory, so each has its own install ID.
Turning it off
Either of these makes the agent send only the User-Agent: no install ID, no first-launch flag, and no install-id file is created. Update checks keep working.
Set the environment variable CRUMA_NO_TELEMETRY=1 (any value except empty, 0 or false).
Set telemetry_enabled: false in the machine-local settings.yaml, which lives in the agent's config directory next to the default cruma.yaml:
telemetry_enabled: false
If settings.yaml exists but cannot be read or parsed, the agent treats telemetry as off. The setting is read at startup, so restart the agent after changing it. See the privacy policy for what we do with this data.
How this compares
Assigned hostnames: Cruma can fall back to provider-edge termination for assigned *.tun.cruma.io hostnames, similar to Cloudflare, ngrok, and similar services for their default domains. On eligible paid tunnels, the preferred path is agent-side termination once the assigned-hostname certificate is ready.
Custom hostnames: Terminating TLS on the agent via ACME TLS-ALPN-01 provides true end-to-end encryption by default — no manual certificate setup needed. This is stronger than providers that terminate custom-domain TLS at their edge. For additional hardening, layer on CAA and/or pinning.
Testing your routing
Once you have more than a couple of frontends, one question comes up again and again: if a request for this host and that path arrived right now, where would it actually go? Cruma gives you two ways to answer that without touching real traffic — one that predicts, and one that asks the live proxy directly.
Today both are reached through the MCP server (so any connected AI assistant can run them for you), and the live probe can also be driven by hand with curl. The desktop app carries a visual version of both tools on the Connections page, but only in developer (debug) builds — the release app you install does not show it yet.
The Route Simulator — a prediction
The Route Simulator answers "where would this go?" without sending anything anywhere. Give it an SNI (the TLS server name), a Host header, and a path, and Cruma walks the request through your routing rules — the same firewall, TLS, and route-matching logic the proxy uses — and reports, for every listener, which TLS route matches, which frontend rule wins, and which backend would serve it.
It's instant and safe because it never opens a connection. Set a source IP to see how source-based firewall rules would treat the request, or mark the request as HTTP/3 (UDP) so protocol-aware firewall rules are evaluated as they would be for QUIC.
💡 Ask your assistant
The simulator is the simulate_route MCP tool. If you've connected an AI assistant, you can ask "simulate a request for app.example.com/api" and it will run this for you, read back the outcome, and render the result as a flow diagram. (The assistant built into your proxied sites can run simulate_route too, for the site it is embedded in.)
Because the simulator re-derives the decision from your configuration, it's the right tool for "what if" questions. Where the answer depends on something only the running proxy knows — the current round-robin position, whether a rate limit is about to trip, whether a login would succeed — it says so rather than guessing.
The Live probe — the ground truth
Sometimes you don't want a prediction; you want to know what the running proxy would do right now. The Live probe does exactly that: it sends a real request to one of your listeners on this machine and reports the decision the live data plane actually made.
You tell it the port of the listener to test and whether that listener is TLS; the SNI, Host, and path are the same inputs as the simulator, and you can optionally force HTTP/2. The probe never contacts your backend and never disturbs your traffic counters, rate limits, or firewall state — it stops at the decision and hands it back.
What it tells you:
Plane — whether the request was handled by the hyper engine or the io_uring engine (see the performance section in Configuration; hyper is the default).
Fast path — on the io_uring engine, whether the matched route qualifies for the zero-copy fast path, and if not, which middleware disqualifies it. Not applicable on hyper.
Route — the frontend rule that matched, how it matched (host, path, or both), and what kind of target it points at.
Middleware — the request and response middleware that would run, in declared order, and where the request would stop. A rule that always ends the request (a redirect, for example) is marked as terminating; a rule that might end it depending on something at runtime — a login wall, an IP filter, a rate limit, a CORS preflight — is marked as may terminate. The probe deliberately never says whether a given credential would have passed.
Origin — the exact backend endpoint (address:port) that would be picked, the protocol it would be spoken to with, and why it was picked (single endpoint, round-robin, cookie affinity, client-IP hash, or an explicit override). The round-robin position is only previewed, never advanced.
Notes — anything the probe could not determine, in plain words.
The full raw decision as JSON, for copying into a bug report.
📝 When the two disagree, trust the probe
The simulator predicts; the live probe reports. If they ever differ, the live probe is the ground truth — it's the real engine answering. A mismatch is worth reporting.
For your assistant, this is the probe_route MCP tool — "probe port 443 for shop.example.com/checkout". It takes port, and optionally tls (inferred from your configuration if omitted), sni, host, path, and http2, and returns both a readable summary and the raw decision.
⚠️ What the live probe can reach
The probe only answers on this machine (loopback), and only on listeners that terminate HTTP or HTTPS. A TLS-passthrough or raw-TCP listener has no routing decision to report, so it will handle the request normally instead of answering the probe — the tool tells you when that happened.
Advanced: the probe header
Under the hood, the live probe is triggered by a single request header, x-cruma-probe, sent from a loopback client. Its value doesn't matter — its presence is the trigger. You can use it directly with curl for scripting or CI:
Instead of proxying the request, the proxy replies 200 with the decision as JSON and marks the reply with x-cruma-probe: echo, so you can tell a real probe answer from an ordinary response. The second form uses --resolve so the request presents app.example.com as its SNI and Host while still connecting to your local listener — the same trick the MCP tool uses.
fast_path is "Eligible", "NotApplicable", or { "Ineligible": { "reason": "..." } } naming the middleware that disqualifies the route.
route is null when nothing matched. target_kind is one of Backend, ServeDir, Respond, Redirect, DynamicBackend, or HyperService.
Each middleware outcome is "Ran", "Skipped" (an earlier step ended the request), { "TerminatedHere": { "detail": "..." } }, or { "MayTerminateHere": { "rule": "..." } }.
origin is null when no route matched, the target isn't a proxied backend, or the backend has no available endpoint (the reason then appears in notes). why is one of SingleEndpoint, Override, CookieAffinity, ClientIpHash, or RoundRobin; upstream_proto is h1.0, h1.1, h2, h2c, or h2c-pk.
A few fields are reserved and not filled in yet: tls_decision and outbound_framing are always null today, sni is only reported by the hyper engine, and alpn only by the io_uring engine.
⚠️ Don't send X-Forwarded-For
The probe is deliberately restricted to loopback callers. If you add your own X-Forwarded-For header, Cruma can no longer be sure the request is really local, so it fails safe and serves the request normally instead of answering the probe. Leave that header off.
What is Promenade?
Promenade is a drop-in widget that turns any web page into a small shared
place. Add one <script> tag to a site and the page itself becomes a playable
landscape: every letter of every paragraph is solid ground, so visitors control
a little stick figure that walks across headings, jumps between list items,
fires a jetpack to reach the skyline, and falls through the gaps between words.
Anyone else reading the same page appears as their own figure walking the same
text, in real time — and you can talk to them, by text chat or by voice and
video. It needs no cooperation from the host page's own code, and it renders
entirely inside a shadow root so it can't touch (or be touched by) the host
site's styles.
The fastest way to see it: There is a decicated site over at promenade.cruma.io which has the script running in server mode
What it's for
Presence on a quiet page. A blog or docs page stops being
read-once-and-forgotten — you can see who else is here right now and wander
over to them.
The page is the level. There's no authored level geometry. The article
is the terrain, so every page is a different place, for free. Change the page,
and you've changed the map.
Chat tied to a location. General chat, named channels, direct messages,
and a voice/video room — attached to a figure standing somewhere on the page,
not a faceless sidebar.
A serverless option. A single attribute (data-p2p) drops the server
entirely and runs the whole thing over a browser-to-browser mesh. Fewer
features, but no infrastructure at all.
Four ideas carry everything
The page is the level. Every non-whitespace glyph of every matched element
becomes its own small platform, measured from the page's real layout. Text-less
elements (images, inputs) become one block platform instead.
It is a guest on someone else's page. Everything renders inside a shadow
root, the scene is anchored to the document rather than pinned over your content,
and the host's own CSS is never touched. A widget that breaks its host has failed.
One origin, one world. Visitors are partitioned into universes keyed by the
website they're on. Each embedding site gets its own private area — people on
foo.com never see people on bar.com.
Two transports, one client.Server mode (a relay with persistence and
moderation) and P2P mode (a serverless browser mesh) run the same simulation
and the same UI. The only difference is where packets go and which features
exist.
Server mode vs P2P mode at a glance
Server mode
P2P mode (data-p2p)
Infrastructure
Talks to a Promenade server
None — browsers connect directly
Room identity
The site's origin → a universe
A room key you choose (default: the site origin)
Chat history
Persisted per site (owner-toggleable)
Ephemeral only
Moderation
Mute, ban, purge, reports, audit trail
None — local hide only
Voice / video
Yes, owner can gate it
Yes, open to everyone in the room
Identity
Stable per-browser id, hashed server-side
Random per page load (today)
Most sites use server mode by pointing the script at the managed server at
promenade.cruma.io — you get moderation, persisted chat, and the owner
dashboard with nothing to run yourself. Reach for P2P mode when you want
zero infrastructure and don't need moderation or history.
The next chapter shows how to add the widget to a page. If you just want to know
what the keys do, jump to Controls, chat & video. If
you're curious how the page-as-terrain trick actually works, see
How it works.
Embedding Promenade
The widget is a single script tag. It mounts all of its own DOM and styles
inside a shadow root, draws a non-interactive overlay pinned to your page, and
connects back to a Promenade server for presence and chat.
The one-line version
Point the script at the managed server and you're done:
That's the whole install. The async attribute keeps the widget from holding up
your page — it never blocks the parser and doesn't delay your DOMContentLoaded.
Promenade finds its own <script> tag to read the options below, so load order
never matters.
Because the script is loaded frompromenade.cruma.io, it also talks to that
server by default — everyone visiting your site lands in your site's own private
universe (keyed by your origin), and you never see visitors from other sites.
Hosting the script elsewhere
If you'd rather serve promenade.js from your own CDN but still use the managed
server, tell it where the server is with data-server:
See P2P mode for what changes, room keys, and the
trade-offs.
Where the widget appears
By default the widget fits itself into your page without growing it whenever
it can: it measures where your real content ends and, if the whole promenade band
fits in the empty space at the foot of the viewport, it tucks in there — no extra
scrollbar, the line stays visible above the fold. Only when your content is tall
enough that the band genuinely doesn't fit does it add a little padding at the
page foot and put the line below your content (scroll down to reach it).
You can override this with data-clearance (see the reference below).
Boxed embed
Instead of overlaying the whole page, you can mount the promenade inside a
specific element — a framed, clipped box the figure can't leave, perfect for a
"try it here" section:
Size the box with your own CSS on that element. A boxed embed is floor-only
(there's no host text inside it to stand on). The chat panel and the fullscreen
toggle still work — they float over the whole viewport rather than being trapped
in the box.
Caveat: a transform, filter, or contain on the mount element (or any
ancestor) makes it the containing block for otherwise viewport-fixed layers,
which would trap the chat panel and fullscreen stage inside the box. Keep those
off the container.
Attribute reference
All attributes go on the <script> tag.
Attribute
Effect
data-server
Which server to talk to. Defaults to the script's own origin.
Override the Nostr relays used for P2P discovery/signalling.
data-p2p-strict-pow
Hide P2P peers with missing/invalid proof-of-work instead of just flagging them. Off by default.
data-solids="h1,h2,img,…"
CSS selector for which elements become terrain. Defaults to headings, p, a, li, media, table cells, and form controls.
data-mount="#selector"
Bounded/"boxed" embed inside a container (implies floor-only).
data-max-width / data-max-height
Size caps (CSS px) for a boxed embed.
data-clearance="<px>"
Manual control of the headroom reserved above the promenade line. 0 keeps only the UI band; a negative value eats into the band so the page grows less (≈-64 zeroes the reserve). Leave it off to keep the automatic fit.
data-delay="<ms>"
Defer the first page measurement (and server connection) by N ms. Useful when your content slides/fades in with an entrance animation — measuring mid-animation bakes terrain a few pixels low. Set it to roughly the animation's duration.
data-chart-nodes="<selector>"
Make diagram nodes climbable platforms. Defaults to Mermaid flowchart nodes; point it at another library's node elements, or set empty to disable.
data-chart-edges="<selector>"
Make diagram edges walkable ramps (sampled into little staircases). Defaults to Mermaid edge paths; override or set empty to disable.
data-lamp-switch
Turn the lamppost into a light switch: walk up to it and press Enter (or click) to flip the page between light and dark. Writes data-theme on <html>; the choice is local to the browser and remembered across reloads.
data-debug
Outline every solid platform, for debugging your terrain.
Cooperating with your page's own theme toggle
If you use data-lamp-switchand your page has its own dark-mode control,
they should agree. Promenade drives the page the same way a normal theme button
would — by setting data-theme (and color-scheme) on <html>, and persisting
light/dark under the localStorage key pm-theme.
Use the same source of truth so you don't get two competing preferences. Two ways
to stay in sync — pick either:
Listen for the event. Each flip dispatches a promenade:theme event on
document:
document.addEventListener("promenade:theme", function (e) {
  myThemeSwitch.checked = e.detail.light;   // e.detail.theme is "light" | "dark"
});
Observe the attribute (catches any writer, not just the lamp):
new MutationObserver(function () {
  var light = document.documentElement.getAttribute("data-theme") === "light";
  myThemeSwitch.checked = light;
}).observe(document.documentElement, { attributes: true, attributeFilter: ["data-theme"] });
A note on performance
The widget is around 330 KB and loads lazily with async, so it never blocks
your page render. Terrain is measured once and only recomputed on resize or when
the DOM changes — scrolling costs nothing. The P2P transport lives in a separate
chunk that's only downloaded when you actually use data-p2p.
Controls, chat & video
This chapter is for visitors — the people walking around on a page that has
Promenade embedded. Nothing here needs setup; it's how you actually play and
talk.
Moving around
Key
Does
A / D
Walk left / right
W
Jump
J or Shift
Jetpack — hold to fly (burns limited fuel)
S
Climb down through a bordered edge of a div or pre
T
Open the Travel menu — jump to any heading on the page, or to another page. Start typing to filter; Enter jumps to the first match.
E
Open your camp / settings dialog (name + colour) from anywhere
. (dot)
Open a slim chat bar — Enter sends, Esc cancels
C
Toggle the chat history panel
;
Toggle the fullscreen stage
Some abilities depend on the mode the site runs — on a floor-only "promenade"
site there's no glyph terrain, jetpack, or climbing (see
Modes & universes).
Carrying your figure (desktop)
On desktop you can pick up and carry your own figure with the mouse: press
and drag it anywhere on the page, then release to drop it — it falls and lands on
whatever's beneath. Everyone else sees a little UFO swoop in, beam your figure up
and away, then set it down at its new spot. A quick click (no drag) just opens
your settings instead.
Pickups are limited to one every 5 seconds; while it's cooling down the figure
shows a red "blocked" cursor. (Dragging is mouse-only — on touch devices a
press-drag scrolls the page as usual.)
Idling
If you stop for a while, your figure shows Zz after 10 seconds and settles into
a bed after 30. Everyone sees the right pose — even people who just arrived.
Setting your name and colour
Press E anywhere, or walk up to the camp tent prop (beside the fire and
tree) and press Enter when it lights up. Set your name, a colour, and an
optional short description. Your choices are saved in your browser and shared with
everyone else in the universe in real time. (Esc closes the dialog.)
Chatting
Everyone on the same site shares a chat. Press . (dot) for a slim input bar
pinned low on the screen — Enter sends, Esc cancels. Each message pops a
speech bubble over your figure for a few seconds.
Press C to open the full history panel: a floating, draggable, resizable
window that does not block or blur the page — you can keep walking and reading
while it's open. Drag it by its header to move it, drag a corner to resize, and
use the header button to switch between a glass (translucent) and a solid
background. Its size, position, and look are remembered in your browser.
The panel lists every message with the sender's name, a timestamp, and the text,
and has a composer at the bottom so you can type and send right there. On a
server-mode site the server keeps a rolling history and replays whatever's still
in the window when you arrive, so you land mid-conversation. Chat is scoped to the
site's universe — foo.com and bar.com never see each other's messages.
Beyond the general chat there are also named channels and 1:1 direct
messages in the same panel. Direct messages between two people negotiate a
direct, encrypted browser-to-browser connection where possible — the panel
shows whether a conversation is direct or relayed via the server — and fall
back to the server relay if a direct link can't form.
Voice & video
When the site owner enables it, the chat panel gains a 🎥 Live room: a
WebRTC mesh where participants share audio and optional video.
It is strictly opt-in — nothing touches your mic or camera until you click
Join with mic or Join with camera, so you never unexpectedly broadcast.
Participants appear in a video grid (camera-off shows an avatar tile), and a 🔊
indicator lights over someone's head while they're talking. Media flows directly
between browsers; the server only relays who's in the room.
A few things worth knowing:
The video grid sits beside the chat and stacks on a narrow panel. You can hide
the chat column for a video-only view, and split the layout side-by-side or
stacked.
On a phone in landscape, opening chat during a call switches to a clean
theater (fullscreen) layout built for small screens.
You can opt into camera thumbnails over players' heads (Settings → Live
room) to see participants' video in the scene itself, not just in the grid.
If your mic or camera can't be opened, the room tells you why (for example it
needs a secure HTTPS or localhost page, or permission was blocked) instead of
silently doing nothing.
Connection trouble? Direct media needs the two browsers to reach each
other. On open or LAN networks this just works, but some restrictive networks
need a relay (TURN) that the site owner has to provide. Without one, a
connection that can't get through shows a clear "your networks may need a TURN
server" notice rather than stalling silently.
The props
Along the foot of the page runs the promenade line with a few interactive props,
placed at fractions of the page width:
A bus stop — the Travel menu.
A lamppost — optionally a light switch (if the site enabled
data-lamp-switch).
Benches you can sit on.
A telephone box — toggles the fullscreen stage.
A camp tent — your name/colour dialog.
A campfire that can set you alight — and, in floor mode, doubles as a
connection tell: it burns out when your connection drops and relights when
it comes back.
A tree.
Props scale and shift on narrow screens so they don't pile up. Which props appear
is configurable by the site owner.
Modes & universes
Promenade runs the same client everywhere, but a site can be configured to feel
quite different. This chapter explains the two concepts that shape that:
universes (who shares a world) and modes (what that world lets you do).
Universes: one world per site
Visitors are partitioned into universes, keyed by the browser's origin — the
site the widget is embedded on. Every site that embeds the widget gets its own
private street: visitors on https://foo.com never see visitors on
https://bar.com. A universe is created on demand when its first visitor arrives
and dropped when its last visitor leaves.
Everything is scoped to the universe the same way: movement, chat history,
channels, and the voice room. This is why a busy site and a quiet one embedded
from the same server never bleed into each other.
On the roadmap: "stargates" that let a figure hop from one site's universe into
another. Today, a universe is a firm boundary.
Modes
The mode decides which abilities exist in a universe. In server mode the owner
picks the mode (globally or per-site); the server advertises it to every visitor
so everyone in a universe agrees on the rules, and it enforces the mode — a
modified client can't, say, fly in a mode where flight is off.
Mode
Terrain
What it feels like
explore (default)
Full glyph terrain, jetpack, warp links, figure-dragging
The full experience: the page's text is terrain and figures climb, fly, and warp around it.
promenade (floor)
Floor only — walk and jump on one line
A calm "town square": visitors can only walk and jump along a single promenade line at the foot of the page, never interacting with the page content itself.
fullscreen stage
Floor only
Any visitor can toggle a fullscreen stage with ; (or the telephone box). Occupants share a world with each other and appear as "ghosts" to people still on the page.
boxed
Floor only
Set by the site's data-mount embed — the promenade lives inside a bordered box instead of overlaying the whole page.
explore mode
The default. The host page's text is the terrain: every glyph is a platform,
figures climb and jump between headings and list items, fire the jetpack to reach
the top, warp through links, and can be picked up and carried. The Travel menu
jumps to any heading. This is the mode most sites want.
promenade (floor) mode
A deliberately minimal, TownSquare-style
mode. Visitors can only walk and jump on the promenade line, which sits at the
foot of the page — you scroll down to reach it. The view never camera-follows as
you walk; your figure slides across a fixed-width stage instead of dragging the
page around.
The widget never scans the host page in this mode — no glyph terrain, no
link-walking, no watching the DOM — because there's nothing to collide with. Glyph
terrain, climb-down, the jetpack, link-warp signs, and figure-dragging are all
off. The Travel menu remains but only lists "leave this site" links. Jumps are a
purely cosmetic hop that never affects a figure's networked position, so they can
never jitter on other people's screens. The result is smooth, even motion that
suits a busy or a very simple page.
Ghosts: when layouts don't match
A figure's position is expressed as which glyph it's standing on, not as pixels
(see How it works). That only lines up perfectly when
two visitors' pages wrap text the same way. When they don't — a different window
size or zoom, a fullscreen stage, a boxed embed, or genuinely different content —
the other person is shown as a faded ghost: an approximate figure placed onto
your terrain rather than positioned precisely-but-wrongly. Ghosts are how the
widget stays sensible across a phone and a widescreen monitor looking at the same
page at the same time.
Serverless (P2P) mode
Add one attribute and Promenade runs with no server at all:
In P2P mode, visitors' browsers connect directly to each other over a WebRTC
mesh. Public relays are used only for discovery and signalling — the handshake
that lets two browsers find each other — never for your movement or your messages.
Once connected, everything flows browser-to-browser.
This is the zero-infrastructure option: you don't run anything, you don't need an
account, and there's nothing to administer. The trade-off is that features which
fundamentally require a trusted server aren't available.
What you get, and what you give up
P2P mode
Server mode
Infrastructure
None
A Promenade server
Chat history
Ephemeral (in-session only)
Persisted per site
Moderation
Local hide only
Mute, ban, purge, reports
Identity
Random per page load (today)
Stable, hashed per browser
Voice / video
Yes — open to everyone in the room
Yes — owner can gate it
Anti-abuse
Receiver-side guard + proof-of-work
Server-enforced
The single biggest difference is moderation. With no server there's no
authority to ban anyone, persist history, or resolve identity disputes — each
browser can only locally hide peers it doesn't want to see. Sites that need real
moderation should use server mode.
Rooms
In server mode, the "room" you land in is fixed by the site's origin. In P2P mode
you choose it with a room key — a rendezvous string that decides which
browsers try to find each other:
The default room key is location.origin, so by default P2P behaves like server
mode's per-site partitioning. Note a key difference, though: a room key is a
rendezvous point, not a boundary. Anyone who knows the key can join. It
decides who finds each other, not who's allowed in.
Relays
Discovery uses public Nostr relays by default. You can point
at your own with data-p2p-relays if you'd rather not depend on the public ones:
There's no server to enforce rules, so P2P does its policing on the receiving
side: each browser vets what it receives and quarantines misbehaviour locally.
That needs no cooperation from the sender, which is why it works at all.
Per-peer movement and flood limits catch an individual bad actor.
Aggregate budgets catch a swarm — twenty peers each individually compliant
are still a swarm — and shed the least-trusted first, where "trust" is simply
time-in-room (unforgeable, and paid in wall-clock).
New peers solve a small proof-of-work before they're shown, so a flood of
fresh identities costs real effort.
By default, peers with missing or invalid proof-of-work are flagged but still
shown. Add data-p2p-strict-pow to hide them entirely:
You want presence and chat with zero infrastructure.
You don't need persisted history or the ability to ban people.
Your audience is small-to-medium and mostly on open networks (very restrictive
NATs may struggle to form direct connections without a relay).
Choose server mode when you need moderation, persisted chat, a stable
identity per visitor, or a gated voice room. See
Owner & admin controls for what that gives you.
Owner & admin controls
When you embed Promenade in server mode (pointing at promenade.cruma.io),
you can claim your site and take control of how the widget behaves there — the
mode, whether the voice room is on, whether chat history is kept, and who gets
moderated. This chapter covers that owner experience.
This applies to server mode only. P2P mode has no
server and therefore no owner controls, no persisted history, and no
moderation beyond a local per-viewer hide.
Claiming your site
Everything an owner can do is scoped to origins you've proven you control.
Promenade deliberately never trusts the widget's own Origin header for this —
a browser sets it honestly, but a non-browser client can forge it — so ownership
is verified out-of-band, the same way other services verify a domain.
From your Cruma dashboard, add your site's origin and pick one of two proofs:
DNS — add a TXT record at _promenade-challenge.<your-host> containing
the challenge token you're shown.
File — serve the token at
https://<your-host>/.well-known/promenade-verify.txt (the file's contents
should be exactly the token).
Then click Verify. Each origin has exactly one verified owner — first to
verify wins. Once verified, you get a copy-paste embed snippet and access to the
per-site settings below.
Per-site settings
These are all scoped to your verified origin (your universe). Each one is an
override of the server's global default — where you don't set anything, the
site inherits the default.
Setting
What it controls
Mode
Floor-only promenade mode vs full explore mode for your site (see Modes & universes).
Voice / video room
Turn the live 🎥 room on or off for your site.
Registered-only voice
Require visitors to be signed in (to a linked account) before they can join voice or place 1:1 calls. When off, guests can join.
Chat history
Whether chat is persisted and replayed to new arrivals, or live-only.
Federation
Opt in to listing your site's open, password-free channels in other sites' channel trees so people can discover them. Off by default.
Multiple channels
Allow named channels beyond the general chat.
Fullscreen stage
Allow the ; fullscreen stage.
Chat widget
Whether the draggable chat panel is available.
Travel menu
Whether the T travel menu is available.
Chat theme
The chat panel's colour theme.
You manage these from the site's page in your dashboard, which also shows a live
list of who's currently on your site and lets you drop into it yourself.
Moderation
Moderation exists only in server mode. There are two levels: what a site owner can
do inside the running widget, and the platform-level controls the server operator
holds.
As a site owner (in the widget)
Once you're recognised as the owner of your origin, you get a small set of
moderation actions right inside the running widget — from a player's info panel or
the in-call UI. Every action is re-checked server-side against your ownership of
that origin, so it only ever affects your site:
Mute — silence a visitor's chat (general and channels). They're told
they've been muted; you can unmute them again.
Voice-block — revoke a visitor's access to the voice room. If they're in a
call, they're removed from it.
Kick / ban — remove a visitor and block their network address from your
site. Their recent messages are purged and their connection is dropped.
Reports
Any visitor can report another (for spam or abuse, with an optional note),
rate-limited so it can't itself be spammed. Reports are retained even after the
offender disconnects, and are backed by a message audit trail, so a late report is
still actionable — a moderator can trace the reported visitor's network addresses
and recent messages and act on them after the fact.
Automatic anti-abuse
On top of manual moderation, the server runs the layered anti-abuse defences
described in How it works — connection-rate limits,
chat-flood gates, identity-churn detection, movement-plausibility scoring, and an
optional proof-of-work at connect. These run automatically; you don't have to
configure anything to benefit from them.
Platform-level controls
The server operator (the Cruma team, for the managed service) additionally has a
super-admin dashboard covering every universe on the server: global defaults
that all sites inherit, server-wide bans, the report queue and audit trail across
all sites, an embed/connect allowlist, and the sign-in providers offered to
visitors. As a site owner you don't need this — your per-site settings and
in-widget moderation cover your own universe — but it's what backstops the whole
service.
Running your own server
The managed server at promenade.cruma.io is not currently open source, so
self-hosting isn't covered here. If you want moderation and persisted chat, the
managed server is the path; if you want zero infrastructure and don't need those,
P2P mode needs no server at all.
How it works
You don't need any of this to use Promenade — but if you're curious how a web
page becomes walkable ground and how everyone stays in sync, here's the mental
model, top down.
The page is the level
When the widget loads, it measures the host page's real, laid-out text. It walks
every matched element (headings, paragraphs, links, list items, table cells, and
so on) and, for each non-whitespace character, measures the glyph's actual
on-screen rectangle. Each glyph becomes its own tiny platform, sized to the
visible ink of the letter — so a figure stands right on the letters, walks across
them, slips off their edges, and falls through the gaps between words and lines.
Text-less elements like images and inputs become a single block platform.
Because playability comes straight from typography, the whitespace is the
gameplay: the gaps between words and lines are deliberately holes to fall
through. Change the page's text and you've changed the map, for free — there's no
authored level anywhere.
Terrain is stored in document coordinates (scroll-independent), so scrolling
costs nothing; it's only recomputed on a resize or when the page's DOM changes.
Positions are glyphs, not pixels
Here's the idea the whole project rests on. A position cannot be sent as
pixels, because your window is a different width than mine — my pixel 400 is the
middle of a different word than yours. So a figure's position is expressed as
which glyph it's standing on:
el — the element's index in the match list,
seg — the character's offset within that element's text,
plus a fraction across that glyph.
Both el and seg are derived from the shared DOM that every visitor
received identically. So the same glyph is identifiable on every visitor's
screen, no matter how differently their browser lays the page out. When your
figure walks across a heading, the message that goes out says "I'm on the W of
element 3" — and the receiving browser resolves that against its own layout
and draws the figure there. Which is why it looks right on a phone and a
widescreen monitor at the same time.
When two visitors' pages don't lay out the same way — different window size,
zoom, a fullscreen stage, or genuinely different content — the glyph anchor would
resolve to a weird spot, so that peer is drawn as a faded ghost placed
approximately onto your terrain instead (see
Modes & universes).
What runs where
There are two pieces: one JavaScript bundle in every visitor's page, and —
in server mode — one server.
The client bundle contains the whole simulation, the UI, and both
transports. Local physics actually runs in a small Rust core compiled to
WebAssembly, with a pure-JavaScript fallback so the widget always works even
if the WASM can't load.
The server (server mode only) is a relay and a referee, not a
simulator. It never runs physics. It sanitizes and forwards each visitor's
state, enforces the mode (clearing flags for abilities a mode disables, so a
modified client can't express them), scores movement for plausibility, and
relays chat. Physics runs only in browsers.
In server mode the server forwards each visitor's state the moment it arrives
(rate-capped per player, and always flushing a player the instant it comes to
rest so its settled position is exact). A figure standing still generates no
traffic at all. In P2P mode there's no referee, so each browser instead vets what
it receives and quarantines misbehaviour locally.
Identity
In server mode, each browser mints a random secret on its first visit and keeps
it locally. It presents that secret to the server on connect, and the server
hashes it into the public id other people see. The secret itself never
leaves the browser, so a public id can't be reverse-engineered into someone's
secret or used to impersonate them — and because the hash is deterministic, a
returning visitor keeps the same identity. Multiple tabs from the same browser
share one player.
In P2P mode, identity is random per page load today (a stable-identity scheme is
in progress).
Anti-abuse, briefly
The widget is embeddable by anyone, so the abuse surface is "a bot connects to
every site using the script." The defences are layered, and mostly about
anchoring limits to something that costs real money:
Limits key on IP, not identity, because a browser identity is free to mint
— per-identity penalties would reset for nothing.
Identity churn is the signal that separates a real office behind one
address (24 identities that persist) from a spammer (a fresh identity every few
messages). Message rate alone can't tell them apart; churn can.
Proof-of-work at connect is a speed bump that makes swarms cost effort,
solved off the main thread so the host page never janks.
In P2P, the same ideas are judged locally by each receiver, plus aggregate
budgets that catch a swarm of individually-compliant peers.
If you self-host and every visitor appears to arrive from one IP (a common
misconfiguration behind naive Docker port-forwarding), the per-IP defences detect
the collapse and fail open with a loud warning, rather than throttling your
whole audience into one shared bucket.
Want the deep version?
This is the tour. The widget also has an interactive, six-altitude architecture
walkthrough (arch-and-mental-model.html in the source tree) and a set of design
docs covering anti-abuse, anti-cheat, deterministic replay, the simulation-core
interface, and the in-progress P2P identity spec. Those are the source of truth
for anyone working on Promenade itself.
What is Cruma DNS?
Cruma DNS hosts the DNS for your domains. You point a domain (or a subdomain)
at Cruma's nameservers, manage its records in the Cruma dashboard, and Cruma
answers every DNS query for it on the public Internet.
Two things set it apart from a plain DNS host:
Geo-aware answers. Any record can have a different value per country.
Visitors in Finland can get one address and visitors in the US another, with a
default for everyone else. See Geo routing.
Domain registration in the same place. You can search for a domain, buy
it, and have it renew automatically, without a separate registrar account. A
domain bought through Cruma is set up on Cruma DNS from the start.
Where to find it
In the dashboard at dash.cruma.io, open Geo-DNS in
the sidebar:
Domains: the domains hosted on Cruma DNS and their records.
History: a log of changes made to your domains and records.
Search domains and My domains: buying and managing registered domains.
Key concepts
Domain. A zone Cruma DNS answers for, such as example.com or
tun.example.com. You add a domain once you've proven you control it.
Record set. All the values of one type for one name, for example the A
records of www.example.com. A record set has one TTL and one or more values.
Geo zone. Which visitors a record set is for: a country code such as FI,
or Any (*) for everyone else.
Nameservers. Cruma DNS answers from dns.cruma.io and ns1.cruma.io.
A domain resolves through Cruma once it is delegated to these two.
Personal and organization domains
A domain belongs to the scope you add it in: your personal account, or an
organization you're a member of. In an organization, each member's DNS access
is set on the organization's Roles page:
Access
Can
Read
See domains, records and history.
Write
Also add, edit and delete records.
Admin
Also add and delete domains, import zone files, and buy and manage registered domains.
In your personal account you have full access to your own domains.
Prove you control it with a TXT record at your current DNS provider.
Delegate it to Cruma's nameservers so the records you manage in Cruma are
the ones the Internet sees.
💡 Buying a domain instead?
A domain you buy through Cruma skips both steps:
it's added to Cruma DNS and delegated automatically.
You can add an apex domain (example.com) or any subdomain you control
(tun.example.com). Adding a subdomain leaves the rest of the parent domain
with your current provider.
1. Publish the verification record
At your current DNS provider, create a TXT record on the exact name you're
adding. Its value is cruma:, the name, and your Cruma account ID:
example.com. 300 IN TXT "cruma:example.com:YOUR-ACCOUNT-ID"
In the dashboard, Geo-DNS → Domains → How domain verification works shows
this line with your account ID already filled in.
The name in the value must match the name you add exactly: no trailing dot,
and the subdomain included if you're adding one.
Publish only one TXT record starting with cruma: on that name.
The account ID is your own, even when you add the domain to an organization.
Wait for the record to be visible, then check it:
dig +short TXT example.com
2. Add the domain
Enter the name under Add a domain and select Add domain. Cruma looks up
the TXT record right away. If it's missing, doesn't match, or there's more than
one, the domain isn't added and the error says which. Fix the record, wait a
moment, and try again.
The record is only checked when you add the domain. Cruma creates the domain
with its SOA record and an NS record set listing both Cruma nameservers.
If the domain was already added by another account in the same scope, adding it
with your own verification record moves it, with its records, to you.
3. Delegate to Cruma
Point the domain at both Cruma nameservers:
dns.cruma.io
ns1.cruma.io
An apex domain (example.com): set these as the nameservers at your
registrar, replacing the existing ones.
A subdomain (tun.example.com): at the DNS provider of the parent domain,
add NS records for the subdomain:
tun.example.com. 3600 IN NS dns.cruma.io.
tun.example.com. 3600 IN NS ns1.cruma.io.
Until the delegation takes effect, the records you create in Cruma exist but
aren't what the Internet sees. You can add records before delegating, so the
switch-over doesn't leave a gap.
Check the delegation:
dig +short NS example.com
dig @dns.cruma.io www.example.com A
The first should list both Cruma nameservers. The second asks Cruma directly and
works even before delegation.
Deleting a domain
Open the domain and select Delete. This permanently removes the domain and
all of its records from Cruma DNS. Delegate the domain elsewhere first, or it
stops resolving.
A domain registered through Cruma can't be deleted while its registration is
active.
Managing records
Open Geo-DNS → Domains and select Manage records on a domain. The table
lists every record set with its type, name, values, TTL and geo zone. Use the
search box and the type and zone filters to narrow it down.
Add a record
Select Add record and fill in:
Owner (name).@ for the domain itself, a name relative to the domain
(www, api.eu), or a wildcard (*, *.dev, **). You can also type the
full name, such as www.example.com.
Type.A, AAAA, CNAME, TXT, NS or PTR.
TTL. How long resolvers may cache the answer, from 1 to 86400 seconds.
Geo zone.Any (*) for everyone, or a country. See
Geo routing.
Records. One value per line. All lines become one record set.
Owner:     www
Type:      A
TTL:       3600
Geo zone:  Any (*)
Records:   203.0.113.10
           203.0.113.11
Saving a record set with the same name, type and geo zone as an existing one
replaces it.
MX, SRV and CAA records are added by importing a zone file, described
below.
Rules per type
CNAME has exactly one target, and a name with a CNAME can't have
records of any other type.
TXT values are at most 255 characters each. Enter the text without
surrounding quotes.
NS, CNAME and PTR values are host names.
SOA and the NS records at the domain itself are created for you when
the domain is added. The SOA serial increases automatically whenever records
change.
Wildcards
When a name has no records of its own, Cruma DNS looks for a wildcard:
* one level up: a query for a.dev.example.com uses *.dev.example.com.
**, a wildcard at any depth: a record set named ** covers
a.example.com, a.b.example.com and so on. It never applies to the domain
itself.
Edit, clone and delete
Edit changes a record set's values, TTL, name, type or geo zone.
Clone opens Add record pre-filled with a copy, which is the quickest
way to add a variant for another country.
To delete, tick record sets in the table and select Delete selected.
Export
Export CSV downloads the domain's records as a spreadsheet with the
columns Type, Name, Content, TTL, Geo Zone and Priority.
Import a zone file
Import CSV opens Import zone file, which takes a zone file in the
standard text format. Upload a .zone or .txt file or paste its content.
Each line is one record:
@       3600  IN  A      203.0.113.10
www     3600  IN  CNAME  example.com.
@       3600  IN  MX     10 mail.example.com.
@       3600  IN  TXT    "v=spf1 mx -all"
_sip._tcp 3600 IN SRV    10 5 5060 sip.example.com.
@       3600  IN  CAA    0 issue "letsencrypt.org"
www     300   IN  A      198.51.100.20   ; zone=FI
Every line needs a name, a TTL, the class IN, a type and the data.
Names are relative to the domain unless they end in a dot. @ is the domain
itself.
Lines starting with ; are comments. A comment of the form ; zone=FI at the
end of a line puts that record in a geo zone. Lines without one go to
Any (*).
Directives such as $ORIGIN and $TTL aren't supported. Remove them before
importing.
Lines with the same name, type and zone form one record set and must share a
TTL.
Importing adds and replaces record sets. It doesn't delete records that aren't
in the file. Importing requires DNS admin access.
History
Geo-DNS → History lists changes to your domains, newest first: records
created, changed and deleted, zone file imports, and domains added, moved or
deleted. In
an organization it shows changes to the organization's domains by every member.
Geo routing
Every record set has a geo zone. Records for the same name and type can
exist in several geo zones at once, and Cruma DNS answers each query from the
one that best matches where the query comes from.
A typical setup sends European visitors to a server in Finland, North American
visitors to one in the US, and everyone else to a default:
Name
Type
Geo zone
Value
www
A
FI
198.51.100.20
www
A
US
203.0.113.10
www
A
Any (*)
203.0.113.10
To build this, add the Any (*) record set first, then use Clone on it
and change the geo zone and value for each country.
Geo zones
A country, by its two-letter ISO code (FI, US, JP …).
Any (*): the default for queries no country variant matches. Every
name that uses geo zones should have one.
All: a second default, used only when a name has neither a matching
country nor an Any (*) variant. Most setups don't need it.
How a query is matched
For each query, Cruma DNS works out the country it comes from and picks:
The variant for that exact country.
Otherwise, a variant for another country on the same continent. With
only the table above, a visitor in Sweden gets the FI answer and a visitor
in Canada gets the US answer.
Otherwise, Any (*), then All.
If the name has neither, one of its country variants. Which one isn't
defined, so always add an Any (*) variant.
The country comes from the client subnet that many public resolvers forward
with the query (EDNS Client Subnet). When the resolver doesn't send one, the
resolver's own address is used, which places visitors where their resolver is
rather than where they are.
TTLs are per variant, so a short TTL on one country doesn't affect the others.
Testing
Ask Cruma DNS directly and pretend to be in a given network with dig's
+subnet option:
dig @dns.cruma.io www.example.com A +subnet=198.51.100.0/24
Replace the subnet with an address range in the country you want to test.
Without +subnet, the answer is for the country of the address you query from.
Buying a domain
You can register a new domain directly from the dashboard. A domain bought
through Cruma is added to Cruma DNS and delegated to
Cruma's nameservers automatically, so you can start adding records as soon as
the registration completes.
Search
Open Geo-DNS → Search domains and enter a name, such as example. The
results list matching domains across several endings, each with its
registration price and its yearly renewal price, or the reason it can't be
bought. Select Buy on the one you want.
Premium domains, which registries price individually, can't be bought through
Cruma.
Enter the registrant contact
The registrant is the legal owner of the domain. Fill in name, email, phone,
address and country. Enter the phone number in international format, starting
with + and the country code (+46701234567).
Some domain endings ask for more, such as a national identity number, a nexus
category or an acknowledgement of the registry's terms. Those fields appear
below the contact form for the ending you chose, and Buy stays disabled
until they've loaded. Cruma passes these answers to the registry and doesn't
keep them once the domain is registered.
Pay and register
After Buy, enter your card details in the secure card form and select
Authorize card and register.
Your card is authorized for the price, not charged.
Cruma registers the domain and sets up its DNS.
Only when the registration succeeds is the payment captured.
If the registry refuses the domain, the authorization is released and you
aren't charged. If something needs correcting, such as a registry-specific
field, the form opens again with the error next to the field.
Registration usually takes a few seconds. If it takes longer, the page says so,
and Cruma finishes the registration and emails you. Retrying never charges you
twice. If a message shows a reference, quote it when you contact support.
While the card form is open, Cancel purchase abandons the purchase without
charging you.
WHOIS privacy turned on, so your contact details aren't published.
The domain added to Geo-DNS → Domains, with Cruma's nameservers set at the
registry.
Registrars require the registrant to confirm their email address. Watch for a
verification email after buying: an unverified domain may be suspended.
Buying for an organization
With an organization selected, the domain belongs to the organization and is
shared with its members. Buying, renewing and managing registered domains in an
organization requires DNS admin access.
Managing registered domains
Domains you bought through Cruma are listed under Geo-DNS → My domains,
with their status and expiry date. Select one to see its details, renewal and
registrar settings.
A registration is in one of these states:
Status
Meaning
Pending payment
The purchase was started but the card hasn't been authorized.
Registering
Payment is authorized and the registration is being completed.
Active
The domain is registered to you.
Transferring out
The domain is being moved to another registrar.
Expired
The registration ran out without being renewed.
Cancelled
The purchase was cancelled, or the domain has left Cruma.
Failed
The registration couldn't be completed. You weren't charged.
Renewals
Domains renew one year at a time. Renew automatically is on for every new
registration.
With automatic renewal on:
You're notified about 45 days before the domain expires.
30 days before expiry, Cruma raises a renewal invoice and charges the payment
method saved on your account.
If the payment fails, it's retried 14, 7, 3 and 1 days before expiry. After the
last attempt, the invoice is voided and the domain lapses at expiry.
The Renewal section shows the next charge date, the amount, and links to the
invoice and receipt when they exist. If a payment fails or needs your action,
update your card, then select Renew now.
Turning Renew automatically off means the domain lapses at expiry unless you
renew it yourself, and voids any open, unpaid renewal invoice. Renew now is
offered whenever automatic renewal is off, a payment failed or needs action, or
the domain has lapsed but can still be renewed. A lapsed domain can be renewed
only within the registry's grace period after expiry.
Selecting Renew now again never creates a second invoice for the same term.
If the page says a renewal is being recovered or its outcome is unknown, don't
renew again: Cruma is already resolving it.
Registrar settings
Transfer lock. While enabled, the domain can't be transferred to another
registrar. Keep it on unless you're moving the domain.
WHOIS privacy. While enabled, your contact details are hidden from public
WHOIS lookups. It's on for every new registration.
Registrar nameservers. The nameservers the registry has for the domain. If
they've been changed, Reset nameservers to Cruma points the domain back at
dns.cruma.io and ns1.cruma.io.
Registrar contacts
The Registrar contacts section shows the domain's contacts and whether the
registrant's email address has been verified. If it hasn't, a notice shows the
deadline. An unverified domain may be suspended by the registrar after it.
Resend verification email sends the email again.
DNS for a registered domain
A registered domain's records are managed like any other under
Geo-DNS → Domains. The domain can't be deleted from Cruma DNS while its
registration is active.
Private preview
What is Catacombs?
🧪 Private preview, in heavy development
Catacombs is not generally available yet and is under heavy development. Access is by invitation. This book describes Catacombs as it is planned for general availability: features, limits and pricing are subject to change, and parts marked 🚧 In development are not available in the preview yet.
Catacombs runs your container images and virtual machines for you. Give it an
image reference, say how many copies you want and how much CPU and memory each
one gets, and Catacombs starts them, keeps them running, restarts them when
they crash and gives them a public hostname. When you need a long-lived
server instead, create a machine: a Linux virtual machine with its own disk
that you manage over SSH.
Every running container is its own isolated micro virtual machine, not a
container sharing a kernel with other customers. Your workloads are separated
from everyone else's at the hardware-virtualisation level, and every limit
(CPU, memory, disk, network) is enforced from outside the workload.
The things you work with
Zone. A private network for a group of deployments that belong
together, such as an app and the API it talks to. Deployments in the same
zone can reach each other by name. Zones are isolated from each other and
from other organizations.
Deployment. One container image, the resources each copy gets, and how
many copies (replicas) you want. Catacombs keeps the actual number of
copies equal to the number you asked for.
Instance. One running copy of a deployment. You don't create instances
yourself: Catacombs creates and replaces them to match the deployment.
Machine. A durable Linux virtual machine in a zone, with its own root
disk and private address that survive restarts. See
Machines.
Catacombs lives in the Cruma dashboard. Once it is
enabled for your account, a Catacombs section appears in the dashboard
sidebar with Zones, Usage and Network pages. Everything in it
belongs to the organization you have selected in the dashboard.
This walks you from an empty organization to a container image answering on
a public hostname. You need Catacombs enabled for your account (see
Introduction) and a container image that serves
HTTP. A public image such as nginx:latest works for a first try.
1. Create a zone
In the dashboard, open Catacombs → Zones.
Click Create zone, give it a name (for example dev) and, optionally,
a description.
Click Create zone.
The zone appears in the list. Its name becomes part of the hostnames of the
deployments you put in it.
2. Create a deployment
Click Open on the zone.
Click Create deployment and fill in:
Name: for example web. This name is how other deployments in the
zone reach this one, and it can't be changed later.
Image: the image reference, for example nginx:latest.
HTTP port: the port your container listens on. For nginx:latest
that's 80.
Location: make sure it is empty, to run in any available location.
Leave the other fields at their defaults and save.
3. Watch it start
The deployment shows up in the zone with its Hostname, Replicas,
Ready count and Phase. It moves from Pending to Running once
its instance is up. Open the deployment to see its instances, their status
and their logs.
4. Open it
The deployment's public hostname is shown in the deployment list and at the
top of the deployment's page. Open it in a browser and you reach your
container on the HTTP port you set.
Next steps
Deployments: resources, replicas, updates,
rollback and logs.
Networking: how deployments reach each other,
outbound internet access and traffic policies.
Machines: durable Linux virtual machines you manage
over SSH.
Private preview
Deployments
A deployment describes what to run. Catacombs continuously works to make what
is running match it: it starts missing instances, replaces crashed ones and
removes extra ones.
Settings
Setting
What it does
Name
Identifies the deployment and is its name on the zone's private network. Fixed once created.
Image
The container image to run, for example ghcr.io/you/app:1.4.
Replicas
How many instances to keep running.
Location
Where to run. Empty means any available location.
HTTP port
The port your container serves HTTP on. Traffic to the deployment's public hostname goes here.
Outbound
Deny (default) blocks connections to the internet. Allow internet permits them. See Networking.
CPU millis
CPU per instance, in thousandths of a core: 1000 is one full core.
Memory MiB
Memory per instance.
Disk MiB
Scratch disk per instance. It is not kept when an instance is replaced.
Each instance gets the CPU, memory and disk you set, and those limits are
enforced from outside the workload.
Phases
Phase
Meaning
Pending
Instances are being scheduled and started.
Running
The requested number of instances are running.
Rolling out
A change is being rolled out to the instances.
Degraded
Fewer instances are running than requested. The Reason column says why, for example an image that can't be pulled or a container that keeps crashing.
Stopped
No instances are running.
A container that keeps exiting is restarted with an increasing delay between
attempts, so a broken image doesn't restart in a tight loop. Fix the image or
settings and update the deployment.
Updating a deployment
Click Edit on a deployment to change any setting except its name.
Every saved change becomes a new revision and rolls out one instance at
a time: a new instance starts before an old one is removed, so the
deployment keeps serving while it updates.
Rolling back
Roll back returns a deployment to its previous revision. The confirmation
shows which revision and image it returns to. The rollback is itself a new
revision copied from the earlier one, so the history only ever grows and you
can roll forward again the same way.
Definition
Definition shows the deployment's full specification as YAML, including
the settings the dashboard doesn't edit directly.
Instances and logs
Open a deployment to list its instances with their status, private address
and DNS name. Click Logs on an instance to see its output,
including new lines as they arrive.
Logs are kept for 7 days, up to 100 MiB per organization. Logs of instances
that have been replaced or removed stay available under Terminated instance
log archives.
Jobs
🚧 In development
Jobs are not available in the preview yet.
A job runs a container image once instead of keeping it running. It gets
its own isolated micro virtual machine with the image, command, environment and
resources you give it, runs until the container exits, and is never restarted.
The job ends as Succeeded or Failed with the container's exit code, or
as Timed out or Cancelled, and its logs stay available like any
instance's. The micro-VM and its disk are discarded when the job ends.
Use jobs for one-off and batch work such as migrations or reports. Cruma Flow's
hosted runners run every CI job this way.
Deleting
Delete removes a deployment and all its instances. A zone can only be
deleted once it has no deployments or traffic policies left.
Private preview
Networking
Public hostname
Every deployment gets a public hostname, built from the deployment's name,
its zone and your organization. You'll find it in the zone's deployment list
and at the top of the deployment's page. Requests to it are spread across
the deployment's running instances on the deployment's HTTP port.
Leave HTTP port empty and the deployment gets no public traffic. It is
still reachable from inside its zone.
TLS pass-through and UDP
🚧 In development
Publishing TLS pass-through and UDP services is not available in the preview yet.
A deployment that terminates TLS itself receives encrypted connections
untouched, routed to it by the hostname the client asks for. Services that
speak UDP, including QUIC-based protocols, can be published as well.
Inside a zone
Each zone is a private network. Deployments and running machines in the same
zone reach each other by name:
curl http://api:8080/health
Here api is the name of another deployment in the same zone and 8080 is
the port it listens on. Traffic inside a zone is allowed unless a traffic
policy blocks it (see below).
Zones are isolated from each other and from other organizations' workloads,
and no policy opens one zone to another. Put workloads that need to talk to
each other in the same zone.
Outbound internet access
Each deployment's Outbound setting decides whether its instances can
open connections to the internet:
Deny (default): no outbound internet access. Use this for anything
that only serves requests.
Allow internet: outbound connections are allowed, for example to call
third-party APIs or pull data.
Traffic policies
A traffic policy is a finer-grained rule set for a whole zone. Open it from
Traffic policy on the zone. A policy has a default action and a list
of rules. Each rule allows or denies a destination, for a protocol (TCP or
UDP) and a list of ports:
Destination
Meaning
cidr
An IP address range, for example 203.0.113.0/24.
dns
A host name, for example api.example.com. The rule follows the name when its addresses change.
same zone / deployment
Workloads in this zone.
How a policy applies:
Default action deny: the zone's workloads reach only the destinations
you allow.
Default action allow: the zone's workloads reach the internet, except
the destinations you deny.
A deny rule for same zone cuts traffic between the workloads in the
zone. A deny rule for one deployment cuts traffic to that deployment only.
🚧 In development
Matching rules on protocol and ports, deny rules for host names and single deployments, and host-name rules that follow address changes are not available in the preview yet.
A policy only ever narrows access. When a deployment's own Outbound
setting and its zone's policies disagree, the stricter one wins, so a
deployment whose Outbound is Deny reaches no internet destination
even if a policy allows it. Set Outbound to Allow internet and use
the policy to narrow it.
Watching traffic
Catacombs → Network shows traffic for the selected time window: bytes
sent and received, broken down by source and destination, as a graph or a
table. Traffic to and from the internet is shown as External.
🚧 In development
Reporting of blocked connection attempts is not available in the preview yet.
Connection attempts that a policy blocks are reported to your organization:
which workload tried, the destination and port, and the rule that blocked it.
Private preview
Machines
🚧 In development
Machines are still being rolled out to preview hosts, so they may not be
available to your organization yet.
A machine is a durable Linux virtual machine that you manage yourself, over
SSH, like a server. Use a machine when you need a long-lived server with its
own disk. Use a deployment when you want copies of
a container image that Catacombs replaces freely.
Deployment
Machine
Copies
Any number of interchangeable instances
Exactly one
Disk
Scratch disk, lost when an instance is replaced
Root disk that persists until you delete the machine
Address
Changes when instances are replaced
One private address, kept for the machine's lifetime
Updates
Change the deployment and Catacombs rolls it out
You manage the operating system yourself
Creating a machine
Open a zone and click Create machine:
Name: also the machine's name on the zone's private network.
Image: the operating system to boot.
vCPUs, Memory MiB and Root volume GiB: the machine's fixed
size.
Location (optional): leave empty for any available location.
Initial power state: start the machine right away, or leave it
stopped.
Delete protection: blocks deletion until you turn it off.
SSH public keys: one per line. Ed25519, RSA and ECDSA keys, including
security-key variants, are accepted.
Cloud-init user data (optional): a #cloud-config document that runs
on first boot, for example to install packages or create users.
After creation you can change a machine's name and delete protection. Its
size, image and keys are fixed.
Images
🚧 In development
Picking an image from a list in the dashboard is not available in the preview
yet.
Machines boot from Linux cloud images that Cruma provides. You can't upload
your own images.
The root disk
Each machine has one root disk of the size you chose. It survives shutdowns,
reboots and restarts of the machine, and its size limit is enforced by the
host, so a full disk affects only your machine.
A machine always runs on the host where it was created. If that host fails,
the machine shows Unavailable until the host is back. Catacombs never
starts a second copy elsewhere. There are no snapshots or backups, so keep
your own backups of anything that matters.
Power
The machine's page has these actions:
Power on: start a stopped machine.
Shut down: ask the operating system to shut down cleanly.
Reboot: restart a running machine.
Force off: cut power immediately, like pulling the plug.
Stopping a machine never deletes its disk or releases its address. Every
action is listed under Operation history with its outcome.
SSH access
Each machine gets its own public SSH endpoint, a host name and port. The
machine's page shows a ready-made ssh command with a Copy button once
the machine is placed. Your keys are installed for the image's default user,
for example ubuntu on Ubuntu images.
Serial console
The machine's page streams the serial console output, which is useful for
watching boot messages or finding out why a machine is unreachable. The view
is read-only: nothing you type is sent to the machine.
Inside the zone
A running machine is reachable from other workloads in its zone by name. The
name is lowercased and dots become hyphens, so a machine called API.Database
answers as api-database. Inside the machine, the zone's names resolve the
same way.
Limits
Limit
Value
Machines per zone
32
Machines per organization
256
vCPUs per machine
64
Memory per machine
256 GiB
Root disk per machine
16 TiB
SSH keys per machine
32
Cloud-init user data
64 KiB
Deleting
Delete removes the machine and its root disk permanently. Nothing deletes
a disk automatically: it goes only when you delete the machine. A machine
with delete protection on can't be deleted until you turn protection off.
Private preview
Access, limits and usage
Who can do what
Catacombs resources belong to an organization. Everyone in the organization
works on the same zones, deployments and machines, according to their role:
Role
Access
Organization owner or admin
Everything.
Member with Catacombs admin
Everything.
Member with Catacombs write
View everything and its logs; create, change, power and delete zones, deployments and machines.
Member with Catacombs read
View everything and its logs.
Member with no Catacombs access
Nothing.
Owners and admins grant members a Catacombs level under
Organization → Roles in the dashboard. The Catacombs section only
appears for accounts that have the preview enabled.
🚧 In development
A clear "no access" page is not available in the preview yet.
A member without Catacombs access sees a page saying so, with a way to sign
out and switch accounts.
Per-organization limits on the number of zones and deployments are not available in the preview yet.
Each organization can create a limited number of zones and deployments.
Creating more than the limit is refused with a message naming the limit.
Usage
Catacombs → Usage shows what your organization's workloads consumed:
Billed this window: CPU hours, memory and disk in GiB-hours, and
egress (data sent), for the selected time window. These figures are
closed out hour by hour and don't change afterwards.
So far this hour: the hour in progress. It is provisional until the
hour closes.
Usage over time and By deployment: the same figures as a timeline
and per deployment and zone.
🚧 In development
Showing a just-ended hour as settling, rather than briefly leaving it out, is not available in the preview yet.
An hour that has just ended takes a few minutes to close. Until then it is
shown as settling.
Usage is measured from each workload while it runs: the CPU, memory and
disk it actually uses, and the data it sends.
Private preview
What is Cruma Flow?
🧪 Private preview, in heavy development
Cruma Flow is not generally available yet and is under heavy development. Access is by invitation. This book describes Cruma Flow as it is planned for general availability: features, limits and pricing are subject to change, and parts marked 🚧 In development are not available in the preview yet.
Cruma Flow is a workflow engine built into the Cruma platform. You describe a
process once, as a workflow, and Cruma runs it for you, step by step: calling
web services, waiting, branching, repeating, running work in parallel, and
pausing to ask a person for input or a decision before it carries on.
You build a workflow on a visual canvas, or write the same workflow as YAML.
Both are views of one document, so you can switch between them at any time.
Because a workflow can run scripts on machines you choose, the same engine can
also build, test and deploy your software. With Cruma Catacombs running each
job in its own isolated micro-VM, Flow runs CI/CD pipelines alongside
everything else. See
CI/CD pipelines.
What it's for
Automating calls to web services. Fetch from one API, check the answer,
send something to another, with loops and parallel branches.
Bringing people into a process. A workflow can stop and ask someone to fill
in a form, approve or decline a request, or vote between options, then
continue with their answer.
🚧 Customer-facing journeys. Start a run from your own backend and put its
steps in front of your customers, on a Cruma-hosted page or embedded in yours.
🚧 Building and shipping software. Check out a repository, build and test it
on several platforms at once, and deploy behind approvals.
🚧 Tracking state. Model things that move between named states, such as an
order or a ticket, as state machines.
The pieces
Everything lives under Workflows in the Cruma dashboard,
scoped to the organization you have selected:
Page
What it holds
Templates
Your workflows. Create, edit and start them here.
Instances
Runs: every time a workflow is started, with live progress and history.
Approvals
Decisions and votes waiting on you, and the ones you've made.
Packages
Extra activities, imported from OpenAPI descriptions.
Credentials
Providers and connections that let a workflow call a service as your organization.
State machines 🚧
State machine definitions and their live instances.
Automation 🚧
Schedules and webhooks that start workflows on their own.
Workers 🚧
Your own runners and the API tokens they use.
Statistics 🚧
How many runs, of what, and how they ended.
Pages marked 🚧 are in the sidebar but show a placeholder in the preview.
Who can do what
Your role in the organization decides what you can do:
Members can build, save and start workflows, and cancel or retry runs.
Owners and admins can also manage credentials (providers and connections)
and see the whole team's approvals, not only their own.
Open Workflows → Templates and choose New workflow, or click an
existing one to open it in the designer. Give it a name, build it, and press
Save.
The designer has four tabs:
Tab
What it's for
Canvas
The workflow as a diagram. Add, arrange and edit steps.
Source
The same workflow as editable YAML.
Inputs & outputs
The values a run starts with and the values it reports.
Versions
Every saved version of the workflow.
Steps
A workflow is a list of steps that run top to bottom. Click a + on the
canvas to add a step at that point. There are four kinds:
Activity — does one piece of work: makes an HTTP request, waits, logs a
message, asks someone for approval. Activities are grouped by package in the
step picker; see Activities for the built-in ones.
Conditional — runs its then branch when a condition is true and its
else branch otherwise.
Loop — repeats its body, either a fixed number of times (Count) or for
as long as a condition holds (While).
Parallel — runs two or more branches at the same time. By default the step
finishes when every branch has finished. Turn on Race and the first branch
to finish wins; the others are cancelled.
Click a step to edit it. An activity step shows the inputs that activity
accepts, and the outputs it produces.
Referencing values
Anywhere a step takes a value, you can type it literally or refer to something
the workflow already knows with ${…}:
${name} — a workflow input, or a variable set earlier with
cruma.basic.set.
${alias.field} — an output of an earlier activity step. Give that step a
name in its Output name (as) field first; the step editor then lists the
fields you can use, such as ${page.status_code}.
References can sit inside text, too: "Deployed ${version} to ${environment}".
Conditions
Conditionals and While loops take a condition. Build it with the condition
builder, or switch to Raw and type it:
${page.status_code} == 200
${page.ok} && ${retries} < 3
${tags} contains "urgent"
not ${reply.note} is empty
You can compare with ==, !=, <, <=, >, >=, contains and
not contains, test is empty / is not empty, combine with && (or and),
|| (or or) and ! (or not), and group with parentheses. A reference on
its own, like ${page.ok}, is true when its value is.
Inputs and outputs
On Inputs & outputs, declare the values a run starts with. Each input has a
name, a type (Text, Number, Bool, List, Map or Any), whether it is
required, an optional default, and optionally value choices: either a fixed
list (Static) or options fetched live from a datasource (Dynamic, see
Connections & packages). Whoever starts a run
fills these in. Outputs are declared the same
way and are shown on the run's page.
The YAML source
The Source tab shows the workflow as YAML and accepts edits; changes appear
on the canvas as you type. A small workflow looks like this:
use: an activity id, with as: (optional alias) and with: (its inputs).
if: a condition, with then: and an optional else: list of steps.
loop: with max: and/or while:, and a do: list of steps.
parallel: a list of branches (each a list of steps), with race: true to
let the first branch win.
Saving and versions
Saving checks the whole workflow — every activity exists, every reference
resolves, every condition parses — and shows any problem it finds. Each save
adds a new version, listed on Versions. A run always uses the version it
was started with, so editing a workflow never changes runs already in progress.
Some workflows are marked Managed. They are maintained outside the
designer, so they open read-only.
Repeating over a list
🚧 In development
for_each loops are not available in the preview yet.
A loop can run its body once per item of a list, with the current item bound to
a name. Add parallel: true to run every item at the same time instead of one
after another:
- loop:
    for_each: [linux, windows, macos]
    as: os
    parallel: true
  do:
    - use: cruma.basic.log
      with:
        message: "Testing on ${os}"
Nest two parallel for_each loops to cover every combination, such as each
operating system with each language version, and use a conditional inside the
body to skip a combination. The list is written in the workflow itself.
Workflows inside workflows
🚧 In development
Calling one workflow from another is not available in the preview yet.
use: can name another of your workflows instead of an activity. The called
workflow's inputs are filled from with:, and its declared outputs become the
step's outputs under its as: name:
The called workflow is fixed into the run when it starts, so later edits never
affect a run in progress. A workflow that ends up calling itself, or a missing
required input, is reported at the calling step when you save. Approvals inside
a called workflow work as usual.
Tolerating failures and timeouts
🚧 In development
continue_on_error and enforced step timeouts are not available in the preview yet.
Normally, a failing activity ends the whole run as Failed. Set
continue_on_error: true on an activity step and the run carries on instead;
the failure is recorded, the step produces no outputs, and the run page reports
how many failures were tolerated. A tolerated failure must be looked at:
saving is refused unless a later step reads that step's outcome, so failures
can't be swallowed silently. When a step fails, its failure detail (exit code,
which step failed, the last lines of output) is available to branch on.
A timeout on an activity step fails that step if it runs too long. A whole run
also gets a time limit, so a loop that never ends can't run forever; running out
of time is reported as its own outcome, separate from a failed step.
Expression functions
🚧 In development
Functions in conditions are not available in the preview yet.
Conditions gain functions: success(), failure(), always() and
cancelled() to decide whether a step runs based on how earlier steps went
(for example, upload a test report even though the tests failed), plus
hashFiles(), fromJson, format and startsWith.
Editor support
🚧 In development
Editor support for YAML files is not available in the preview yet.
A published schema for the YAML format gives completion and validation in any
editor that supports YAML schemas, and a language server adds completion of
your organization's own activities and shows the problems Save would.
Private preview
Activities
An activity is a step that does one piece of work. The step picker groups them
by package. Every organization has the built-in packages below; packages you
import yourself appear alongside them (see
Connections & packages).
Basics — cruma.basic
Activity
Inputs
What it does
cruma.basic.log
message
Writes a message to the run's history.
cruma.basic.set
name, value, op
Sets a variable you can then reference as ${name}. Set op to delete to remove it instead.
cruma.basic.delay
duration
Pauses the run, e.g. 1500ms, 30s, 5m, 2h.
cruma.basic.throw
message
Stops the run as failed, with your message.
message can contain references, as in "Order ${order_id} shipped".
HTTP — cruma.http.request
Sends an HTTP request and hands back the response.
Input
url
Required. The address to call.
method
GET (default), POST, PUT, PATCH, DELETE or HEAD.
headers
A map of request headers.
body
Text is sent as-is. Anything else (a map or a list) is sent as JSON, with Content-Type: application/json unless you set your own.
timeout_ms
How long to wait for an answer, in milliseconds. Defaults to 30 seconds.
Output
status_code
The response status, e.g. 200.
ok
true for any 2xx status.
body
The response body as text.
parsed_body
The body parsed as JSON, when it is JSON.
headers
The response headers.
A non-2xx answer does not fail the step: check ${alias.ok} or
${alias.status_code} and decide what to do. Redirects are not followed: a 3xx
comes back as the response, with the target in its Location header. Responses
are limited to 10 MB.
Requests only go to the public Internet. Addresses on private, loopback,
link-local and similar internal ranges are refused, so a workflow cannot reach
into a private network. To call a service that needs a token or API key, attach
a connection — see Connections & packages.
People — cruma.interaction
These activities pause the run until a person answers:
Activity
Asks for
cruma.interaction.ask_input
A filled-in form.
cruma.interaction.approve_anon
Approve or decline, from whoever has the run's link.
cruma.interaction.approve_org_any
Approve or decline, from any one of the named members.
cruma.interaction.approve_org_all
Approve or decline, from every named member.
cruma.interaction.approve_org_atleast
Approve or decline, from at least n of the named members.
cruma.interaction.vote
A choice between options, closed once enough votes are in.
Script, checkout and other pipeline activities are not available in the preview yet.
Running scripts, checking out source code, starting service containers and
reporting status back to your repository are activities too. They're covered
in CI/CD pipelines and
Delivery & governance.
Private preview
People in the loop
Some steps need a person: someone has to fill in a form, approve a request, or
pick between options. The cruma.interaction activities pause the run at that
step, wait for the answer, and carry on with it as the step's outputs.
Every one of them takes a prompt: the question or instructions the person
sees.
Who answers
There are two ways a person reaches a waiting step:
Named members. The approval activities whose ids contain org, and
votes with assignees, are addressed to specific members of your
organization, which you pick in the step editor. Each of them finds the
request under Workflows → Approvals → My pending.
The run's link. When you start a run, Cruma shows a link to that run's
form page. Whoever you hand it to can answer the steps that aren't addressed to
named members: forms, approve_anon approvals and votes without assignees.
The link is shown once, when the run starts, so copy it then. In the preview
it opens in the Cruma dashboard, so the person needs to be signed in.
Answering without a Cruma account
🚧 In development
The public run page is not available in the preview yet.
The run's link opens a public page that needs no sign-in, so the people
answering can be your customers or anyone outside your organization. See
Sharing a run. The same kind of link can be sent by
email to one specific approver, with buttons that approve or decline directly;
the answer is recorded as theirs.
Forms — ask_input
ask_input asks for one or more fields. Each field has a name, a type and
whether it is required, exactly like a workflow input. Once the form is
submitted, each field is available as an output of the step: a step named
address with a city field gives you ${address.city}.
Approvals
All approval activities ask for Approve or Decline, with an optional
note.
Activity
Closes when
Outputs
approve_anon
Someone with the run's link answers.
approved, note
approve_org_any
Any one of the assignees answers.
approved, note, decided_by, decided_by_name
approve_org_all
Every one of the assignees approves, or one declines.
approved, decisions
approve_org_atleast
n of the assignees approve, or so many decline that n is out of reach.
approved, decisions
decisions lists each answer: who gave it, whether they approved, and their
note. Branch on the result with a conditional such as ${signoff.approved}.
Votes — vote
vote offers a list of options and closes once minVotes votes are in. With
assignees, only those members vote; without, anyone with the run's link can.
Its outputs are winner (the option with the most votes), tally (the count per
option), totalVotes and votes (who picked what). When two or more options
tie for first place, there is no winner and winner is empty.
Timeouts
Every interaction takes an optional timeout, in whole seconds. If nobody has
answered in time, the step stops waiting, its timedOut output is true, and
the run continues. Check ${step.timedOut} to handle it, for example by
escalating to someone else.
The Approvals page
Workflows → Approvals collects the requests addressed to you:
My pending — waiting on you. Open one to decide or vote.
My history — what you've decided, and when.
Owners and admins also see Team pending (who in the organization is holding
up which run, and since when) and Team history (every decision, with its
note).
Handing an approval to someone else
🚧 In development
Delegation is not available in the preview yet.
When a named approver can't decide, a member with edit rights can hand their
pending request to someone else, including a person outside Cruma, by creating a
one-time link for it. The link is shown once; copy it when it appears.
Being told something is waiting
🚧 In development
Notifications are not available in the preview yet.
Cruma tells people when an approval or vote is waiting on them, so a run doesn't
stall until somebody happens to look. Notifications about finished and failed
runs are covered in Delivery & governance.
Private preview
Running workflows
Each time a workflow is started it becomes a run, also called an instance.
A run uses the version of the workflow that was current when it started, so
later edits never change it.
Starting a run
On Workflows → Templates, click ▶ Run on a workflow. Fill in its inputs
and press Start.
Cruma then shows the run's link: the page where people answer the run's
forms, approvals and votes. Copy it if someone else needs to answer; it is only
shown here. See People in the loop.
The Instances page
Workflows → Instances lists every run in the organization. Search by
workflow name or run number, filter by status, and sort by newest, oldest, or
Problems first.
Status
Meaning
Running
Working through its steps.
Waiting
Paused: waiting for a person, a delay, or its turn to run.
Succeeded
Finished every step.
Failed
Stopped on an error.
Cancelled
Stopped by someone.
A run that has been running or waiting for more than 15 minutes is marked
Stuck. That may be fine, for instance when it is waiting on an approval, but
it's a good place to start looking when something hasn't finished.
Cancel stops a run that hasn't finished.
Retry sends a failed run back to be picked up again.
Following a run
Click a run to open it. The header shows its status, when it started, and who
started it, along with the inputs it was given and the outputs it reported.
The Canvas tab draws the workflow and marks where the run is. While a run
is live, it follows along. Use ◀ Step and Step ▶ to walk back and forth
through what happened. At any point you can see the values the run held there,
and Jump to live returns to the present.
The Journal tab lists everything the run recorded, in order: each step
started and finished, each message logged, each answer received. When a run
fails, the journal shows where and why.
Sharing a run
🚧 In development
The public run page and the starter's run page are not available in the preview yet.
Whoever started a run gets a clear page for it in the dashboard: the workflow's
name and description, its current status, a timeline of the journey so far,
and any form that is waiting. The run's link opens the same page on its own,
without the dashboard around it and without signing in, so you can hand it to
anyone. Neither page shows the engine's internals; people see the content you
wrote for them. Starting a run from your own backend returns the same link (see
Automation & API).
Embedding a run in your site
🚧 In development
The <cruma-instance> element is not available in the preview yet.
Drop the <cruma-instance> element into your own page to show a run's
current step: the form, approval or vote it's waiting on, and nothing else.
Your page supplies the surrounding context. The element is isolated from your
page's styles and scripts and can be themed from outside. Any web page or HTML
content a workflow shows inside it runs in a locked-down frame that can't touch
or navigate your page. Access works through the run's link, like the public
page.
Statistics
🚧 In development
The Statistics page is not available in the preview yet.
Workflows → Statistics summarizes your organization's runs: how many ended
in each status and which workflows run most, with a switch to cover all the
organizations you belong to.
Private preview
Connections & packages
Credentials
Many services want a token or an API key. Rather than pasting secrets into a
workflow, you store them once under Workflows → Credentials, and workflows
refer to them by name. Secrets are stored encrypted and never appear in a run's
inputs, outputs or journal.
Managing credentials needs the owner or admin role in the organization.
Providers
A provider describes a service and how to authenticate with it. Create one
on the Providers tab, with one of three kinds:
API key — a key sent in a request header. The header is Authorization
unless you name another, such as X-API-Key.
Bearer — a token sent as Authorization: Bearer <token>.
OAuth2 — sign in at the service and let Cruma hold the tokens. Enter the
service's authorization and token endpoints, your client ID and secret, and
its scopes.
Some providers are supplied by Cruma and marked cruma. Deleting a provider
doesn't break connections that already use it; they keep working.
Connections
A connection is one set of credentials for a provider: an actual key, token
or OAuth sign-in. On the Connections tab, choose New connection, pick a
provider and name the connection:
For API key and Bearer providers, paste the secret.
For OAuth2 providers, choose the scopes and press Connect. You are sent to
the service to sign in, and come back to the dashboard once the connection is
made. Cruma refreshes the access token on its own when it expires.
Using a connection in a workflow
Activities that need a credential let you choose one of your connections for
their provider.
For cruma.http.request, add connection: with the connection's name to the
step in the Source tab:
The credential is added to the request when it is sent: as
Authorization: Bearer … for Bearer and OAuth2 connections, or in the
provider's header for API keys. If the step sets that header itself, the
step's value is used instead.
Packages
A package is a set of activities. Besides the built-in ones, you can add your
own from any service that publishes an OpenAPI description. Members can
import and publish packages; deleting a draft needs owner or admin.
Open Workflows → Packages and choose Import from OpenAPI.
Give the description's Spec URL, or paste the document itself. Optionally
choose the Package ID it will be published under.
Press Inspect and review the activities found: one per operation, with
its HTTP method.
Save as draft, open the draft, and Publish. The draft must be valid
first; any problems are listed above the button.
Once published, the package's activities appear in the step picker under its
package ID, ready to use like any other activity.
Value choices from a service
An imported activity that returns a list can also act as a datasource: a
source of choices for a dropdown. In the draft, choose Mark as datasource on
that activity, pick the list in its output, and say which field is the value and
which is the label. Once published, pick it as a Dynamic source under
Value choices on an input or form field, and people get the service's live
list (your playlists, your devices, your projects) instead of a free-text box.
Private preview
Automation & API
Besides ▶ Run, a workflow can be started on a schedule, by a call from
another system, or by your own code.
Schedules
🚧 In development
Schedules can't be managed in the preview yet.
On Workflows → Automation → Schedules, pick a workflow, fill in its inputs,
and set an interval of at least 60 seconds. A run never starts while the
previous run from the same schedule is still going. Schedules can be disabled
and enabled again without deleting them.
Schedules can also follow a calendar, such as "every night at 02:00" in a time
zone you name, with documented behaviour on daylight-saving changes.
Webhooks
🚧 In development
Webhooks can't be managed in the preview yet.
A webhook is a URL that starts a run whenever something POSTs to it. On
Workflows → Automation → Webhooks, pick a workflow and set default inputs;
fields in the JSON body of each call fill in or override them. The URL contains
its own secret and is shown once, when you create the webhook.
Optionally give the webhook a signing secret. Callers must then send
X-Cruma-Signature: sha256=<hex>, the HMAC-SHA256 of the exact request body,
and unsigned or wrongly signed calls are refused without starting a run. A
disabled or deleted webhook answers 404. Each webhook keeps a delivery history,
including refused calls, to help you debug the sender.
Starting runs from your code
🚧 In development
Organization API keys are not available in the preview yet.
Owners and admins create API keys for their organization, each limited to
what it may do: for example, start runs of certain workflows, or only read runs.
Your backend uses a key to start a run and gets back the run's id and its
link. Send your customer to the link, or embed the
run in your own page, and no one has to sign in to Cruma. Keys are shown once
when created and can be revoked at any time.
Private preview
State machines
🚧 In development
Nothing in this chapter is available in the preview yet.
A workflow runs a process from start to finish. A state machine instead
tracks something that sits in one named state at a time and moves between
states when told to: an order going from placed to paid to shipped, or a
ticket from open to in review to closed.
Defining one
On Workflows → State machines, draw the machine in the designer:
the states it can be in;
the states a new instance may start in;
the transitions allowed from each state to the next.
Saving adds a new version, as with workflows.
Instances
Each thing you track is an instance of a machine, with a current state. Open
an instance to see the machine drawn with its current state marked. Only the
states it may move to next can be clicked; click one to move there. Moves that
the definition doesn't allow are refused.
Every move is recorded, so an instance's history shows how it got where it is.
Instances can also be created and moved through the API, which is how other
systems drive them.
Private preview
Runners
The steps of a run are carried out by runners. Cruma operates runners for
the built-in activities and your imported packages, so in the preview there is
nothing to set up.
A runner always connects out to Cruma over HTTPS and asks for work; nothing ever
connects in to it. A runner can therefore sit behind a firewall or NAT, on a
laptop, in a private network, or next to the systems it needs to reach.
Your own runners
🚧 In development
Customer-operated runners are not available in the preview yet.
Run activities on your own machines with the runner SDK, a published Rust
library with documentation and examples. Define a package of activities, attach
a handler to each, and start the worker; the package's activities appear in
your organization's step picker. Your runners only ever receive work for your
own organization's packages. Credentials a step needs are delivered with the
task and kept out of results and logs.
The Workers page
🚧 In development
The Workers page is not available in the preview yet.
Workflows → Workers lists your runners — what each hosts, whether it's
online, and when it was last seen — and manages the API tokens they sign in
with. Each token carries scopes, such as running work or publishing packages, is
shown once when created, and can be revoked.
Choosing where a step runs
🚧 In development
Routing steps to runners by capability is not available in the preview yet.
Runners declare what they can do, such as their operating system and
architecture, and a step can require those capabilities. Each step then runs
only on a runner that has them, so one workflow can build on Linux, Windows and
macOS at once.
Hosted runners on Cruma Catacombs
🚧 In development
Hosted runners are not available in the preview yet.
If you'd rather not run your own runners, Cruma runs jobs for you on
Cruma Catacombs. Each job runs in its own isolated micro virtual machine,
started from a container image you choose, such as node:22 or your own
toolchain image. The micro-VM is created for that one job and discarded when
the job finishes, so nothing carries over between jobs or between
organizations. Hosted runners run Linux. Hosted runner use is subject to your
organization's quota.
Private preview
CI/CD pipelines
🚧 In development
Nothing in this chapter is available in the preview yet.
A pipeline in Cruma Flow is an ordinary workflow. There's no separate pipeline
language: jobs are parallel branches, a build matrix is a for_each loop, and
every script and checkout is a real step you can see, retry, condition and
cancel on its own. Everything else in this book — approvals, connections,
sub-workflows, the run page — works in pipelines too.
Jobs run on runners: your own, or hosted runners on Cruma
Catacombs, where every job gets a fresh, isolated micro-VM.
Getting the code
A checkout step clones a repository at a ref, with options for depth,
submodules and LFS. Each run gets its own repository token, valid for that one
repository and only while the run lasts, instead of a long-lived organization
credential. When a push starts the run, checkout fetches exactly the commit that
was pushed.
Running scripts
A script step runs commands on the runner, with your choice of shell, a working
directory and environment variables. Environment can be set for the whole
workflow, a job or a single step, and a step can pass values on to later steps.
A non-zero exit code fails the step, and its exit code and last lines of output
are kept for the run page and for later steps to branch on.
Jobs and dependencies
Branches of a parallel step are your jobs. A branch can wait for others by
naming them with needs: on its first step:
Here both builds run at once, and package runs when both are done. needs:
can only name sibling branches of the same parallel, a loop of dependencies
is rejected when you save, and needs: can't be combined with race. Jobs run
in waves: a job starts once every job in the wave before it has finished.
Build matrices
A parallel for_each over operating systems,
versions or anything else is a matrix. Nest two for every combination, and skip
one with a conditional in the body.
Passing files between jobs
A step's files are passed on as a workspace: a snapshot of the declared
paths, handed to later steps like any other output. A test job on another
machine can take the build job's workspace and carry on from it. Branches that
start from the same workspace each get their own copy, and workspaces are never
merged back together; jobs hand back results as outputs instead.
When consecutive steps land on the same runner, the workspace is reused from
local disk. If a different runner picks up a step, the result is the same and
only a download is added.
Caching
A step whose inputs and script haven't changed can be skipped and its earlier
result reused, keyed on things like hashFiles() of your lock files. Caches are
isolated per branch, and code from untrusted pull requests can't write entries
that trusted builds later read.
Service containers
A job can start the databases, caches or brokers its tests need. They start
before the job's first step, are checked to be ready before the job relies on
them, pass their address on to the steps, and are torn down after the job, even
when it fails.
Results and artifacts
From the run page, list and download what a run produced, or share an expiring
link to it. Test results in JUnit XML are shown as which tests failed and how
long they took, and which failures are new compared with earlier runs.
Moving from GitHub Actions or Azure Pipelines
Import an existing GitHub Actions or Azure Pipelines YAML file to create a Cruma
Flow workflow from it. The import is one-way: you get a regular workflow to
keep editing, and a report of what converted, what didn't and why. Anything that
doesn't map is reported rather than silently dropped.
Private preview
Delivery & governance
How pipelines connect to your repository, deploy safely, and stay under
control.
Triggers from your repository
🚧 In development
Repository event triggers and status checks are not available in the preview yet.
Pushes and pull requests on GitHub or Azure DevOps start runs, with the ref,
commit, pull request number, author and changed files as typed inputs. Filters
on branches, paths and tags decide which pipelines a change starts. While the
run goes, the commit or pull request shows a pending check, then pass or fail
with a link to the run, so branch protection can require it. One workflow
finishing can also start another, in the same repository or another.
Running by hand, and re-running
🚧 In development
Manual dispatch with access control and re-running failed jobs are not available in the preview yet.
Start a pipeline by hand with typed inputs, such as "deploy version 2.4 to
staging", choosing who may start which pipeline. After a flaky test or a fixed
credential, re-run only the jobs that failed, without repeating the ones that
succeeded.
Pull requests from forks
🚧 In development
The security model for untrusted pull requests is not available in the preview yet.
Pipelines can safely build pull requests from forks, whose code and pipeline
changes you haven't reviewed: such runs are kept away from your secrets, your
trusted caches and runners you haven't allowed for them.
Environments and deployment protection
🚧 In development
Environments are not available in the preview yet.
An environment, such as staging or production, is a named deployment
target with its own credentials. A run that isn't deploying to production can't
reach production's secrets at all. Entering an environment can require
approvals from named reviewers, a waiting period, or that the run comes from
allowed branches or tags. Each environment shows what is deployed there now and
what was deployed before.
Cloud credentials without stored secrets
🚧 In development
Cloud sign-in through OpenID Connect is not available in the preview yet.
Instead of storing cloud keys, a run gets a short-lived OpenID Connect token
from Cruma describing it: organization, workflow, ref, trigger, and whether the
code is trusted. Your AWS, Google Cloud or Azure account exchanges it for
temporary credentials, and can refuse runs it doesn't trust, such as forks.
Concurrency and the merge queue
🚧 In development
Concurrency groups and the merge queue are not available in the preview yet.
Group runs by a key such as the branch, and allow one run per group at a time.
For pull request builds, a new push cancels the run in progress; for
deployments, the new run waits its turn instead. Cancelling actually stops the
work on the runner, and a cancelled run is shown as cancelled, not failed.
A merge queue tests pull requests against each other before they reach a
protected branch, and only merges what passed.
Notifications
🚧 In development
Run notifications are not available in the preview yet.
Cruma tells people about runs, by email or a webhook of your own: when a
pipeline fails, when it recovers, or when a deployment awaits approval, even if
the run failed in a way its own steps couldn't handle.
Retention, quotas and billing
🚧 In development
Retention policies, quotas and usage reporting are not available in the preview yet.
Logs, artifacts and run history are kept for a set time and then removed.
Organizations have limits on concurrent runs and runner minutes. Runner minutes
by runner size, storage and transfer are measured and attributed to the run
that used them.